Perceptual quality assessment and enhancement of visual media using generative priors
Shreshth Saini
PhD student, The University of Texas at Austin
PhD Dissertation Defense · April 2026
Candidate and committee members
 Shreshth Saini
Candidate
UT-Austin
 Prof. Alan C. Bovik (Advisor)
Chair/Member
UT-Austin
 Prof. Joydeep Ghosh
Member
UT-Austin
 Prof. Diana Marculescu
Member
UT-Austin
 Dr. Yan Ye
Member
Alibaba Group US
 Dr. Balu Adsumilli
Member
Google Inc.
Dissertation roadmap
Part I. Perceptual quality assessment
- Beyond8Bits and BrightRate (reviewed)
HDR-UGC data and quality model. CVPR 2026, WACV 2026 - LGDM (reviewed)
Zero-shot image quality from diffusion priors. ICML 2025 - HDR-Q
Multimodal LLM for HDR video. CVPR 2026
Part II. Generative enhancement
- LumaFlux
SDR to HDR conversion. Preprint, 2026 - Rectified-CFG++
Guidance for rectified flow models. NeurIPS 2025 - Future directions
Progress review recap
Beyond8Bits and LGDM
HDR-UGC benchmarks, and generative priors for perceptual quality
Beyond8Bits and BrightRate (review)
BrightRate is the first HDR-aware blind VQA model. It fuses HDR, CONTRIQUE and CLIP features with a temporal difference module.
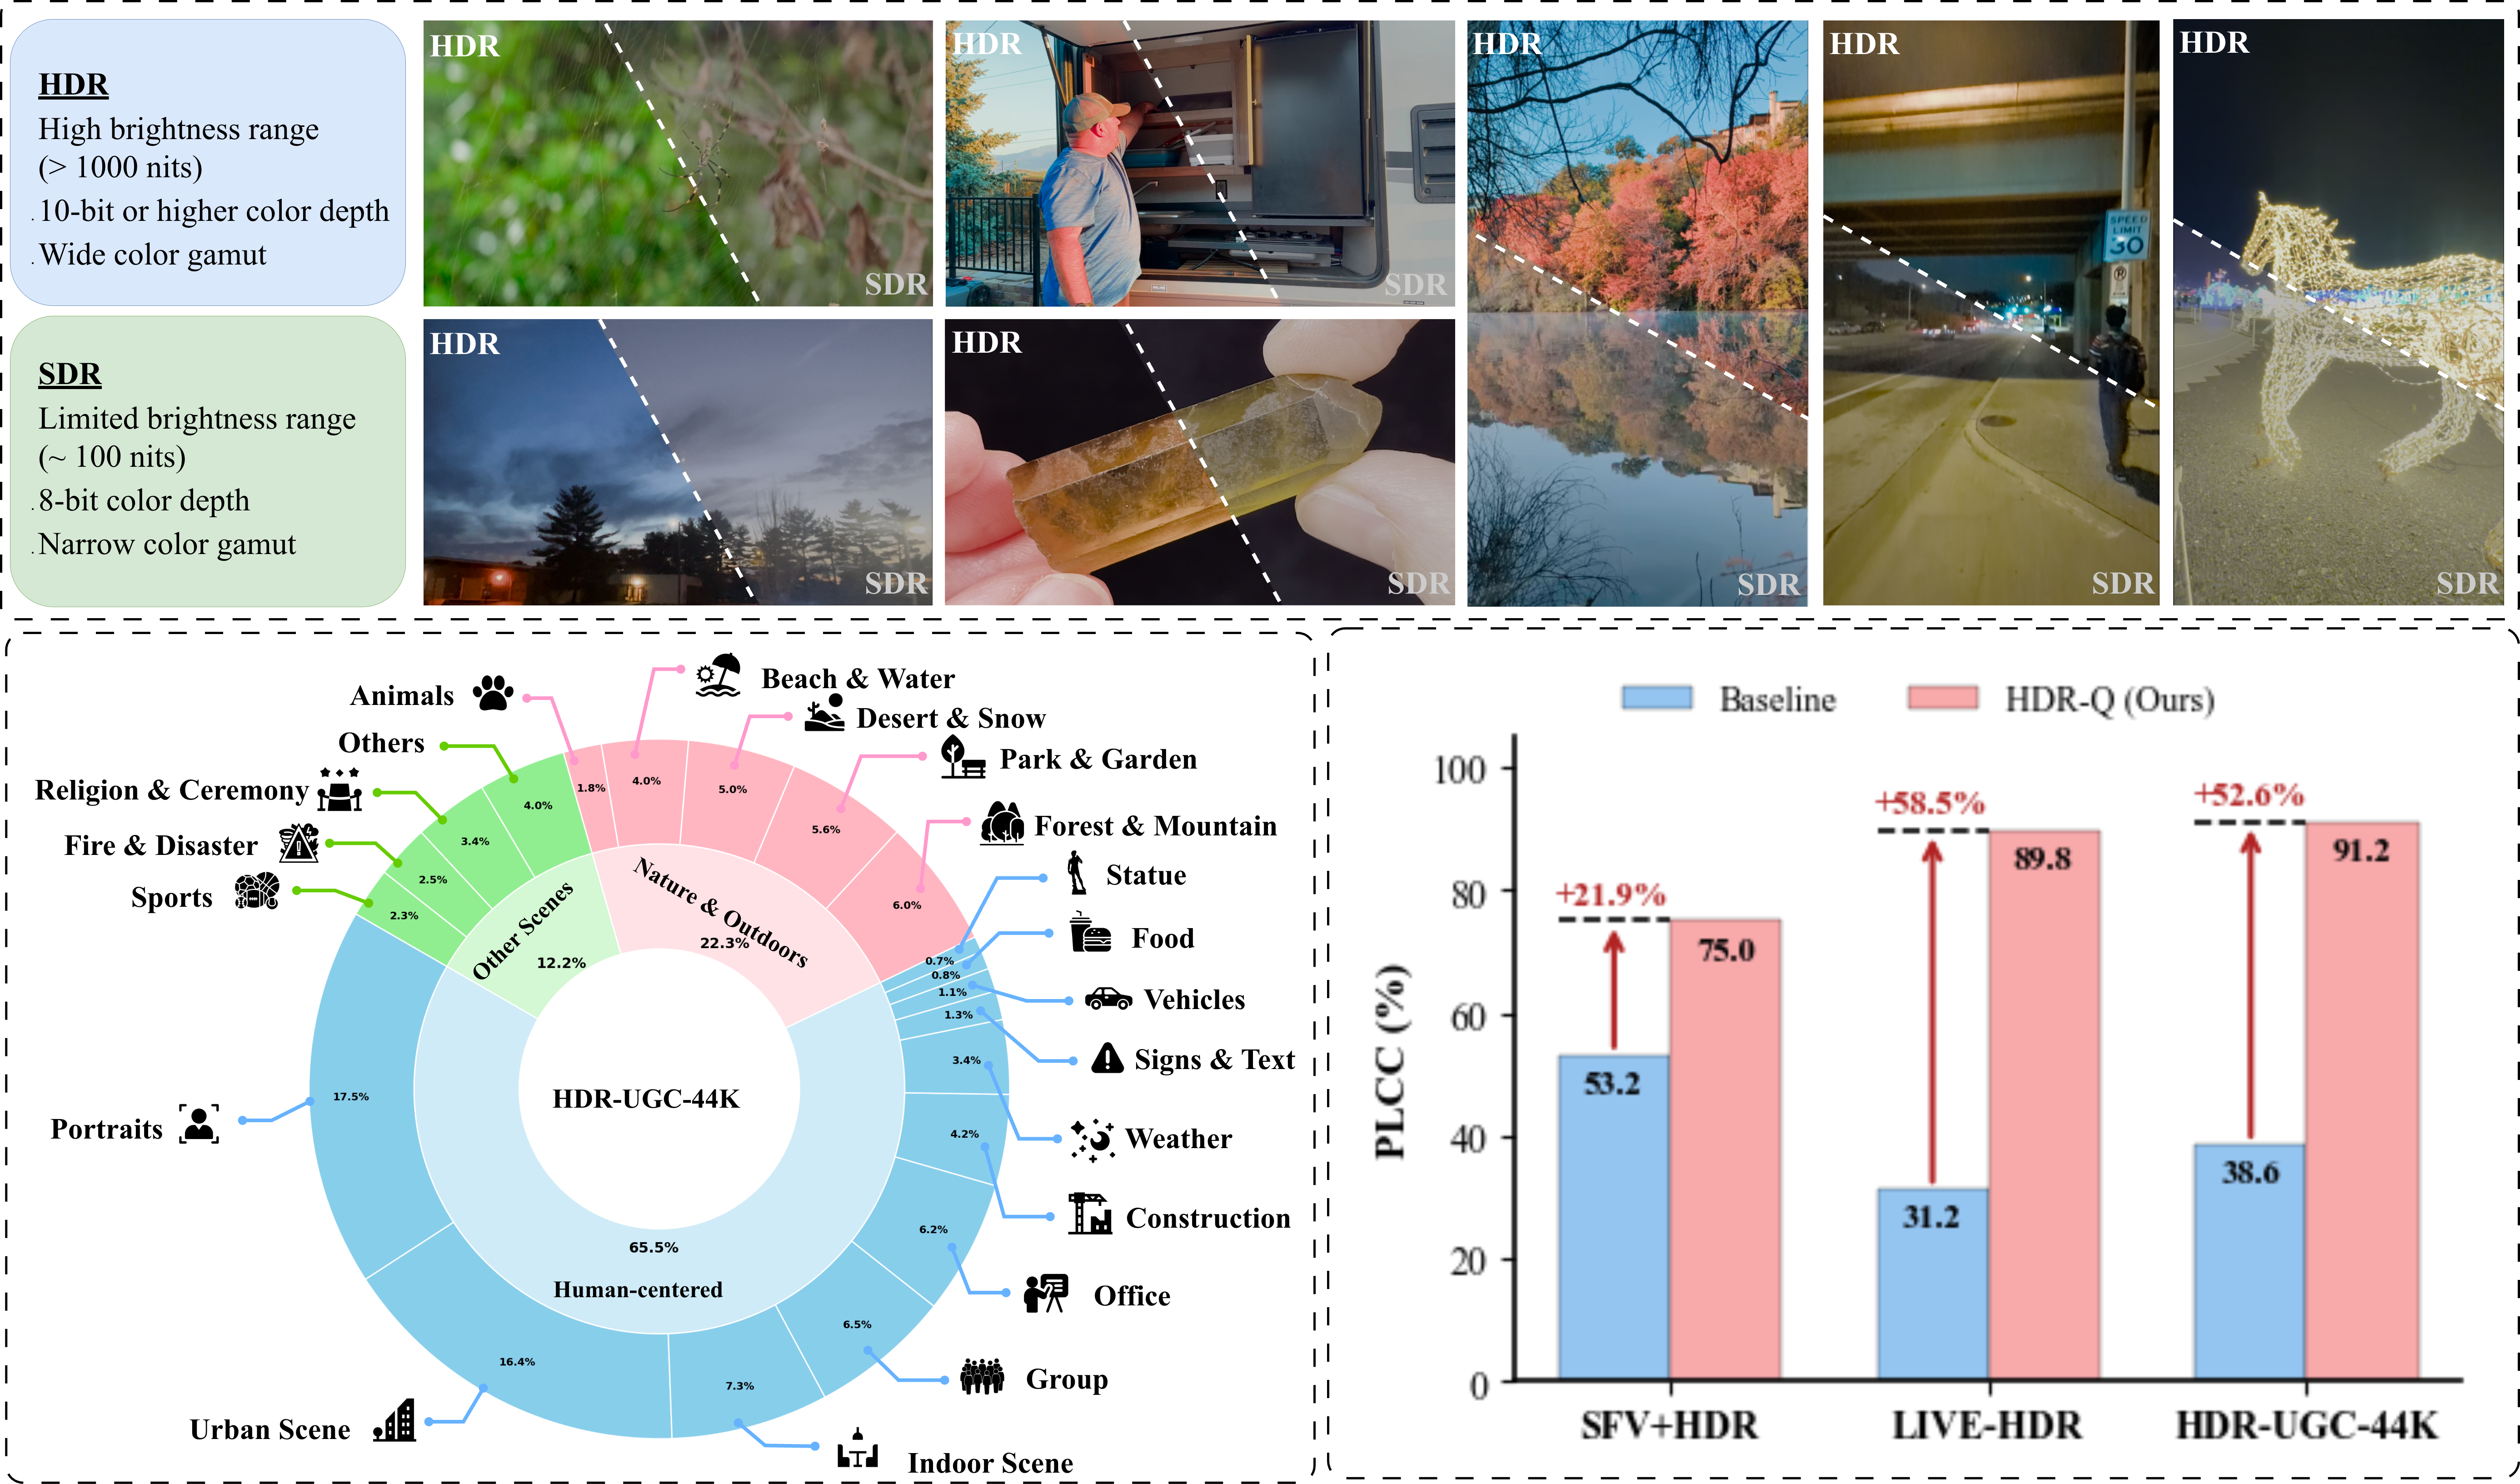
HDR vs SDR gap, Beyond8Bits diversity, and HDR-Q improvements over baselines
Beyond8Bits: Saini et al., CVPR 2026. BrightRate: Saini et al., WACV 2026 (Oral, Best Student Paper Award).
Earlier: HIDRO-VQA, Saini, Saha, Bovik, WACV 2024. CHUG, Saini et al., ICIP 2025.
LGDM turns a diffusion model into a zero-shot quality judge (review)
- Pretrained diffusion models already encode a perceptual manifold
- Perceptual manifold guidance (PMG) keeps sampling on it
- Features from many timesteps and U-Net layers of SD v1.5, no fine-tuning
PMG guides denoising toward perceptually consistent manifold regions
Saini, Liao, Ye, Bovik. LGDM: Latent Guidance in Diffusion Models for Perceptual Evaluations. ICML 2025.
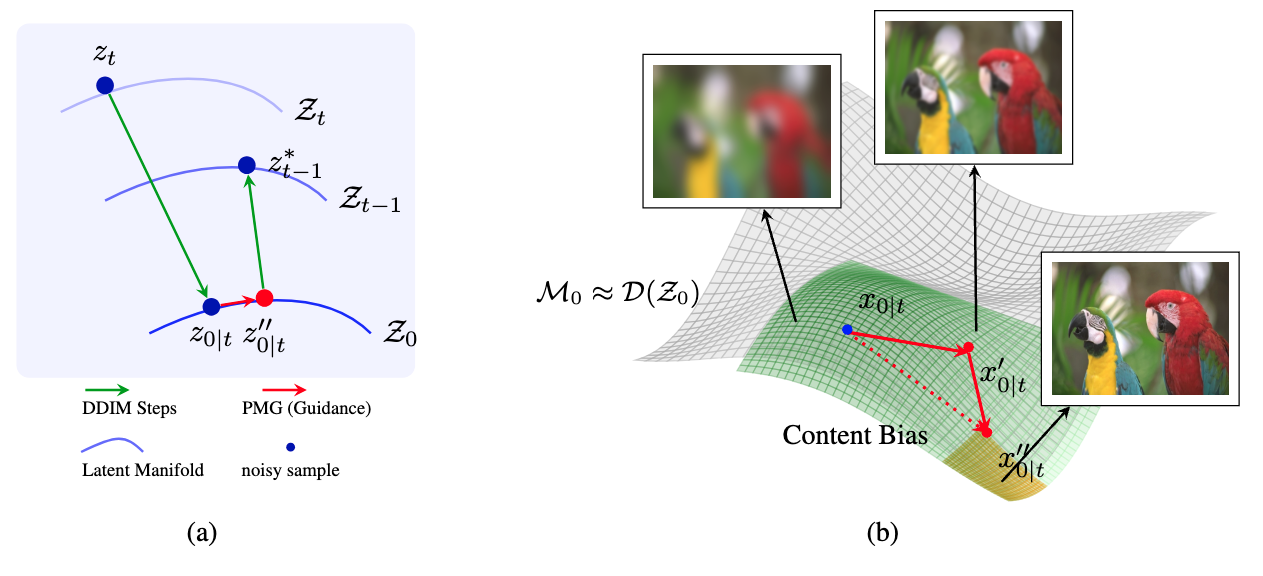
Perceptual manifold guidance, on-manifold quality-aware sampling
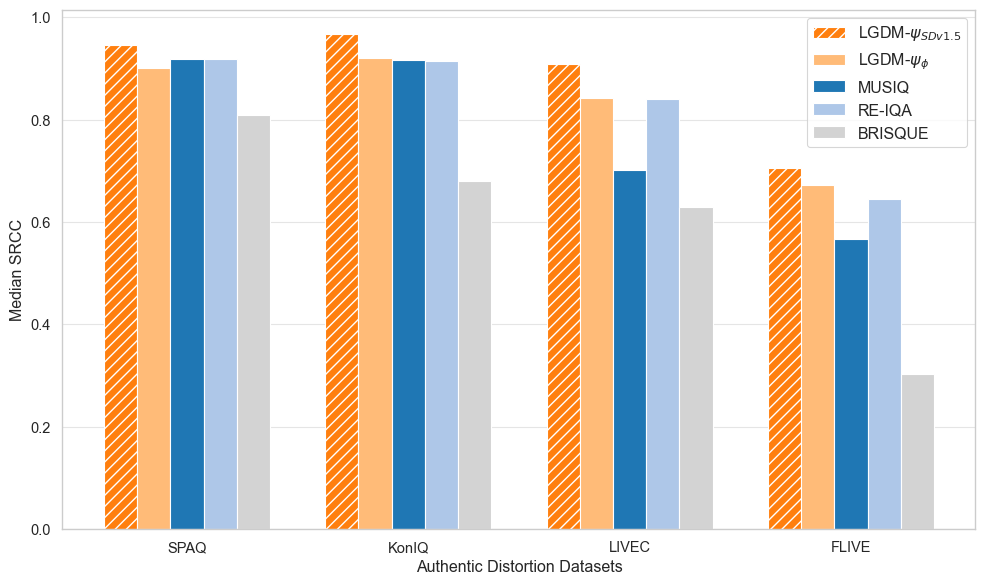
LGDM has the best median SRCC across authentic-distortion benchmarks
Five contributions
A pipeline from perception to generation for HDR visual media
Dashed boxes were covered at the progress review. Today's talk is the three on the right.
Both parts use generative models as evaluators and as enhancers of visual quality.
Part 1 of 3 · Perceptual quality assessment
HDR-Q, a multimodal LLM for HDR video quality
Can a model see HDR video and reason about its quality?
Saini, Chen, Birkbeck, Wang, Adsumilli, Bovik. Seeing Beyond 8bits: Subjective and Objective Quality Assessment of HDR-UGC Videos. CVPR 2026.
HDR is a different signal space
Every modern phone captures 10-bit HDR by default
- HDR10 is 10-bit, the BT.2020 wide gamut and the perceptual quantizer (PQ)
- Peaks of 1000 nits or more, against roughly 100 for SDR
- New artifacts: highlight clipping, near-black banding, color blooming, exposure flicker
SigLIP and CLIP take 8-bit sRGB, so they are structurally blind to these.
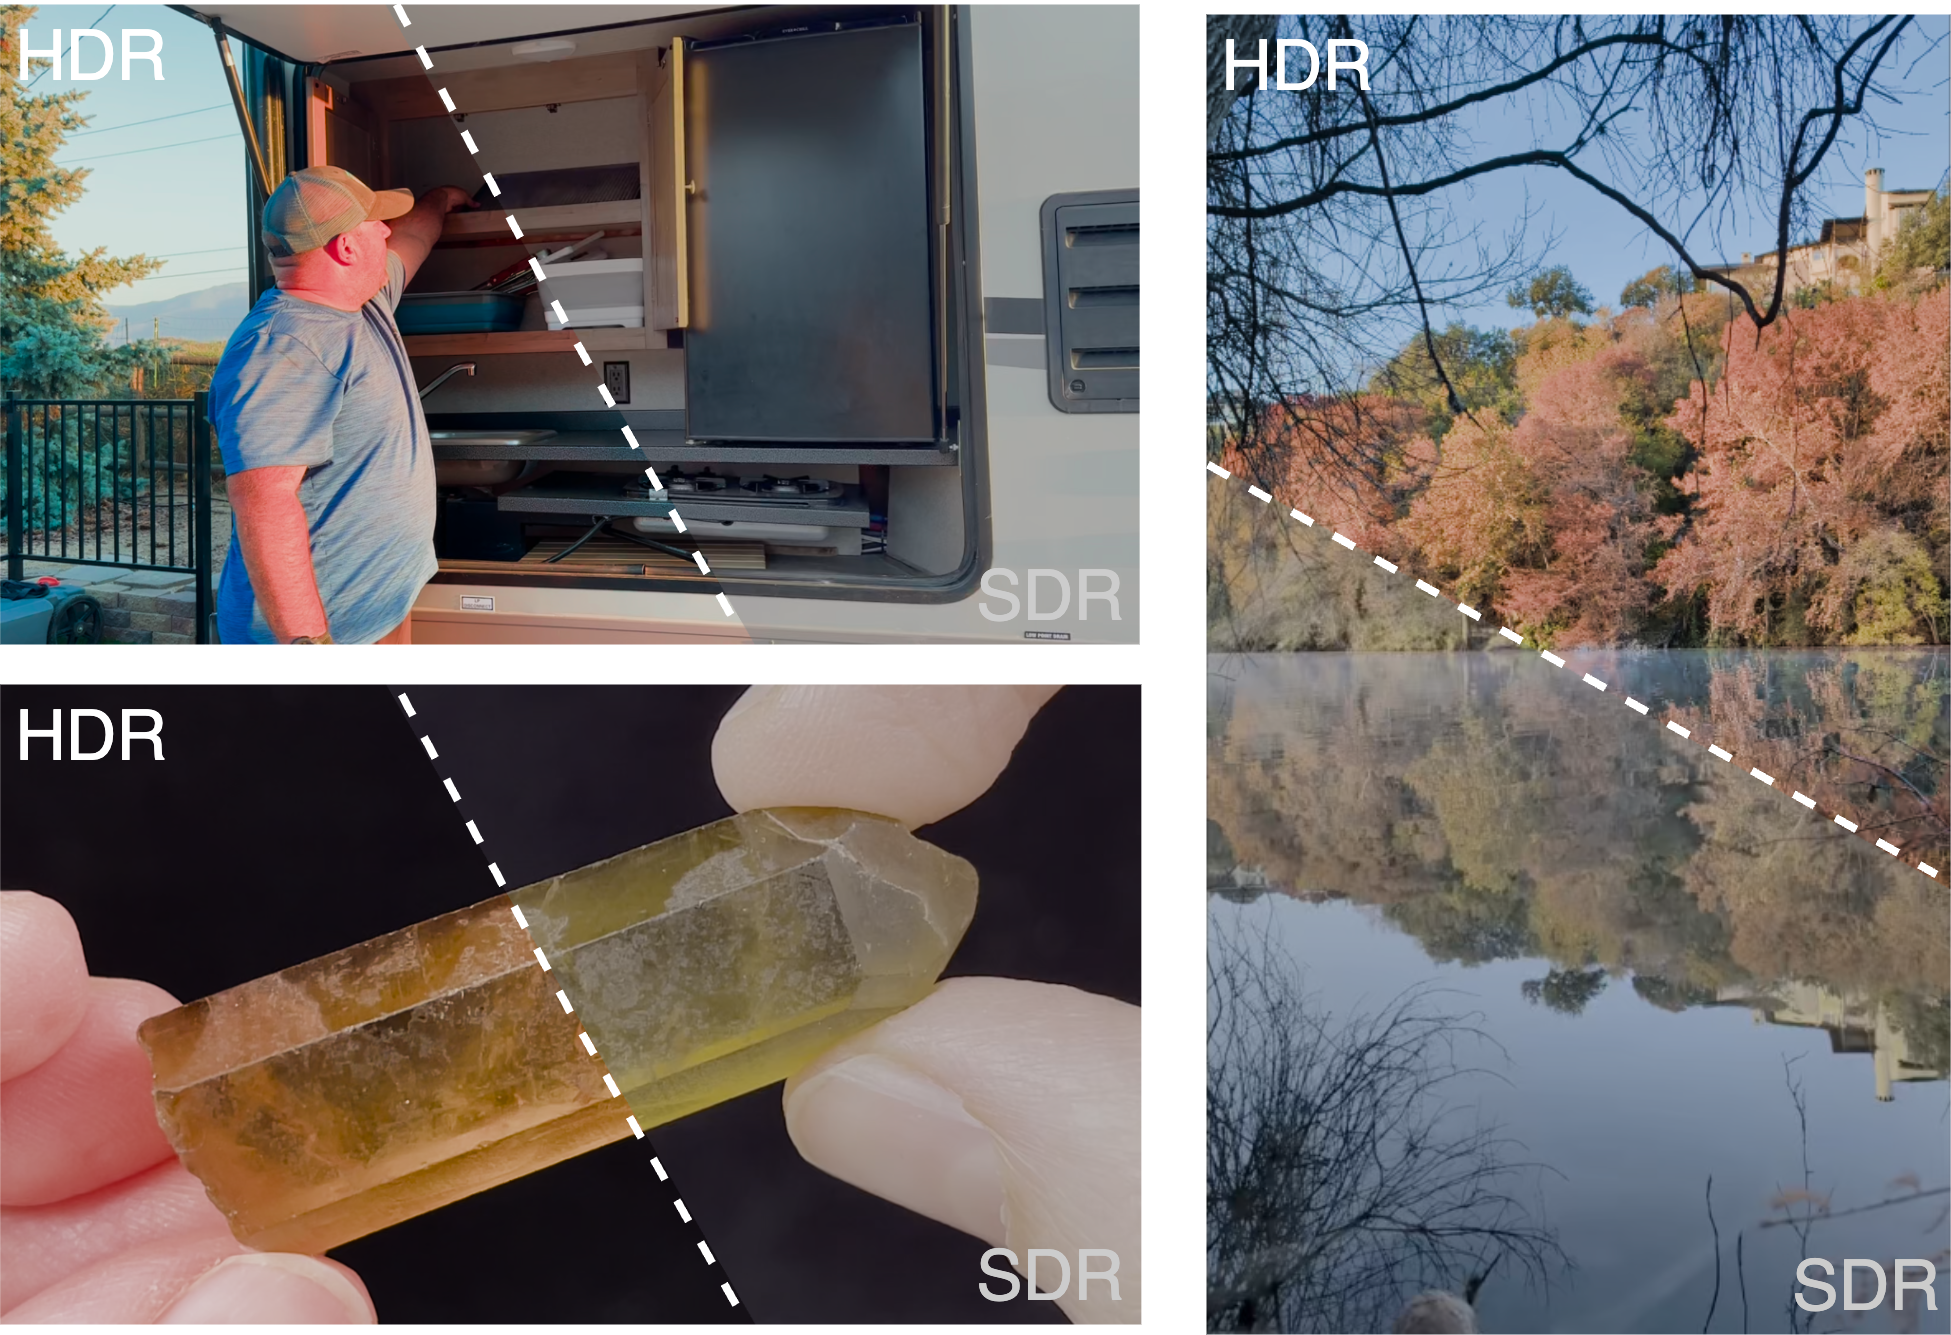
HDR keeps luminance and color detail that SDR collapses
Where current methods break
| Method family | HDR input | Perceptual grounding | Reasoning | Continuous MOS | Interpretable | SROCC |
|---|---|---|---|---|---|---|
| Classical (BRISQUE, VMAF) | no | no | no | yes | no | 0.41 |
| Deep VQA (FastVQA, DOVER) | no | partial | no | yes | no | 0.51 |
| HDR-specific (HIDRO-VQA) | yes | yes | no | yes | no | 0.85 |
| MLLM-VQA (Q-Insight, DeQA) | no | no | yes | partial | yes | 0.52 |
| HDR-Q (ours) | yes | yes | yes | yes | yes | 0.92 |
Only HDR-Q has HDR-aware perception, a continuous score and readable reasoning.
Three obstacles
- O1. SDR-pretrained vision encoders. They cannot represent 10-bit PQ.
- O2. A continuous score from tokens. The LLM writes text, and we need a MOS.
- O3. Modality neglect. Group relative policy optimization (GRPO) ignores the HDR tokens.
With GRPO, adding the HDR input lowers SROCC from 0.891 to 0.875.
HDR-Q architecture
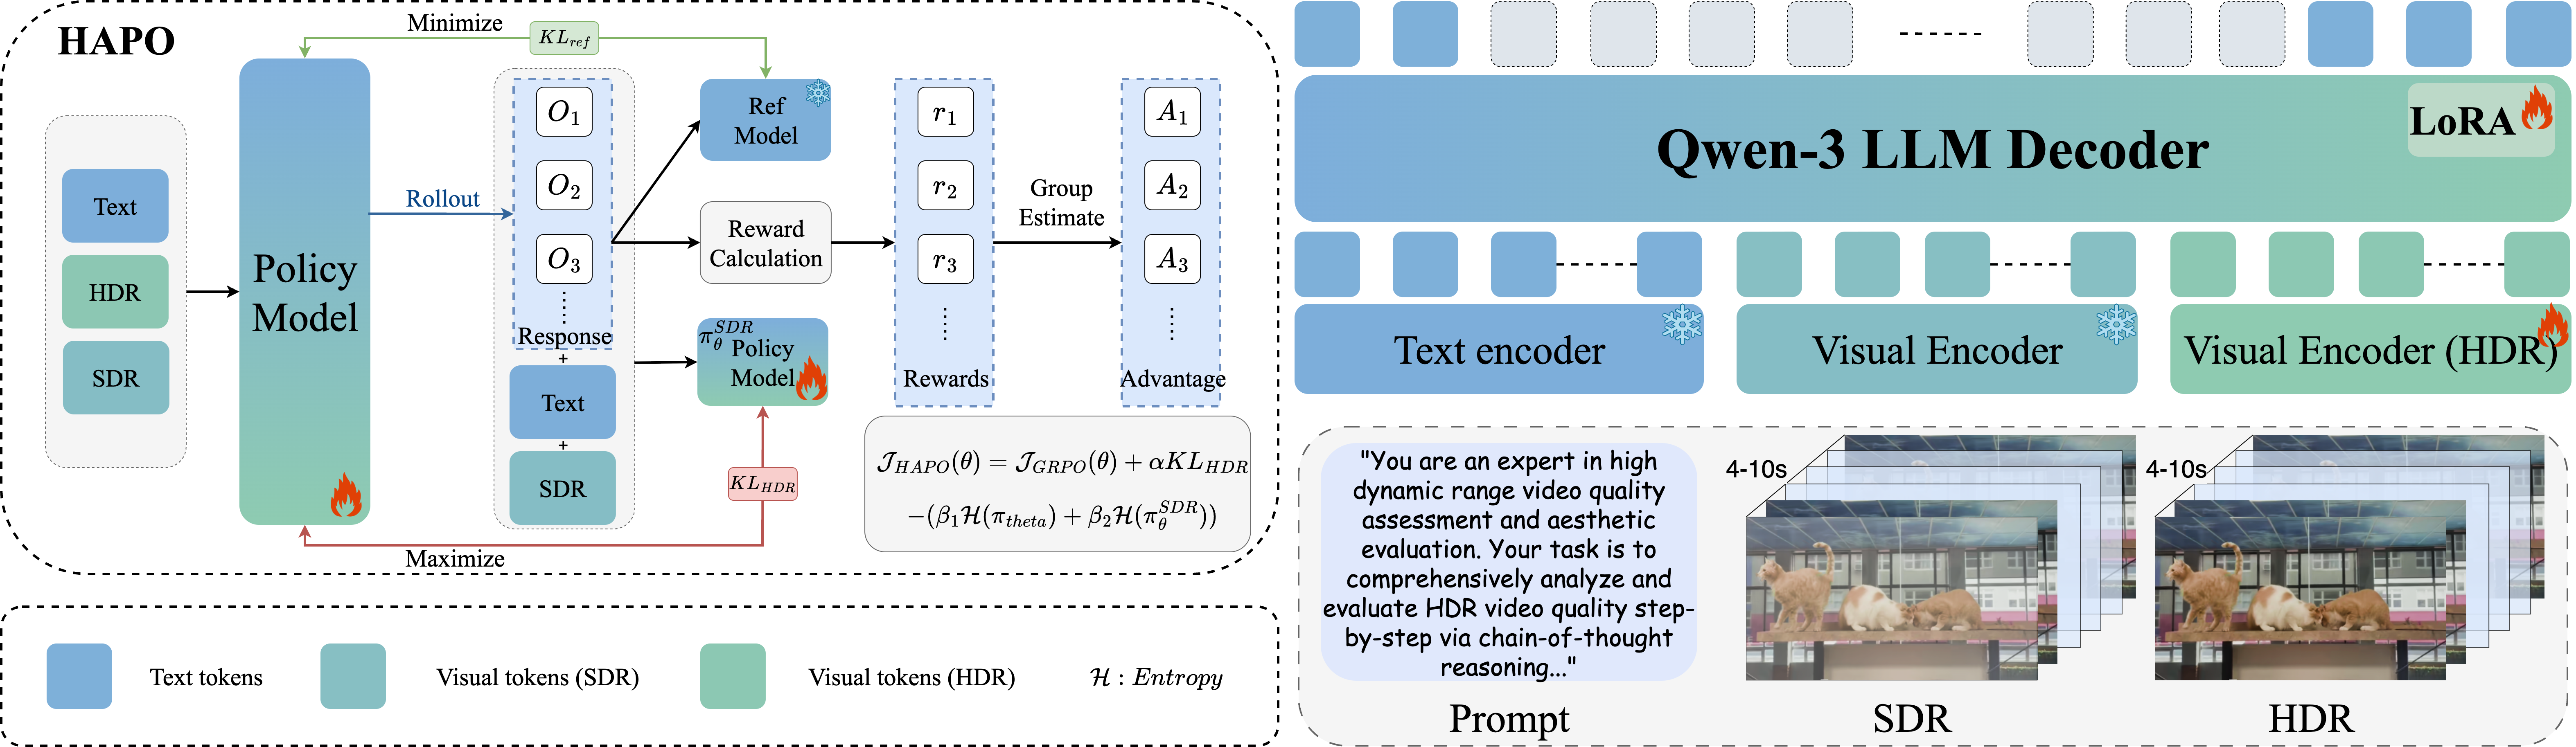
HDR-aware encoder (O1)
SigLIP-2 fine-tuned contrastively on native 10-bit PQ, with separate HDR and SDR pathways.
Structured output (O2)
Ovis2.5 (9B), rank-4 LoRA. <think> reasoning, then an <answer> score. Gaussian reward, σ = 3.
HAPO training (O3)
HDR-aware policy optimization, built from a contrastive KL, dual entropy and an entropy-weighted advantage.
Adding the HDR input made GRPO worse
We call it modality neglect
- GRPO weights all tokens equally
- The model can shortcut through the text context
- Familiar SDR features win over unfamiliar HDR ones
HAPO rewards different outputs for HDR and SDR inputs.
The contrastive KL at the core of HAPO
If the model ignores HDR, its HDR and SDR outputs match and DKL ≈ 0. So we maximize it.
Maximized with coefficient γ = 0.5 in the HAPO objective
Formal guarantee
Mutual information between the output and the HDR content is lower-bounded, so the policy must use HDR.
The HAPO objective
GRPO plus three mechanisms that keep the policy on the HDR input
| Term | What it does | Setting |
|---|---|---|
| Ã | Entropy-weighted advantage (HEW) | λHEW = 0.3 |
| β DKL | Reference KL, for stability | β = 0.02 |
| + γ KHDR | Contrastive KL, for HDR grounding | γ = 0.5 |
| − Hdual | Dual entropy, against collapse | η1 = 0.01, η2 = 0.05 |
HDR-Q reaches 0.921 SROCC on Beyond8Bits
| Method | SROCC ↑ | PLCC ↑ | RMSE ↓ |
|---|---|---|---|
| BRISQUE | 0.410 | 0.469 | 11.70 |
| CONTRIQUE | 0.625 | 0.605 | 15.02 |
| CONVIQT | 0.799 | 0.810 | 8.48 |
| HIDRO-VQA | 0.851 | 0.878 | 6.09 |
| Q-Insight (best MLLM) | 0.517 | 0.562 | 20.78 |
| HDR-Q (SDR only) | 0.891 | 0.890 | 7.42 |
| HDR-Q (full) | 0.921 | 0.912 | 5.16 |
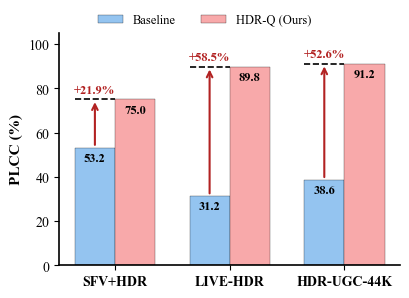
Zero-shot generalization, with no fine-tuning on the target datasets
HDR-Q names real artifacts where the baseline invents them
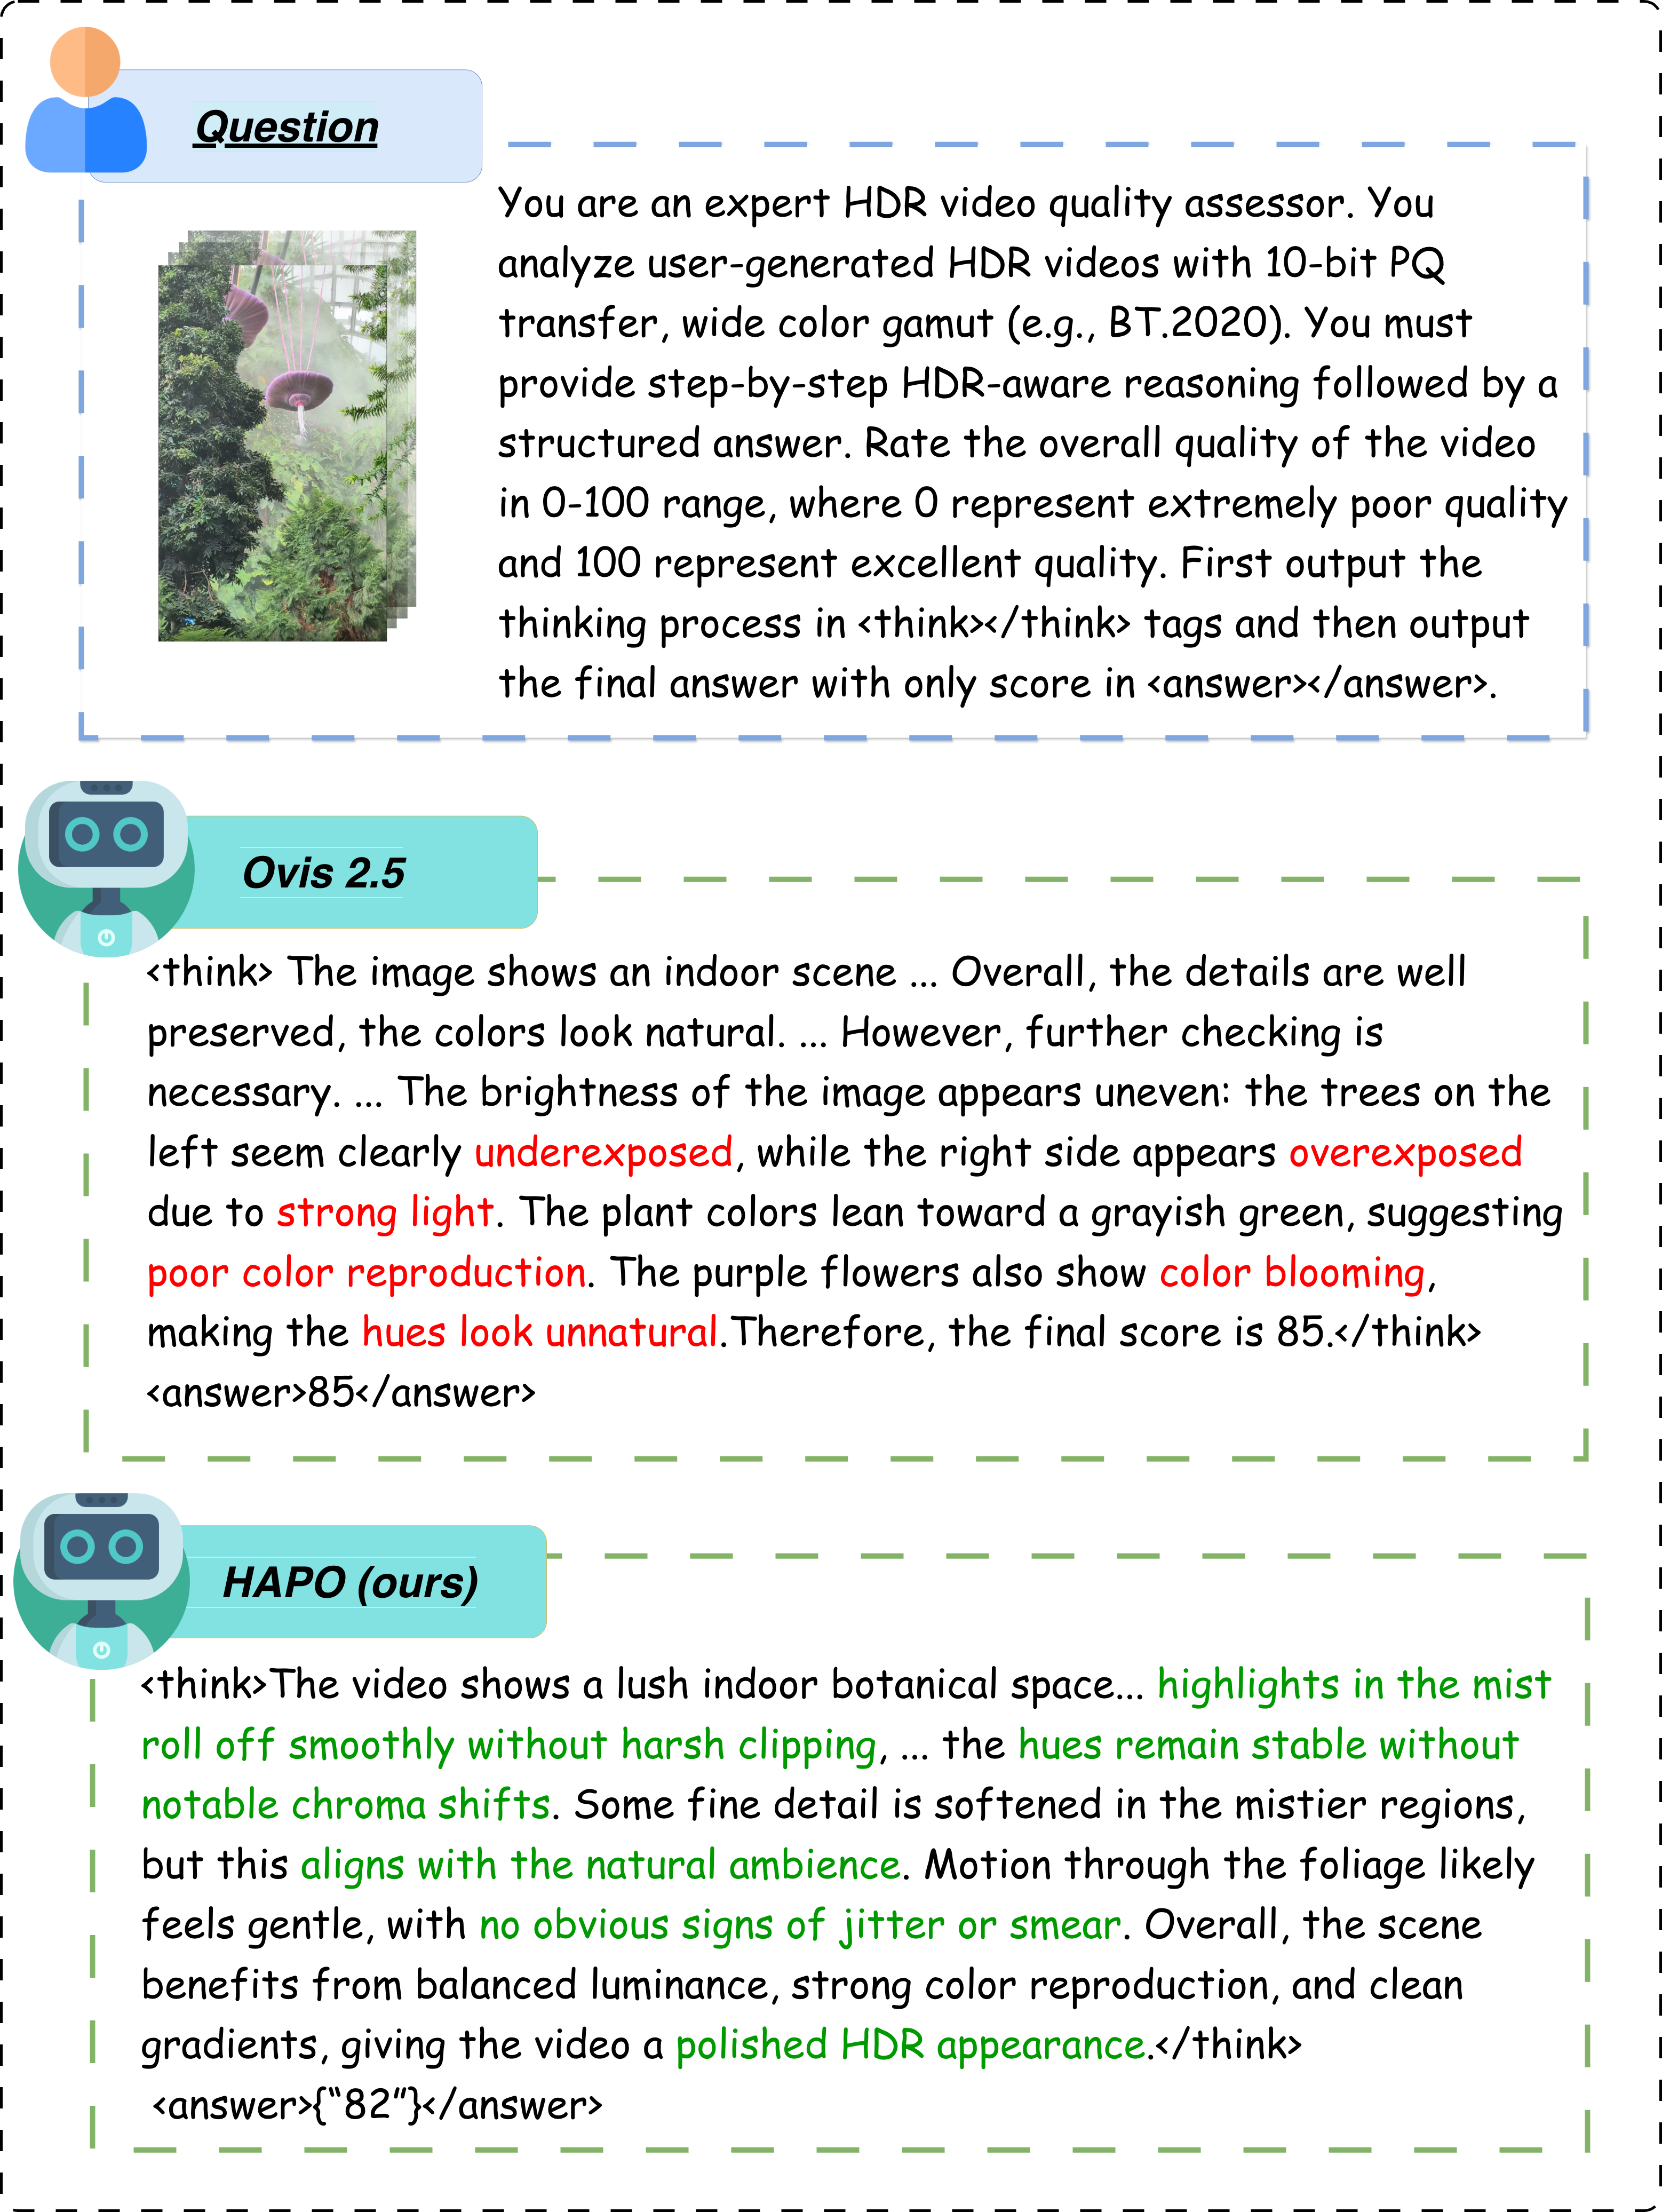
- Ovis2.5 baseline hallucinates underexposure, color blooming and unnatural hues.
- HDR-Q reports what is there: highlights that roll off without clipping, stable hues, no jitter or smear.
Same prompt to both models. HDR-Q identifies true HDR artifacts (highlight preservation, banding, color fidelity).
The contrastive KL matters most
| Variant | SROCC | RMSE | Token entropy |
|---|---|---|---|
| GRPO baseline | 0.81 | 10.73 | 0.20 |
| + HDR encoder | 0.83 | 8.96 | 0.24 |
| HAPO without contrastive KL | 0.86 | 7.10 | 0.29 |
| HAPO without HEW | 0.88 | 6.11 | 0.27 |
| HAPO without dual entropy | 0.91 | 5.82 | 0.26 |
| HDR-Q (full) | 0.92 | 5.15 | 0.33 |
- Contrastive KL. 0.92 falls to 0.86 without it, the largest drop.
- HEW. 0.92 falls to 0.88. It sends gradient to quality-relevant tokens.
- Dual entropy. 0.92 falls to 0.91. It prevents collapse.
- HDR encoder. Lifts the GRPO baseline from 0.81 to 0.83.
Token entropy rises from 0.20 to 0.33, so the model keeps exploring.
Takeaways
- The first MLLM for HDR video quality. 0.92 SROCC against 0.52 for prior MLLMs.
- HAPO fixes modality neglect. Three ablated mechanisms, one mutual-information guarantee.
- It generalizes zero-shot. 0.908 on LIVE-HDR and 0.725 on SFV+HDR with no fine-tuning.
Saini, Chen, Birkbeck, Wang, Adsumilli, Bovik. Seeing Beyond 8bits: Subjective and Objective Quality Assessment of HDR-UGC Videos. CVPR 2026.
Part 2 of 3 · Generative enhancement
LumaFlux: Structure-Aware SDR-to-HDR Conversion with Monotone Luminance Flows
Can a frozen image generator turn 8-bit SDR into faithful 10-bit HDR?
Saini, Gedik, Birkbeck, Wang, Adsumilli and Bovik, arXiv:2604.02787
The question
Can a frozen generative prior be steered by the physics of the SDR frame?
- Inverse tone mapping (ITM) turns 8-bit SDR into 10-bit HDR.
- Our HDR is PQ (Perceptual Quantizer) in BT.2020, mastered at 1,000 nits.
- Image models know scenes, but nothing about nits or gamuts.
- So LumaFlux freezes the model and conditions it on measurements.
What gets lost, on three frames
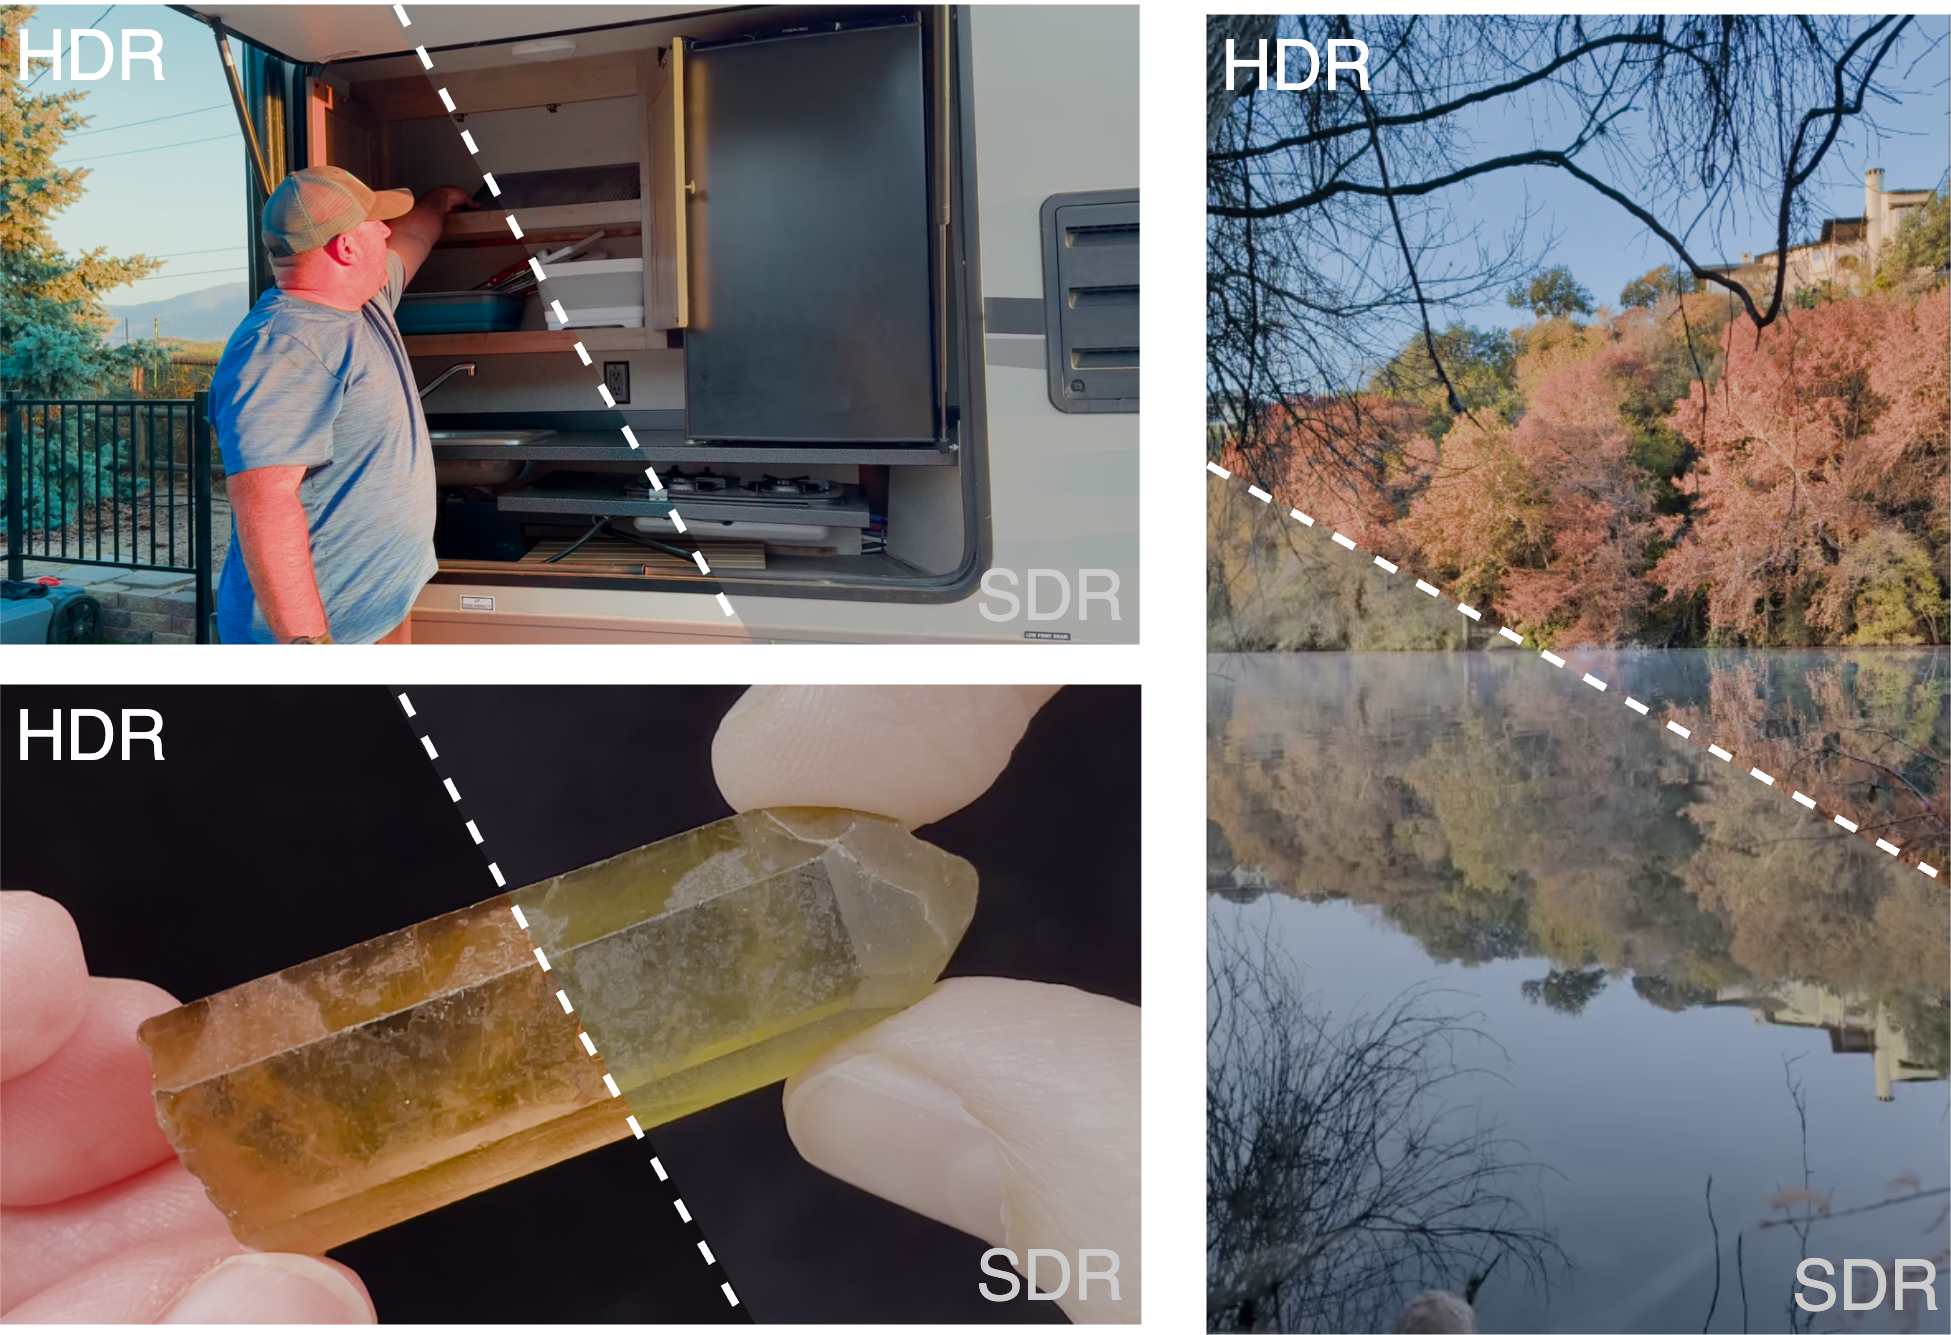
Each frame is split: HDR in the upper-left triangle, SDR in the lower-right.
- Shadows. Detail inside the fridge is gone.
- Color. Foliage and sky lose saturation.
- Highlights. The crystal's speculars merge into one white patch.
The map is many-to-one, so a converter has to invent what is missing.
From the SDR input space to the HDR output space
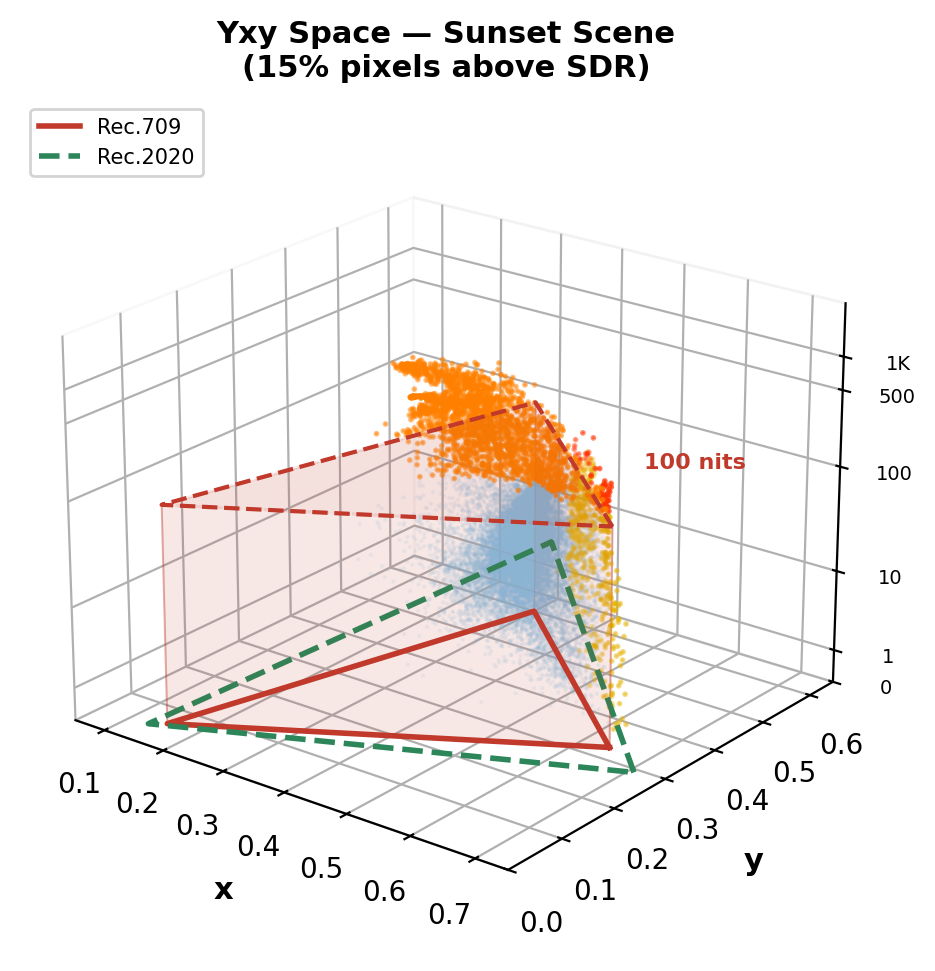
A sunset clip. The shaded box is the SDR volume; orange points are HDR pixels above the 100-nit plane.
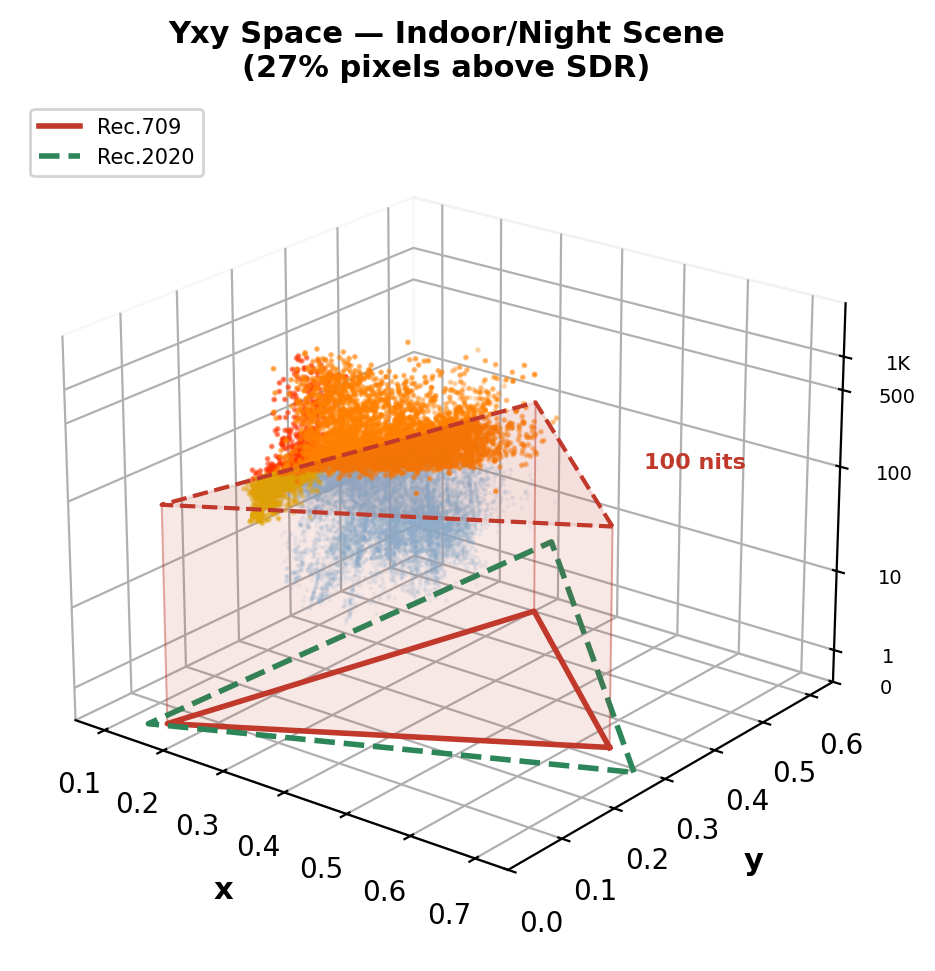
An indoor night clip. It has a larger share of pixels above the SDR ceiling than the sunset.
The input lives inside the box. The output has to fill the volume around it, without moving what is already right.
Prior work and where it fails
Analytic operators
Reinhard, BT.2446
One fixed curve per scene. Clipped highlights stay clipped.
Learned converters
HDRTVNet++, FMNet, ITM-LUT, KUNet
Excellent in domain, tied to the degradation they trained on.
Generative priors
LEDiff, X2HDR
A real structural prior, but color and tone drift.
LumaFlux keeps the prior and pins down the physics.
A frozen FLUX transformer, steered by what the frame measures
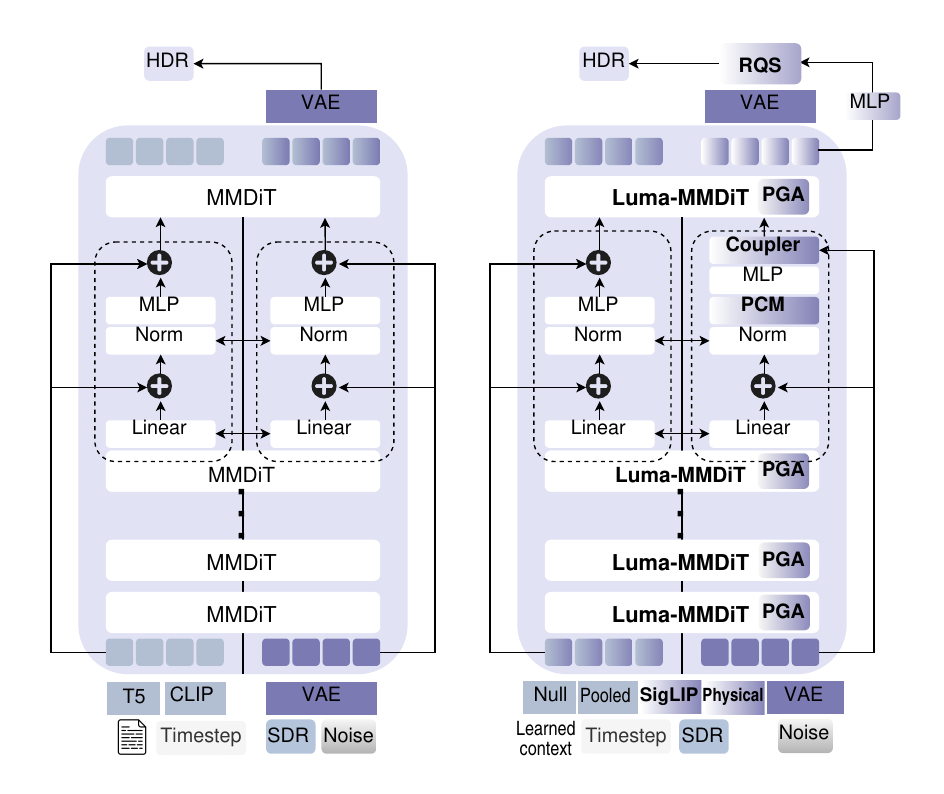
Left: direct adaptation, driven by a text prompt. Right: frozen blocks plus PGA, PCM, a coupler and the RQS decoder.
- Physically-Guided Adaptation (PGA) gates a low-rank update with luminance and gradients.
- Perceptual Cross-Modulation (PCM) adds scene context from SigLIP.
- Rational-Quadratic Spline (RQS) decoder calibrates luma and keeps its ordering.
- Bridge. SDR latent to HDR latent in 8 Euler steps.
PGA is a LoRA told what it is looking at
Tphys per token, from luminance, gradient, saturation; g in ℝ16 and r (FFT energy, 8 bands) per frame.
- Rank 8, image-token value projection only.
- A physical gate sets adaptation per token and head.
- Constant gains instead of Ψ cost 0.81 dB and 6.09 ΔEITP.
Scene context from SigLIP, and a monotone tone decoder
PCM sets one scale and shift per frame from pooled SigLIP tokens.
- 25 spline parameters per frame, all positive.
- So decoded luma keeps its ordering.
- Removing it costs 9.69 dB.
8 bins: 8 widths ξ, 8 heights η, 9 knot slopes s, from a 21.9K-parameter head that starts at identity.
A 314,396-pair corpus of user and professional video
| Source | What it adds |
|---|---|
| CHUG (Saini et al., ICIP 2025) | 856 user-generated references, 846 train and 10 reserved |
| LIVE-TMHDR | 40 references with 120 expert-graded SDR clips |
| HDRTV1K | 1,235 native training pairs |
| Sol Levante | one HDR10 master |
| Synthetic SDR | 307,752 rows: eight tone-mapping operators, three CRF settings |
| Mix | 171,384 user-generated (UGC), 143,012 professional (PGC) |
| Training | Setting |
|---|---|
| Loss | flow matching, two L1 terms in linear light, spline smoothness |
| Crops | 5122, 1,024 tokens |
| Schedule | 100,000 steps, global batch 16, learning rate 2e-4 |
| Trained | 71.3M parameters; the backbone stays frozen |
| In-domain checkpoint | HDRTV1K only, 50,000 steps, adapters only |
LumaFlux is best in every column of the primary track
LumaEval synthetic track, 100 held-out frames under eight tone-mapping degradations, one scoring stack
| Method | PU21-PSNR ↑ | PU21-SSIM ↑ | ΔEITP ↓ | HDR-LPIPS ↓ | HDR-VDP-3 ↑ | FR-HIDRO ↓ |
|---|---|---|---|---|---|---|
| BT.2446c | 23.74 | 0.8291 | 61.60 | 0.307 | 5.611 | 0.753 |
| Reinhard operator | 23.62 | 0.8286 | 61.76 | 0.295 | 5.726 | 0.753 |
| HDRTVNet++ | 23.03 | 0.8192 | 66.67 | 0.328 | 5.417 | 0.703 |
| FMNet | 22.86 | 0.8176 | 67.92 | 0.330 | 5.412 | 0.724 |
| ITM-LUT | 22.92 | 0.8142 | 67.41 | 0.315 | 5.496 | 0.761 |
| VAE + RQS (control) | 18.54 | 0.7647 | 111.67 | 0.381 | 3.673 | 0.924 |
| LumaFlux (ours) | 24.23 | 0.8294 | 56.54 | 0.269 | 5.812 | 0.631 |
FR-HIDROVQA is a full-reference distance on HIDRO-VQA features (Saini et al., WACV 2024).
Three scenes, every method
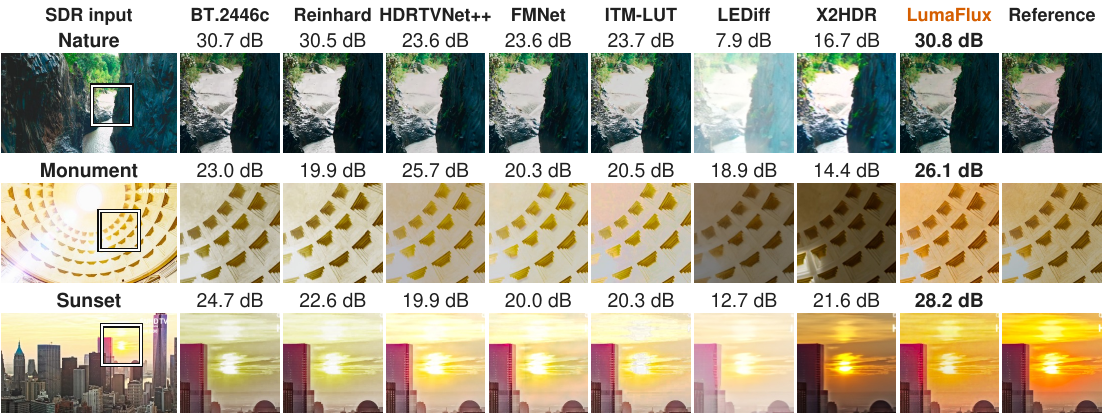
SDR input with the patch box, then each method's crop. Full-frame PU21-PSNR is above each crop, best in bold.
On Sunset LumaFlux reaches 28.22 dB; the next best, BT.2446c, reaches 24.67.
In the ablation, the tone decoder matters most
| Row | Configuration | PSNR (Δ vs g) | ΔEITP (Δ vs g) |
|---|---|---|---|
| (c) | PGA, no spectral gate | 28.57 (−0.62) | 33.48 (+5.66) |
| (d) | PGA + spectral gate | 29.56 (+0.37) | 28.38 (+0.57) |
| (f) | full design, seed-0 run 1 | 28.67 (−0.52) | 35.00 (+7.18) |
| (g) | full design, seed-0 run 2 (ours) | 29.19 (ref.) | 27.81 (ref.) |
| (h) | full, linear spline instead of RQS | 28.74 (−0.45) | 32.16 (+4.35) |
| (i) | full, no RQS decoder | 19.50 (−9.69) | 261.78 (+233.97) |
| (j) | full, no timestep-layer modulation | 28.38 (−0.81) | 33.90 (+6.09) |
- No RQS, row (i): PSNR falls 9.69 dB.
- A linear spline, row (h), costs 0.45 dB.
- The spectral gate, (c) to (d), adds 0.98 dB.
- Rows (f) and (g) are one configuration, 0.52 dB apart, so smaller gaps are noise.
Video without temporal training
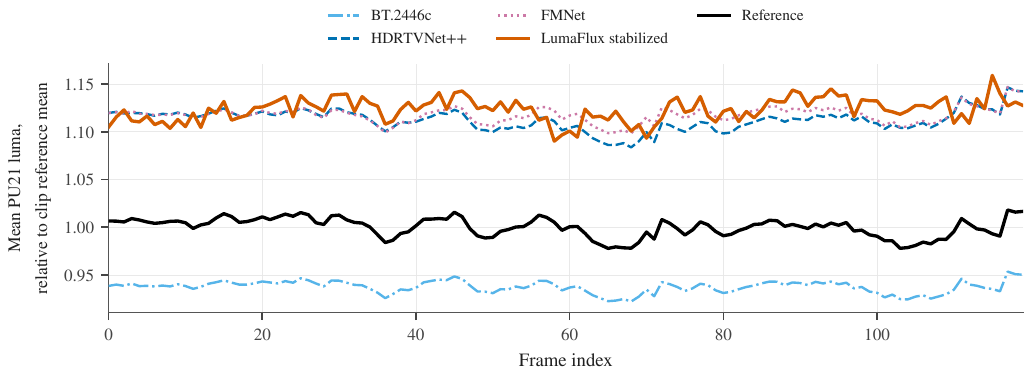
Per-frame mean PU21 luma, first 120 frames of four clips, relative to each reference mean. Stabilized LumaFlux only.
| Method | Bonfire | 02c3 | 055e | 0392 | 0237 | Mean |
|---|---|---|---|---|---|---|
| Reference | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 |
| BT.2446c | 7.813 | 1.411 | 0.450 | 0.063 | 0.124 | 1.972 |
| HDRTVNet++ | 3.005 | 0.207 | 0.147 | 0.442 | 1.257 | 1.012 |
| FMNet | 3.853 | 0.202 | 0.074 | 0.579 | 1.124 | 1.166 |
| LumaFlux | 1.992 | 0.691 | 2.500 | 0.968 | 0.569 | 1.344 |
| LumaFlux + stabilization | 2.109 | 0.469 | 1.676 | 0.879 | 0.362 | 1.099 |
- Draw the bridge noise once and reuse it for every frame.
- Smooth the spline with an EMA, θ̄f = 0.8 θ̄f−1 + 0.2 θf.
- Signed excess flicker falls 53.3%, from 547.4 to 255.5 (×103).
- Raw flicker energy stays within 3.27% of the reference.
What holds up, and what falls short
Holds up under compression
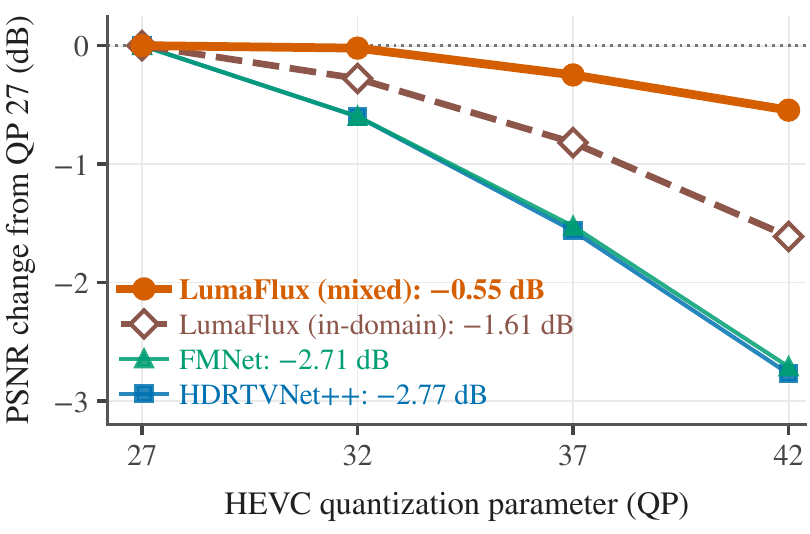
PSNR change from QP 27 on the 117 HDRTV1K pairs, HEVC intra coding of the SDR input. Flatter is better.
From QP 27 to 42 the main model loses 0.55 dB; HDRTVNet++ loses 2.77 and FMNet 2.71.
Falls short
| LumaFlux | Reference point | |
|---|---|---|
| HDRTV1K, in-domain checkpoint | 33.34 dB | 38.60 dB, best published |
| HDRTV1K, main model zero-shot | 27.52 dB | same protocol |
| Mean ITP chroma, five scenes | 60.65 | 49.80, the references |
| Seconds per 1080p frame | 5.282 | 0.367 to 1.708, single pass |
- The VAE is an SDR codec, so heavily clipped detail stays lost.
- Colors run oversaturated, and in-domain CNNs stay ahead on HDRTV1K.
Takeaways
- Measurements can steer a frozen flow transformer.
0.57% of weights trained, no prompt. - A monotone tone field keeps luminance ordering.
Worth 9.69 dB. - One checkpoint leads every primary metric and does video.
24.23 dB on LumaEval, flicker down 53.3%.
Saini et al., arXiv:2604.02787 · github.com/shreshthsaini/LumaFlux · shreshthsaini.github.io/LumaFlux
Next, Rectified-CFG++ (Saini et al., NeurIPS 2025) changes how guidance is applied.
Part 3 of 3 · Generative guidance
Rectified-CFG++, geometry-aware flow guidance
How do we guide a rectified flow model without pushing it off its manifold?
Saini, Gupta and Bovik, NeurIPS 2025
The question
Why does guidance break on the best image generators?
Flux, SD3 and SD3.5 sample a rectified flow with a deterministic ODE. Classifier-free guidance (CFG) pushes their trajectories off the manifold, and nothing brings them back.
Why we need guidance at all
Without it, a flow model gives generic images that only loosely match the prompt
- No guidance. Dark, muddy, weak on the prompt.
- CFG. Follows the prompt, but oversaturates.
- Ours. Follows the prompt and stays natural.
CFG was built for stochastic diffusion samplers (DDPM, SDXL). Flow models sample a deterministic ODE.
Flux-dev, same prompt and seed
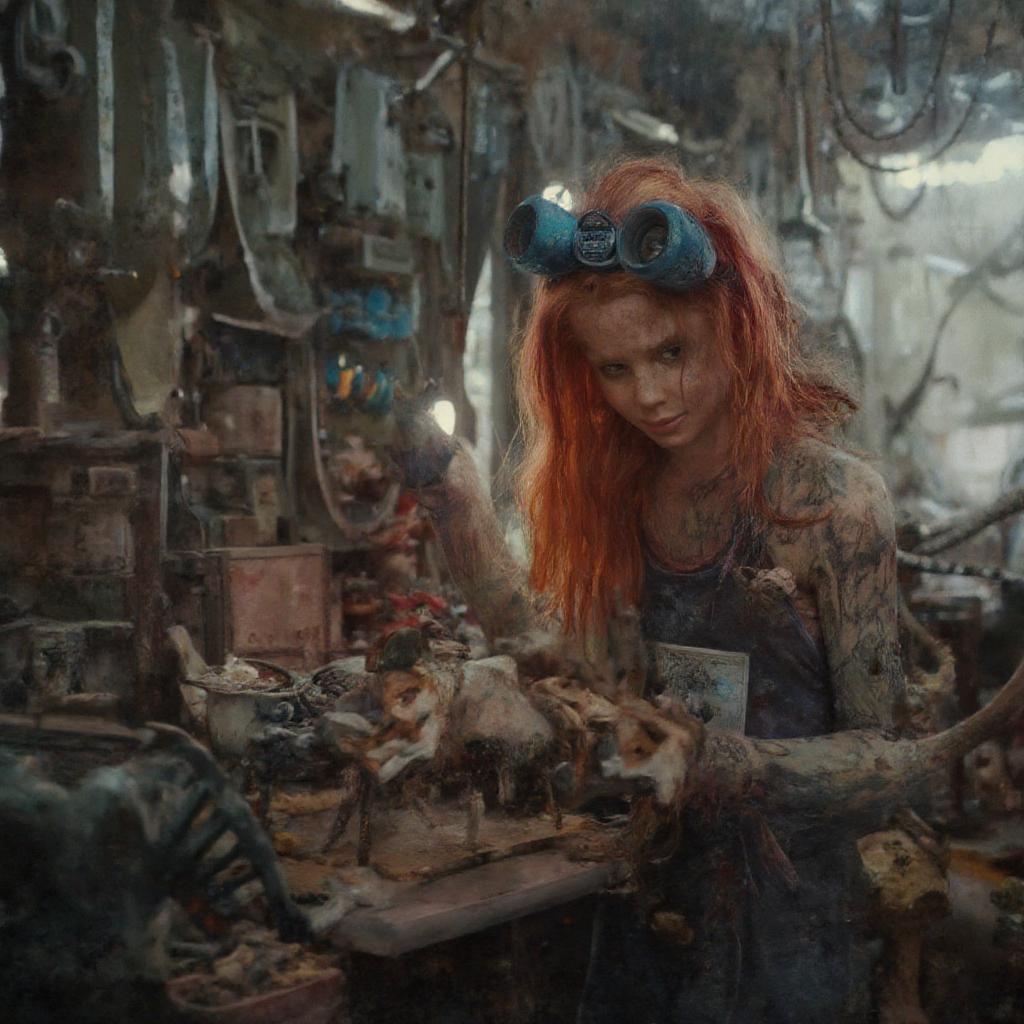
No guidance
CFG, ω = 3.5
Ours, λ = 3.5
SD3.5, same prompt and seed
No guidance
CFG, ω = 3.5
Ours, λ = 3
Why CFG works on diffusion but breaks on flows
Same extrapolation trick, different samplers
| Sampler | One step | After CFG overshoots |
|---|---|---|
| Diffusion SDE DDPM, SDXL |
dx = [f(x,t) − g(t)2 ∇log pt(x)] dt + g(t) dw̄ DDPM: xt−1 = μθ(xt, t) + σt z, z ~ N(0, I) |
Fresh noise at every step pulls the sample back toward the data |
| Flow ODE Flux, SD3, SD3.5 |
dx = vθ(x, t) dt | Nothing pulls it back. Step t+1 starts off the manifold and the error compounds |
So we need guidance designed for deterministic ODE samplers.
Why CFG fails and how we fix it, geometrically
Ideal flow. The velocity stays tangent to the manifold.
CFG. With ω > 1 the step lands off the manifold, for good.
Ours. Predict a midpoint with vc, evaluate guidance there, add a bounded correction.
Left to right: ideal flow, CFG, Rectified-CFG++. The step-by-step version is in the backup slides.
Extrapolation versus interpolation
This one difference explains why CFG fails and Rectified-CFG++ works
CFG extrapolates (ω > 1)
ω = 3 means three times the distance from vu to vc, into territory the model never learned.
Ours interpolates (0 ≤ α ≤ 1)
The base is always vc, on the manifold. The correction α(t) Δvmid is bounded and decays to 0 near the data.
CFG runs ω from 3 to 9. Ours keeps α between 0 and 1.
The two algorithms side by side
Highlighted lines are what changes
Standard CFG
for t = T down to 1:
  vc = vθ(xt, t, y)
  vu = vθ(xt, t, ∅)
  v̂ = vu + ω(vc − vu)        extrapolation
  xt−1 = xt + Δt v̂
2 network evaluations (NFE) per step. Nothing corrects the overshoot.
Rectified-CFG++
for t = T down to 1:
  vc = vθ(xt, t, y)
  x̃mid = xt + (Δt/2) vc           predictor
  vcmid = vθ(x̃mid, t − Δt/2, y)
  vumid = vθ(x̃mid, t − Δt/2, ∅)
  v̂ = vc + α(t)(vcmid − vumid)    interpolation
  xt−1 = xt + Δt v̂
3 NFE per step. α(t) = λ(1−t)γ decays to 0 near the data.
The base is always vc, guidance comes from the midpoint, and α(t) fades out.
Theoretical guarantees
Four mild assumptions give three bounds. No earlier guidance method has any.
| Result | Bound | In words |
|---|---|---|
| Lemma 1 guidance stability |
‖Δvθt−Δt/2 − Δvθt(xt)‖ ≤ L Vmax Δt | Guidance at the midpoint differs from guidance at the current point by only O(Δt) |
| Proposition 1 bounded single-step perturbation |
‖x̂t−1 − x̃t−1‖ ≤ α(t) B Δt | Deviation from the conditional path is set by α(t), so it vanishes near the data |
| Proposition 2 distributional deviation |
DKL(p̂0 ‖ p0) ≤ Cs (B + L Vmax Δt) ∫α(τ) dτ | Total KL divergence is set by the integrated guidance ∫α(τ)dτ |
One knob, ∫α(τ)dτ, controls how far the output can drift.
CFG versus ours, property by property
Lemma 2, manifold-faithful corrector
Distance to the manifold is bounded by the training error ε alone.
Integrated guidance
4 to 16× lower KL divergence
| Property | CFG | Ours |
|---|---|---|
| Per-step perturbation | (ω−1) B Δt constant, never vanishes | α(t) B Δt goes to 0 near the data |
| Manifold distance | Unbounded errors accumulate | O(ε Δt) training error only |
| Integrated guidance | ω−1 ≈ 2 to 8 | λ/(γ+1) ≈ 0.5 |
| KL(p̂0 ‖ p0) | O(ω−1) | O(0.5) |
| Late-step behavior | Same ω everywhere, destroys fine detail | α(t) goes to 0, preserves fine detail |
| Guidance evaluation | At the current point (possibly off the manifold) | At the predicted midpoint (on the manifold) |
Watching the artifacts grow, or not
CFG
ω = 2.5
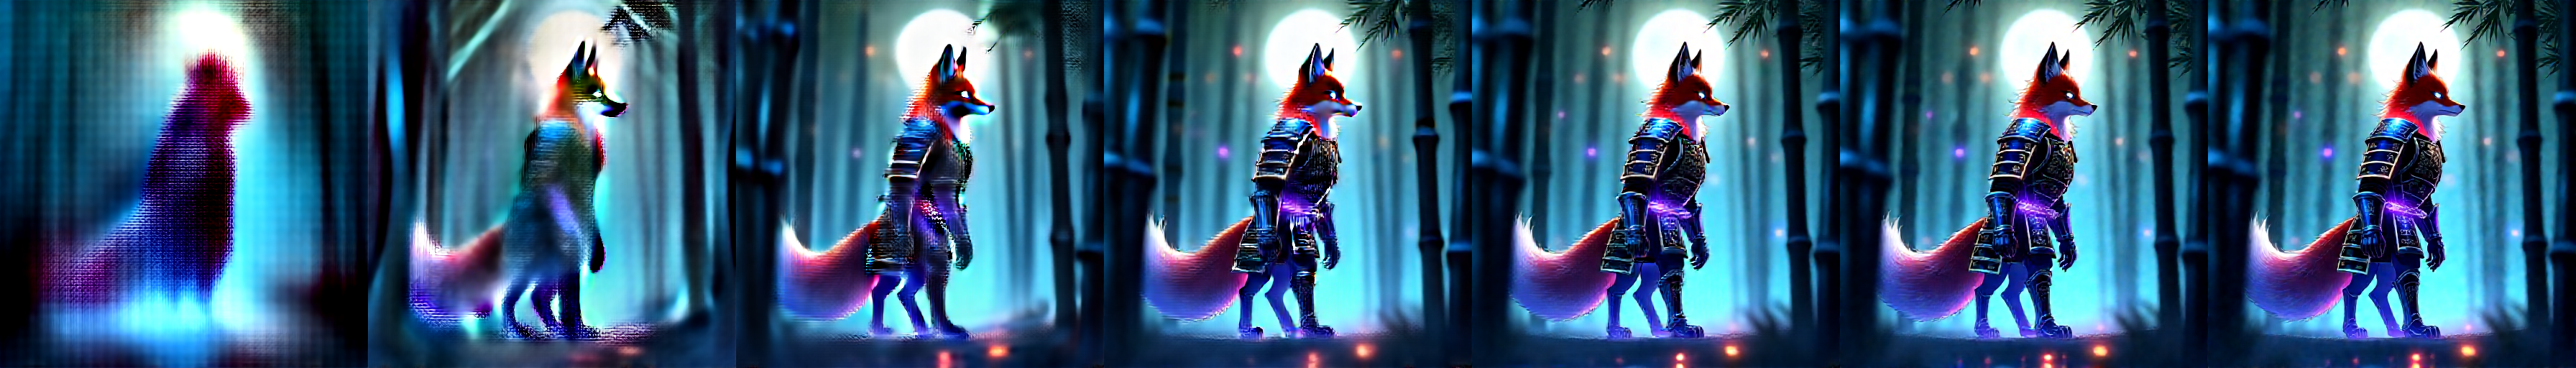
Ours
λ = 0.5
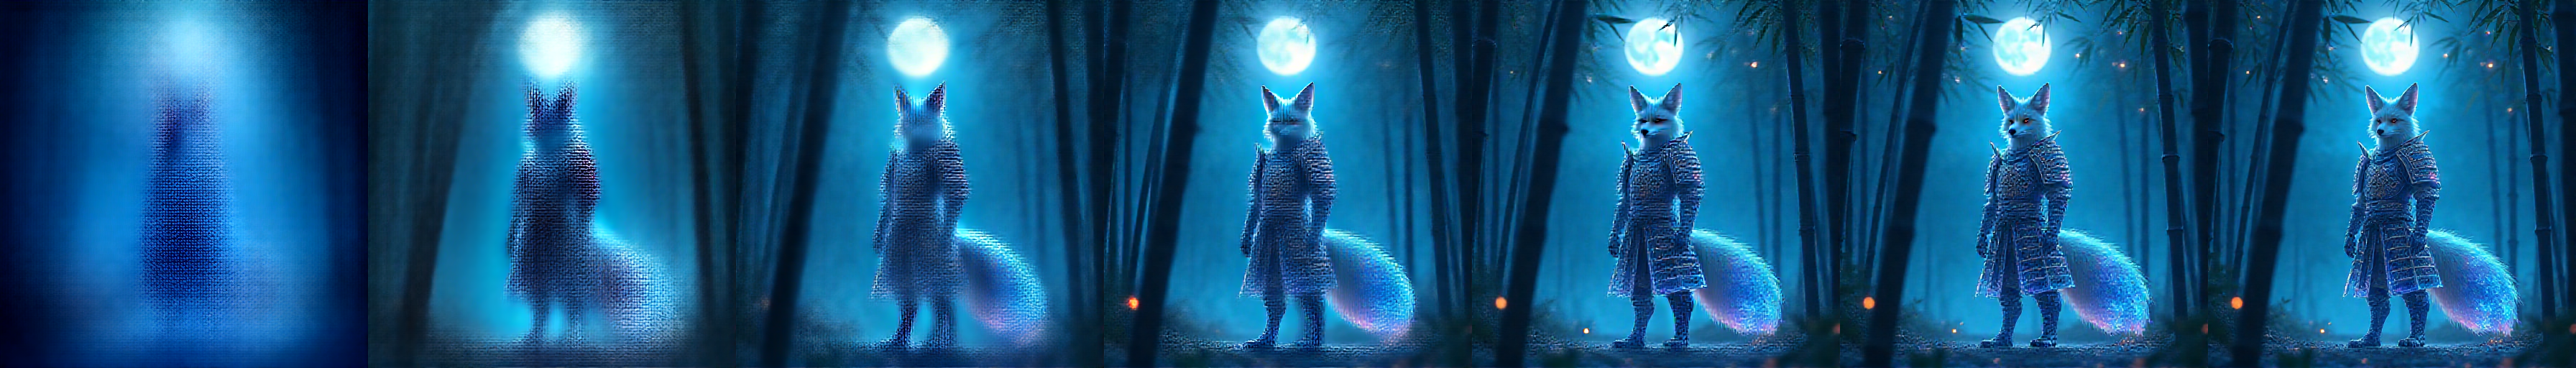
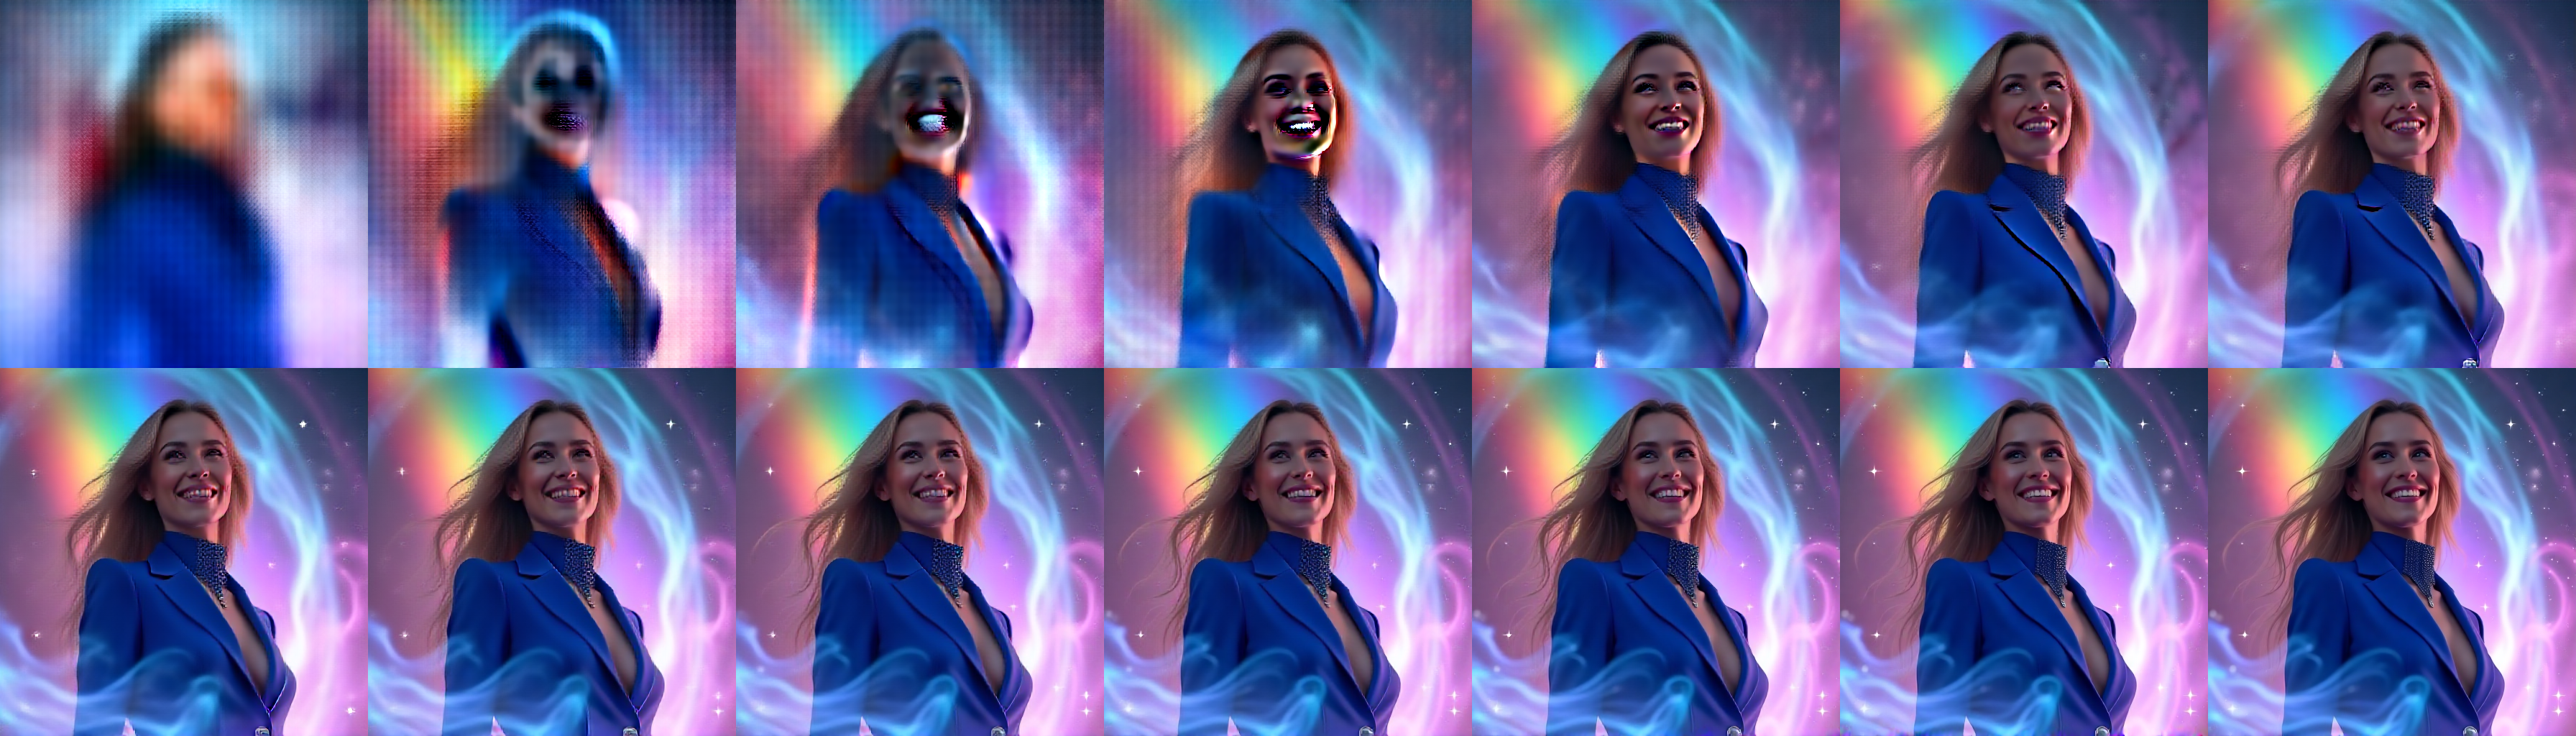
CFG, ω = 2.5
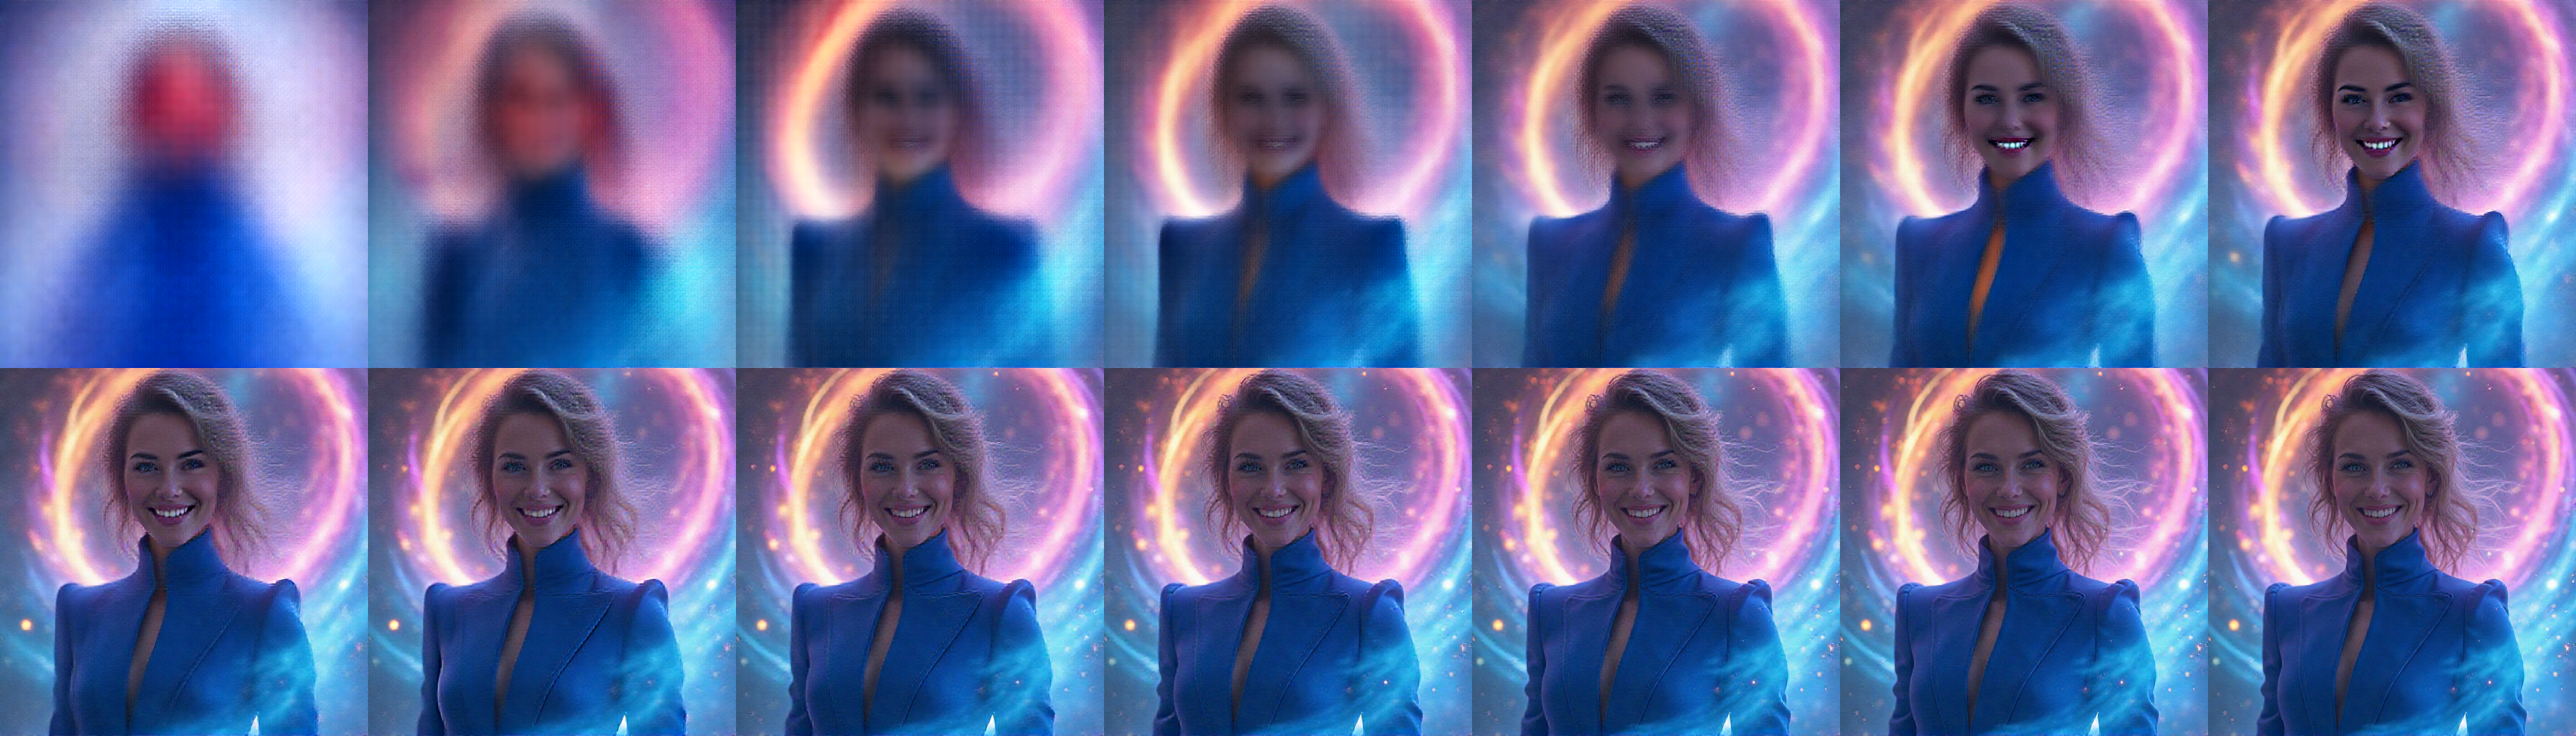
Ours, λ = 0.5
Each strip shows 7 denoising steps, from noise on the left to the final image on the right.
CFG drifts by step 2 or 3 and every later step amplifies it. Ours looks natural throughout.
Baseline, CFG and Rectified-CFG++ on three Flux prompts
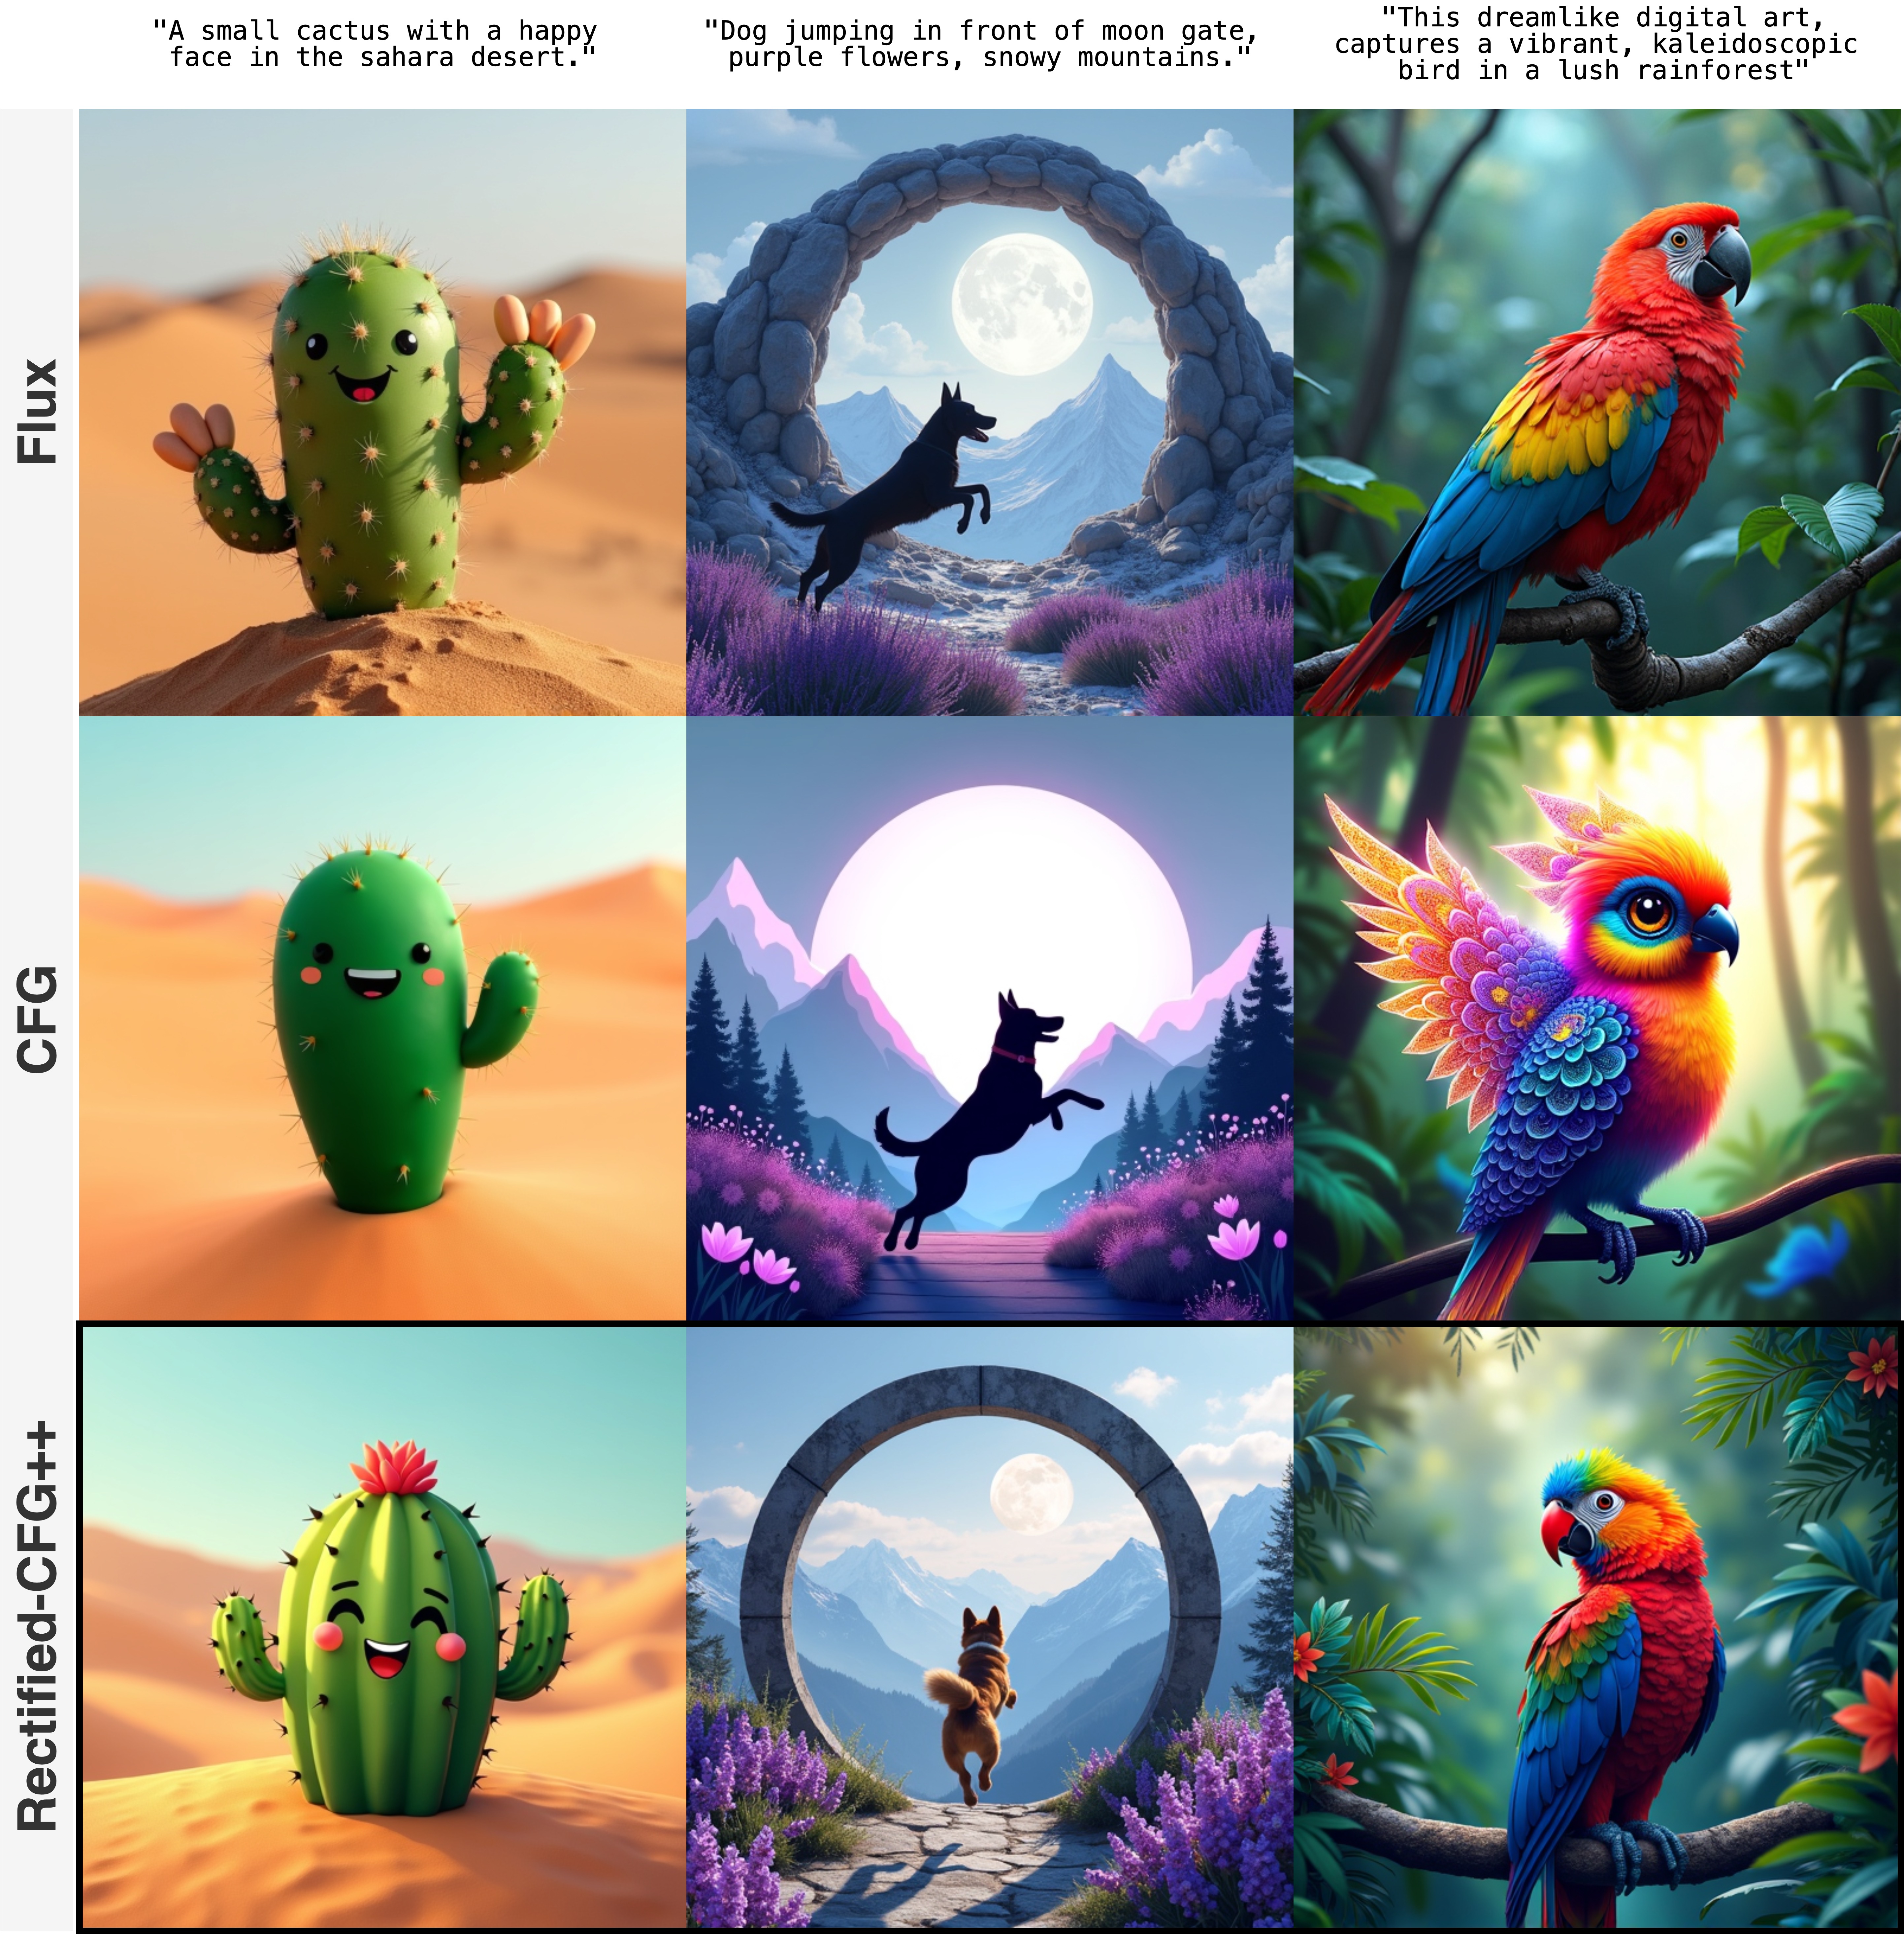
Rows, top to bottom: Flux baseline with no guidance, CFG, Rectified-CFG++.
- Cactus. CFG draws a cartoon with an emoji face.
- Dog and moon gate. CFG loses the stone arch and paints mountains.
- Parrot. CFG turns the bird into a psychedelic abstraction.
Ours keeps the realism and the structure in all three.
CFG versus ours on Flux-dev, eight pairs
CFG
Ours
CFG
Ours
CFG
Ours
CFG
Ours
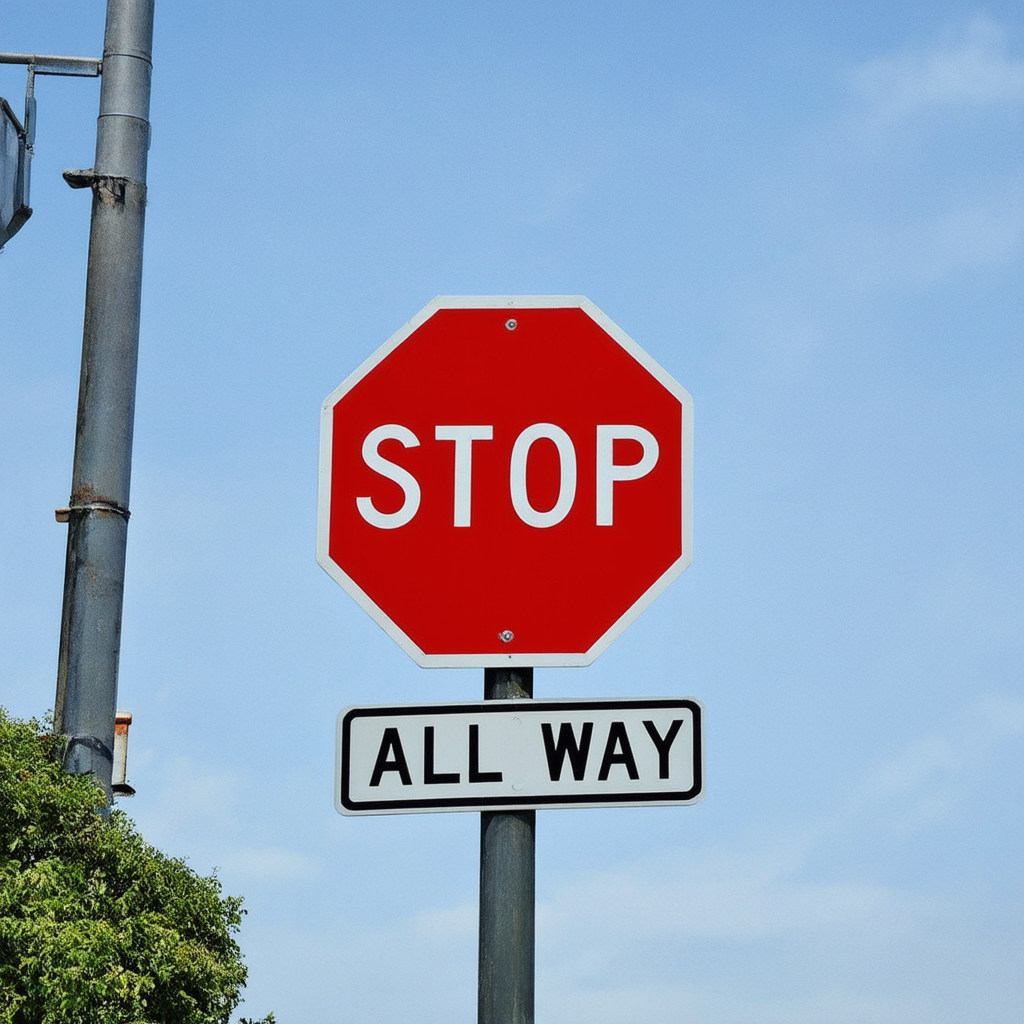
Text rendering, the stop sign test
Text needs pixel-precise strokes in the last denoising steps
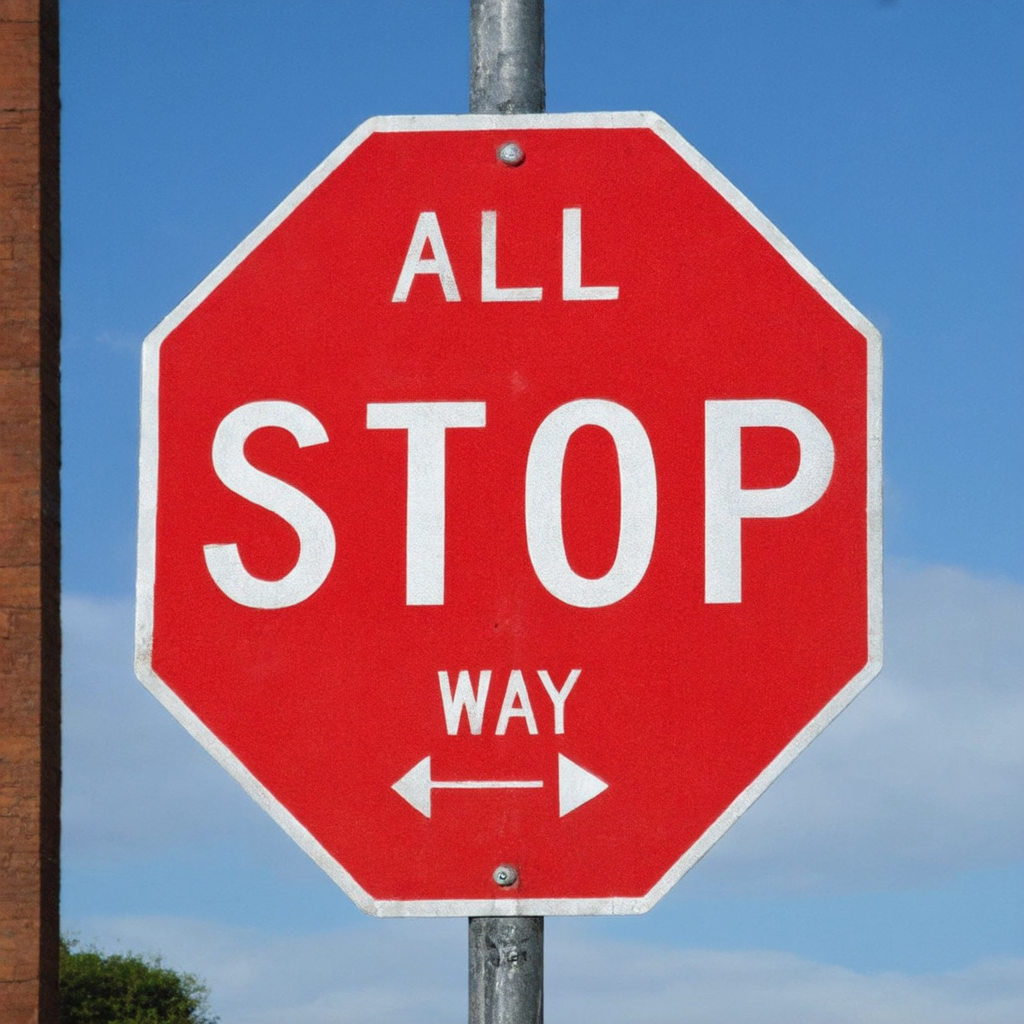
CFG
Rectified-CFG++
Prompt: "A stop sign with 'ALL WAY' written below it."
CFG. STOP warps and ALL WAY is unreadable.
Ours. α(t) is 0 in the last steps, so the strokes stay crisp.
Results on MS-COCO 10K
| Model | Method | FID ↓ | CLIP ↑ | ImgRwd ↑ | Pick ↑ | HPS ↑ |
|---|---|---|---|---|---|---|
| Lumina | CFG | 26.93 | 0.261 | 0.547 | 21.03 | 0.253 |
| Lumina | Ours | 22.49 | 0.268 | 0.621 | 21.19 | 0.259 |
| SD3 | CFG | 26.33 | 0.273 | 0.684 | 21.48 | 0.264 |
| SD3 | Ours | 24.68 | 0.278 | 0.753 | 21.62 | 0.269 |
| Flux | CFG | 37.86 | 0.285 | 0.892 | 22.04 | 0.279 |
| Flux | Ours | 32.23 | 0.289 | 0.961 | 22.18 | 0.283 |
| Guidance (SD3.5) | FID ↓ | ImgRwd ↑ | CLIP ↑ | HPSv2 ↑ |
|---|---|---|---|---|
| CFG | 67.71 | 1.053 | 0.352 | 0.294 |
| CFG-Zero* | 68.39 | 0.995 | 0.346 | 0.288 |
| APG | 67.23 | 1.075 | 0.351 | 0.294 |
| Rectified-CFG++ | 67.15 | 1.085 | 0.351 | 0.296 |
Best or tied on every metric, for every model.
User study
30 experts × 32 prompts × 4 models × 4 criteria = 15,360 responses
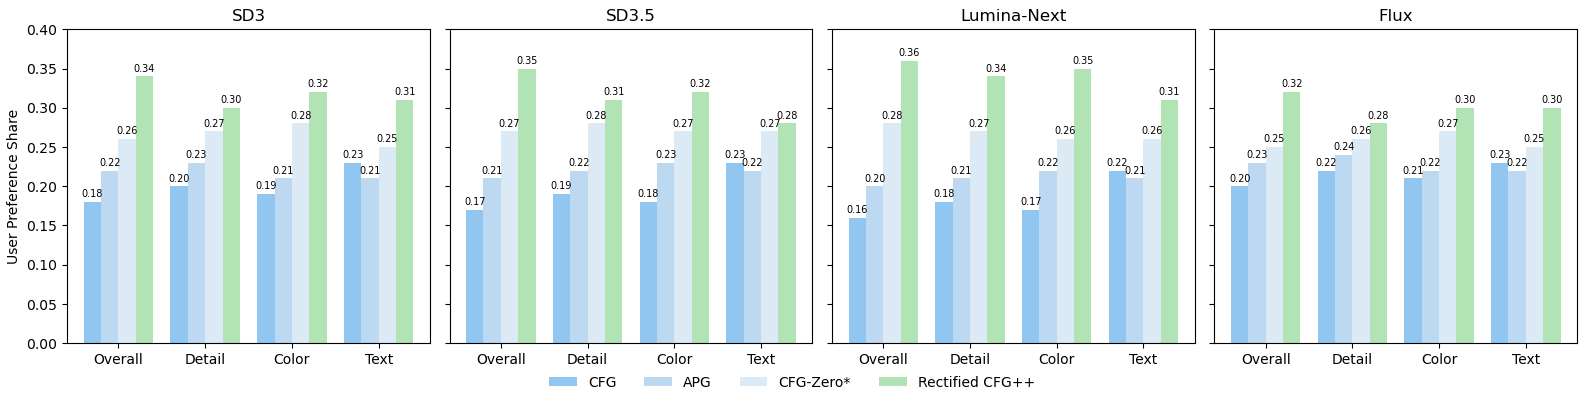
Four-way forced choice: CFG (dark blue), APG (medium blue), CFG-Zero* (light blue), Rectified-CFG++ (green). Green is tallest in every comparison.
Overall. 34 to 36% of votes on every model. Chance is 25%. p < 0.001 against APG.
Text legibility. The largest gain, 28 to 32% against 22 to 25%.
Agreement. Fleiss' κ = 0.61, with image order randomized.
Sweeping the number of sampling steps
Better quality with fewer steps
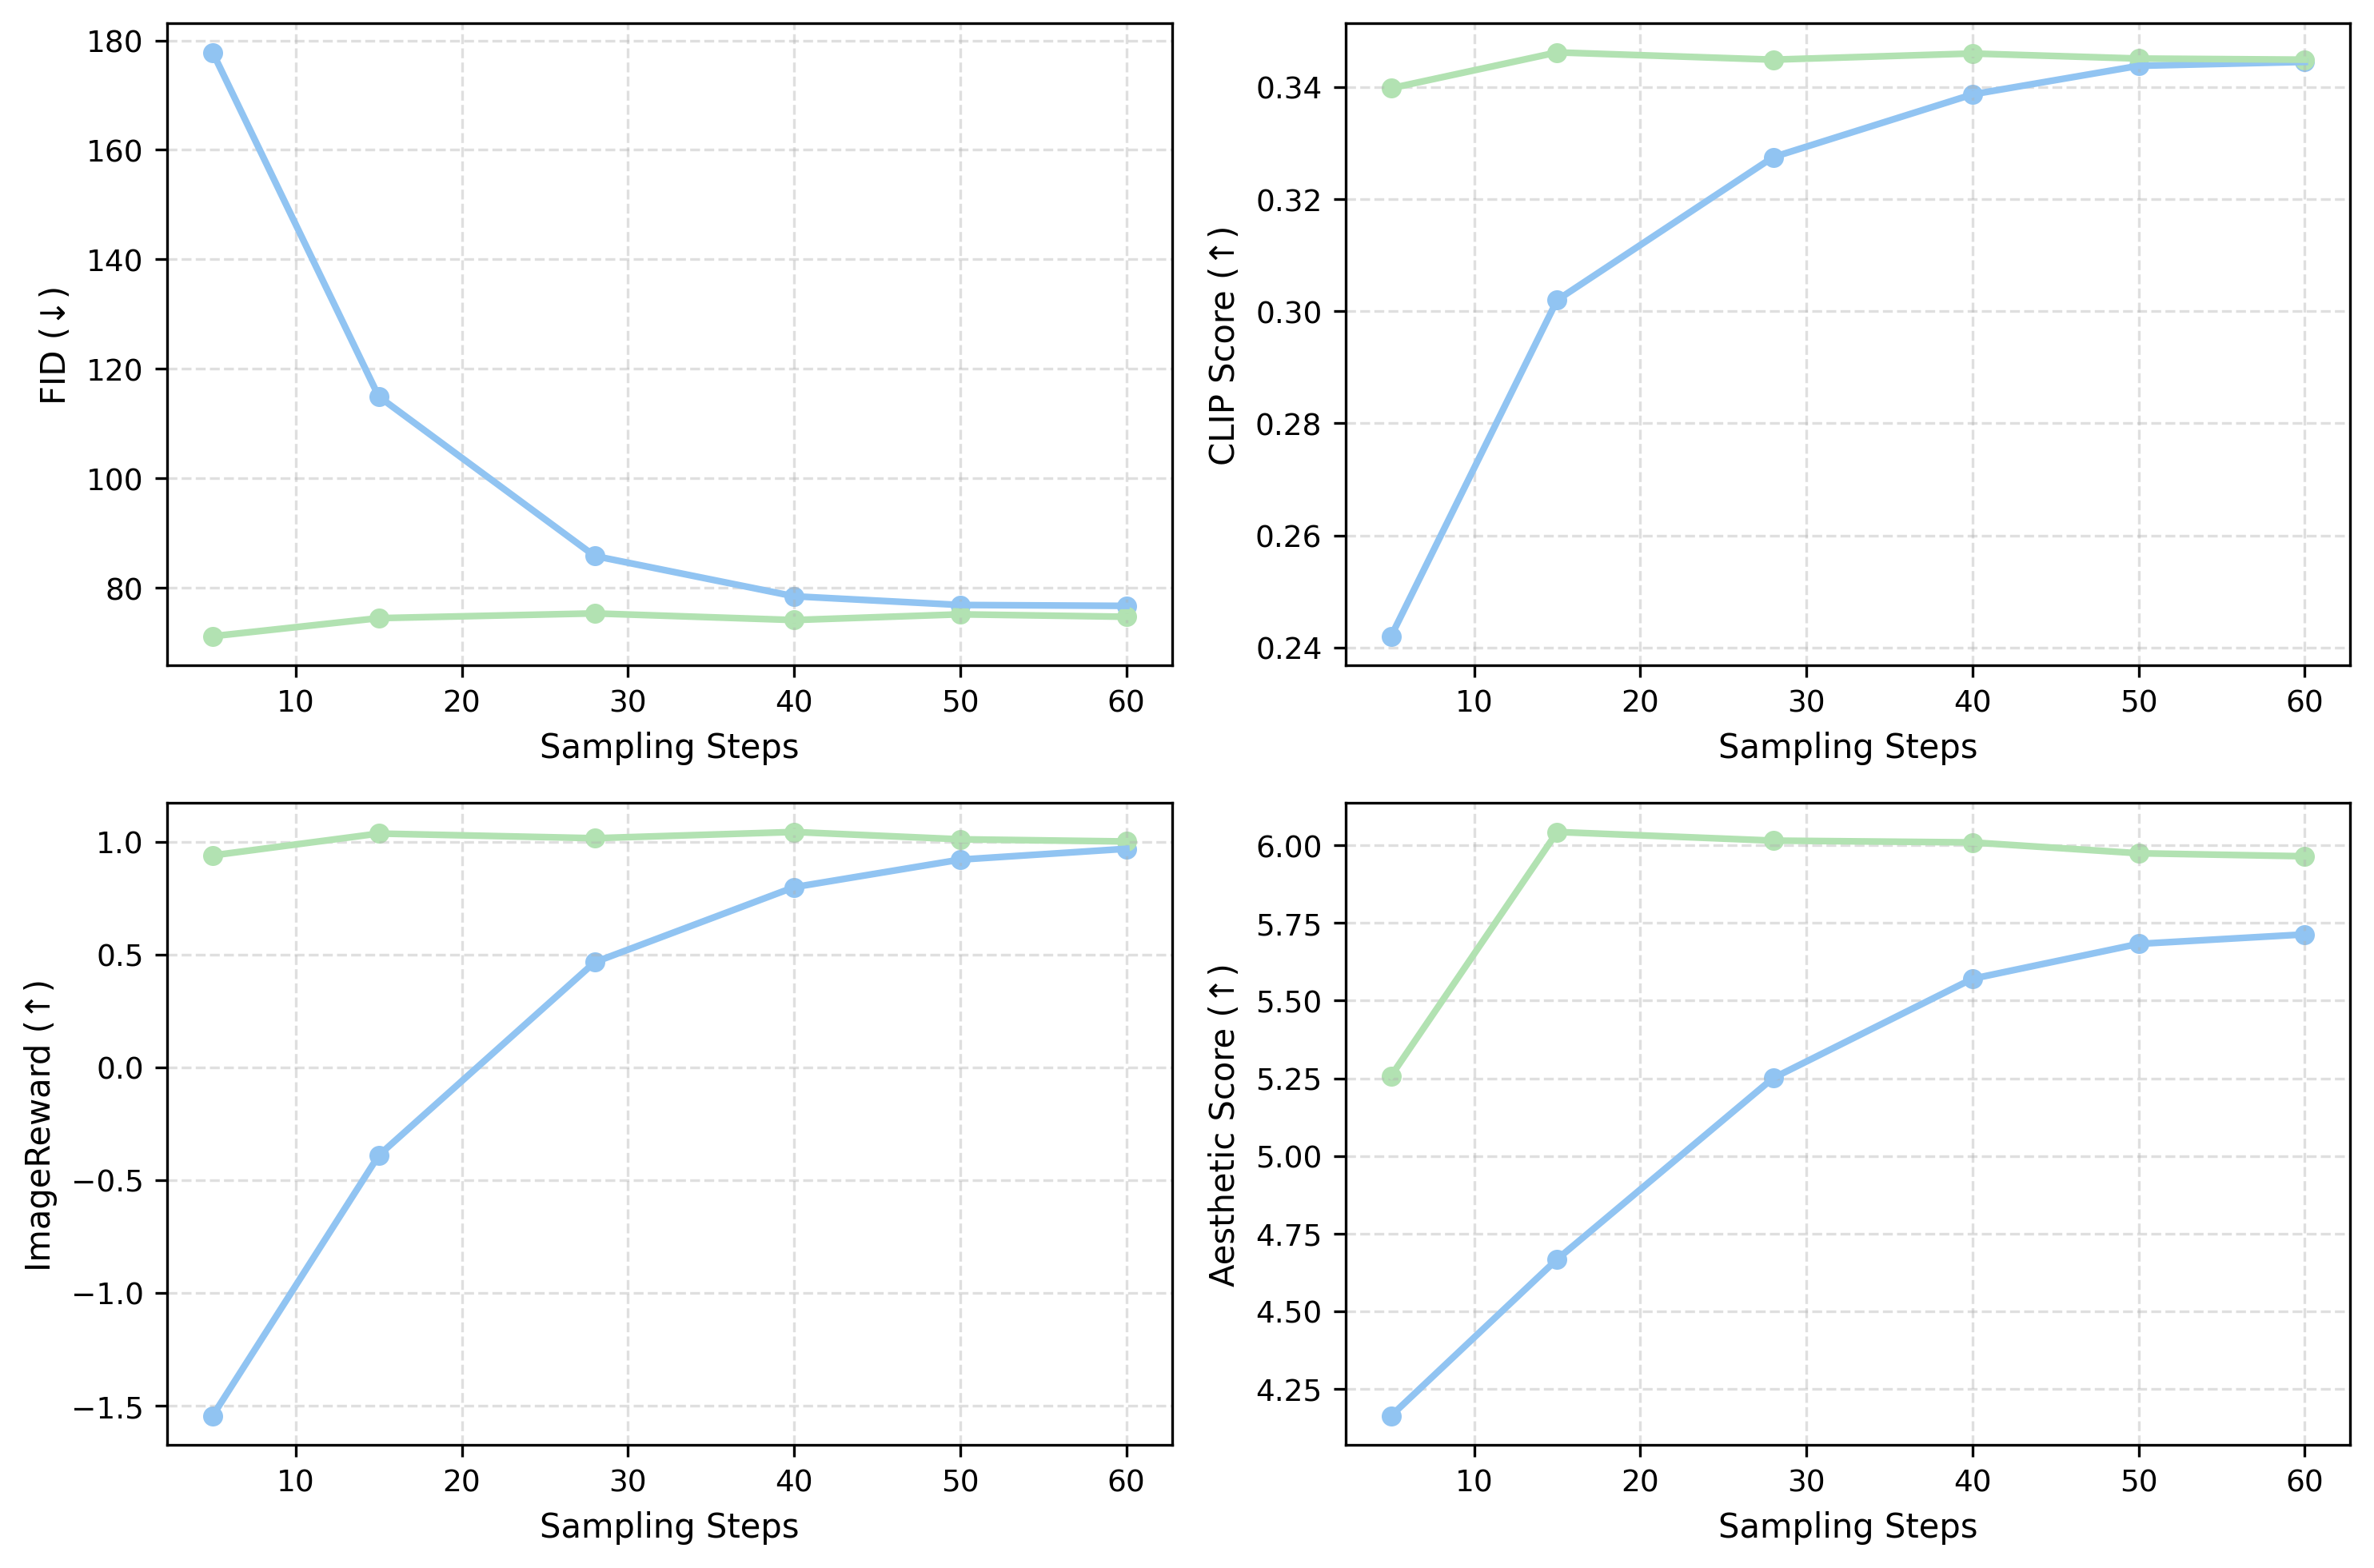
- 5 steps. FID 71 against 178 for CFG, 2.5× better. ImageReward 1.0 against −1.5.
- 15 of our steps match 28 of CFG's, about 2× faster.
Component ablation on SD3.5
| Configuration | FID ↓ | CLIP ↑ | HPSv2 ↑ |
|---|---|---|---|
| Unconditional only | 91.12 | 0.144 | 0.187 |
| Without predictor | 73.70 | 0.341 | 0.297 |
| Without corrector | 74.65 | 0.341 | 0.298 |
| Full | 72.97 | 0.345 | 0.300 |
Both the predictor and the corrector are needed.
x-axis: sampling steps. Blue is CFG, green is ours. Ours converges faster on every metric.
Takeaways
- On-manifold guidance for rectified flows.
Predictor-corrector, adaptive decay, bounded manifold distance. - 4 to 16× tighter distributional bound than CFG.
Integrated guidance λ/(γ+1) against ω−1. - A drop-in for Flux, SD3, SD3.5 and Lumina.
No retraining; 15 steps match CFG's 28.
p < 0.001
Next, video models, distilled flow models and HDR generation inside LumaFlux.
Summary of contributions
1. HDR-Q
The first multimodal LLM for HDR video quality, trained with HAPO
Saini et al., CVPR 2026
2. Rectified-CFG++
On-manifold guidance for rectified flows, provably bounded
Saini et al., NeurIPS 2025
3. LumaFlux
Frozen FLUX.1-dev, monotone RQS tone field, 8 flow steps
Saini et al., arXiv:2604.02787
Built on Beyond8Bits (44K HDR videos, 1.5M+ ratings; CVPR 2026), LGDM (zero-shot IQA, ICML 2025), HIDRO-VQA (WACV 2024) and BrightRate (WACV 2026).
Connecting the contributions
Understanding perception enables guiding generation, which enhances perception.
MLLM + HAPO on Beyond8BitsSaini et al., CVPR 2026
on-manifold predictor-correctorSaini et al., NeurIPS 2025
frozen FLUX.1-dev, monotone RQSSaini et al., arXiv:2604.02787
Generative priors are the common thread, in assessment and in enhancement.
Publications
Perceptual quality
- BrightRate-LM. MVA, WACV 2026 Special Issue, in submission
- Seeing Beyond 8bits (HDR-Q). CVPR 2026
- BrightRate. WACV 2026, Oral, Best Student Paper Award
- GameScope. ICIP 2026
- LGDM. ICML 2025
- CHUG. ICIP 2025
- HIDRO-VQA. WACV 2024
Generation and enhancement
- CachedSearch. Preprint 2026
- LumaGuide. Preprint 2026
- LumaFlux: Structure-Aware SDR-to-HDR Conversion with Monotone Luminance Flows. arXiv:2604.02787
Paper · Code · Project page · Weights on Hugging Face - Rectified CFG++ for Flow Based Models. NeurIPS 2025
Newest first. Bold marks the three dissertation chapters.
Questions?
Thank you
Perceptual quality assessment and enhancement of visual media using generative priors
Shreshth Saini, PhD candidate
shreshth@utexas.edu
Slides at shreshthsaini.github.io/slides/defense.html
Laboratory for Image and Video Engineering (LIVE), The University of Texas at Austin
Advised by Prof. Alan C. Bovik
Backup
Backup slides
Beyond8Bits and BrightRate (review) (full figure)
HDR vs SDR gap, Beyond8Bits diversity, and HDR-Q improvements over baselines. Beyond8Bits: Saini et al., CVPR 2026.
LGDM turns a diffusion model into a zero-shot quality judge (review) (full figure)
LGDM has the best median SRCC across authentic-distortion benchmarks. Saini, Liao, Ye, Bovik, ICML 2025.
LumaFlux is best in every column of the primary track (full table)
LumaEval synthetic track, 100 held-out frames under eight tone-mapping degradations, one scoring stack
| Method | PU21-PSNR ↑ | PU21-PSNR-Y ↑ | PU21-SSIM ↑ | ΔEITP ↓ | HDR-LPIPS ↓ | HDR-VDP-3 ↑ | FR-HIDRO ↓ |
|---|---|---|---|---|---|---|---|
| BT.2446c | 23.74 | 24.22 | 0.8291 | 61.60 | 0.307 | 5.611 | 0.753 |
| Reinhard operator | 23.62 | 24.25 | 0.8286 | 61.76 | 0.295 | 5.726 | 0.753 |
| HDRTVNet++ | 23.03 | 23.23 | 0.8192 | 66.67 | 0.328 | 5.417 | 0.703 |
| FMNet | 22.86 | 22.97 | 0.8176 | 67.92 | 0.330 | 5.412 | 0.724 |
| ITM-LUT | 22.92 | 23.06 | 0.8142 | 67.41 | 0.315 | 5.496 | 0.761 |
| VAE + RQS (control) | 18.54 | 19.41 | 0.7647 | 111.67 | 0.381 | 3.673 | 0.924 |
| LumaFlux (ours) | 24.23 | 24.57 | 0.8294 | 56.54 | 0.269 | 5.812 | 0.631 |
FR-HIDROVQA is a full-reference distance on HIDRO-VQA features (Saini et al., WACV 2024).
In the ablation, the tone decoder matters most (full table)
| Row | Configuration | PSNR (Δ vs g) | ΔEITP (Δ vs g) |
|---|---|---|---|
| (a) | LoRA only, no RQS decoder | 19.29 (−9.90) | 256.84 (+229.03) |
| (b) | attention + MLP LoRA, with RQS | 28.36 (−0.83) | 36.35 (+8.53) |
| (c) | PGA, no spectral gate | 28.57 (−0.62) | 33.48 (+5.66) |
| (d) | PGA + spectral gate | 29.56 (+0.37) | 28.38 (+0.57) |
| (e) | PGA + gate + PCM | 29.20 (+0.01) | 31.76 (+3.95) |
| (f) | full design, seed-0 run 1 | 28.67 (−0.52) | 35.00 (+7.18) |
| (g) | full design, seed-0 run 2 (ours) | 29.19 (ref.) | 27.81 (ref.) |
| (h) | full, linear spline instead of RQS | 28.74 (−0.45) | 32.16 (+4.35) |
| (i) | full, no RQS decoder | 19.50 (−9.69) | 261.78 (+233.97) |
| (j) | full, no timestep-layer modulation | 28.38 (−0.81) | 33.90 (+6.09) |
- No RQS, row (i): PSNR falls 9.69 dB.
- A linear spline, row (h), costs 0.45 dB.
- The spectral gate, (c) to (d), adds 0.98 dB.
- Rows (f) and (g) are one configuration, 0.52 dB apart, so smaller gaps are noise.
Can a model see and reason about HDR video quality?
Today the answer is no. Every existing model was built for the 8-bit SDR world.
Beyond8Bits, the training ground for HDR-Q
The first large-scale HDR-UGC quality dataset
- 10-bit HEVC with PQ transfer and BT.2020, 360p to 1080p, bitrate ladder from 0.2 to 5 Mbps
- 2,253 crowdsourced UGC videos and 4,608 Vimeo CC videos (nature, outdoor, low-light)
- About 35 ratings per video
- Quality control: HDR10 display verification, a qualification quiz, a golden set (SROCC 0.85), SUREAL MOS aggregation; inter-subject SROCC 0.90
Dataset diversity, HDR vs SDR characteristics, and HDR-Q performance gains
Beyond8Bits: Saini et al., CVPR 2026.
HDR-aware vision encoder
Contrastive HDR/SDR discrimination
Pull HDR close to the caption, push SDR away
Full encoder loss
Semantic alignment plus HDR discrimination
Design choices
- SigLIP-2, for its strong semantic priors and multimodal compatibility
- Contrastive, because HDR information is what HDR has and SDR lacks
- 10-bit PQ input, because tone mapping destroys the signal we need
- Captions from Qwen2.5-VL-72B, written to describe quality
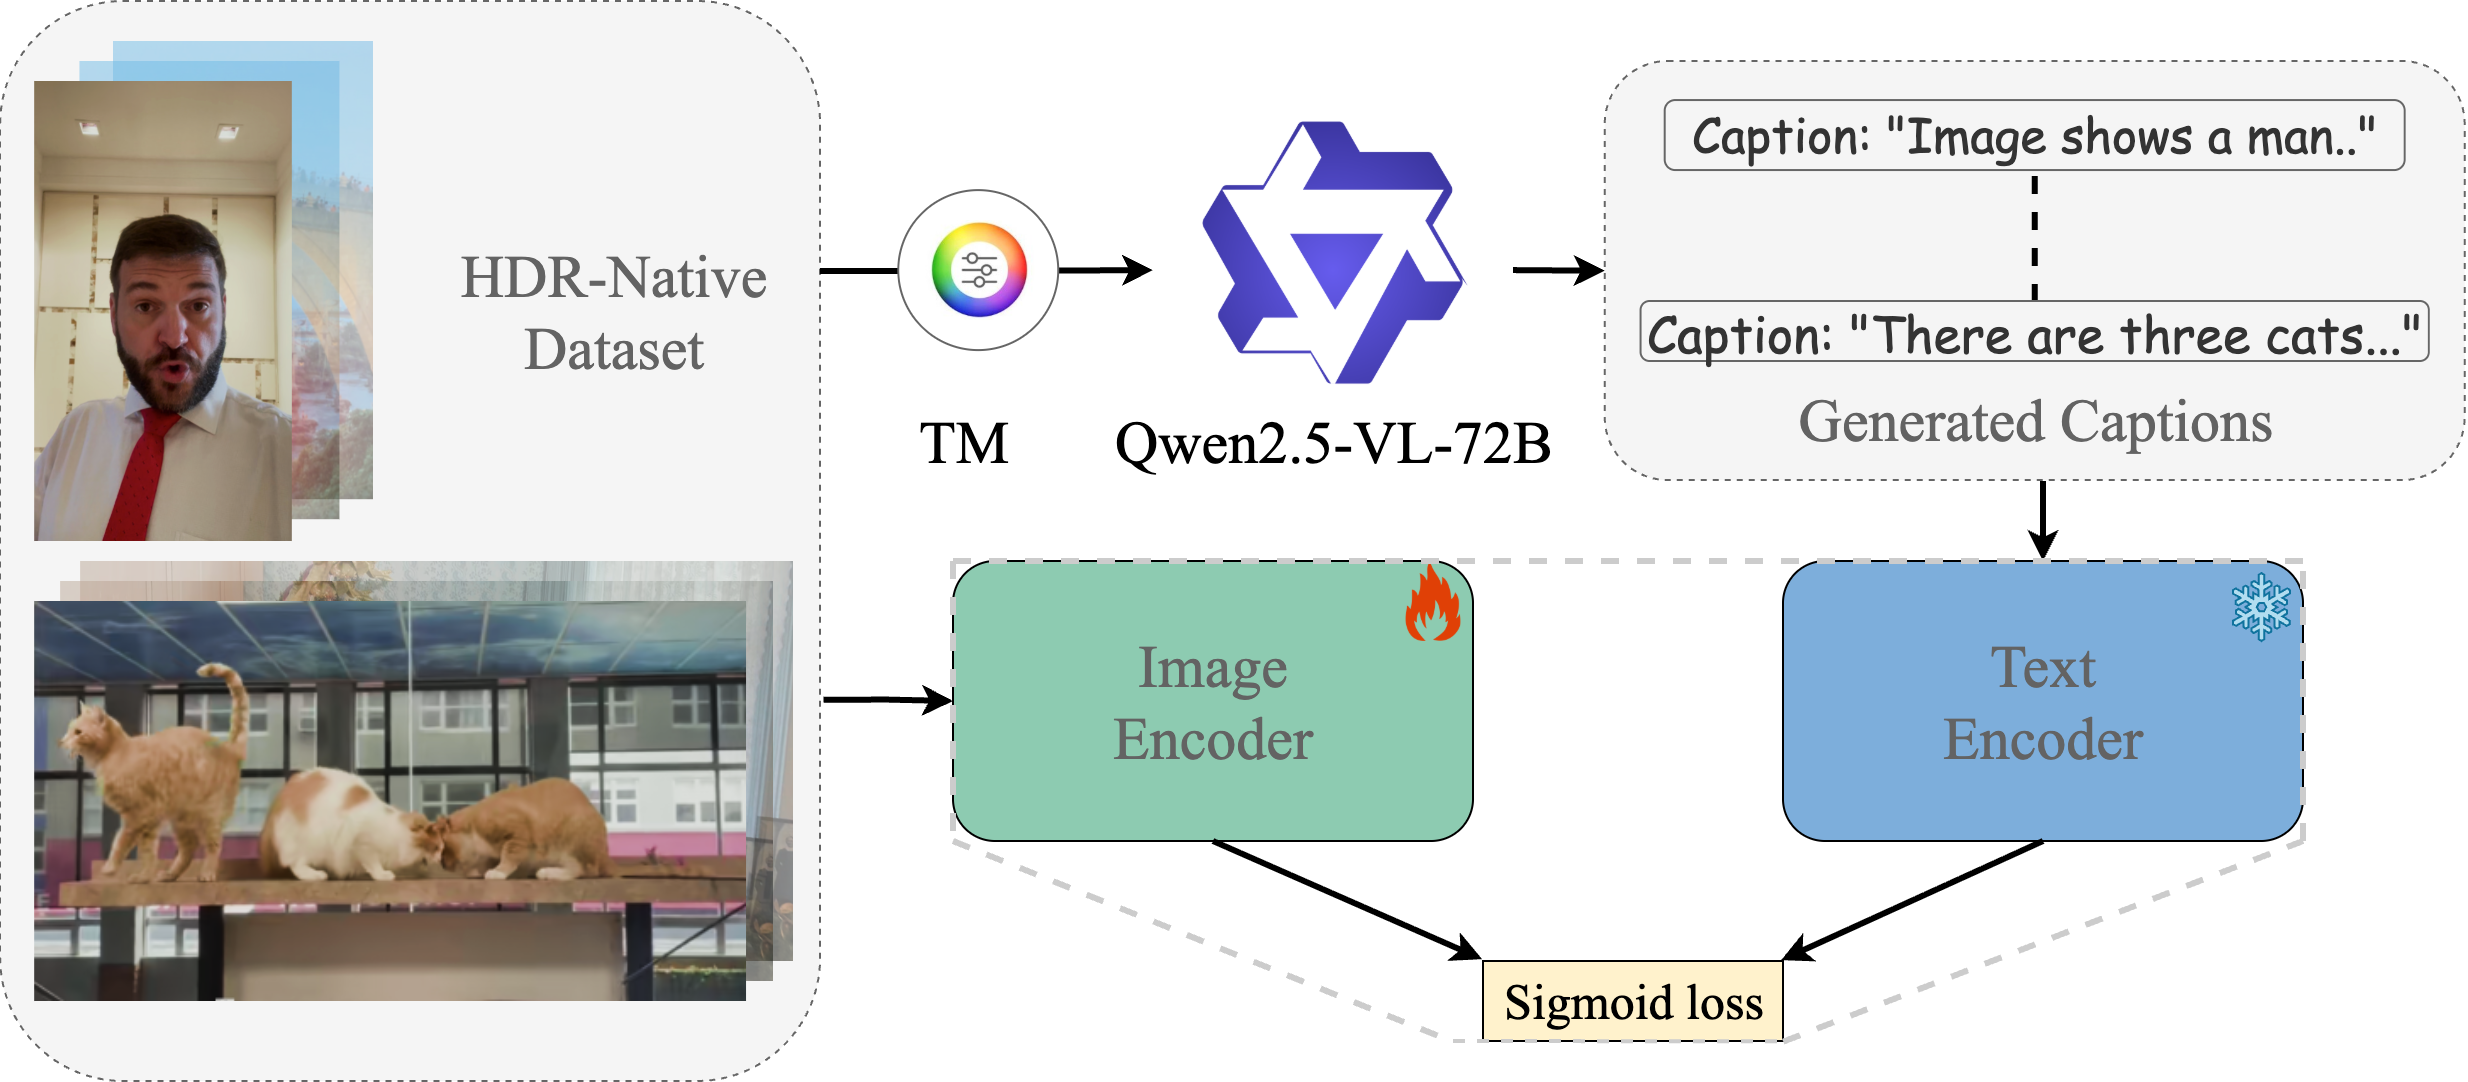
SigLIP-2 contrastive fine-tuning with matched HDR-SDR pairs and quality-aware captions
Training pipeline and reward design
Stage 1, modality alignment
Full HAPO with γ = 0.5 on a curated Beyond8Bits subset of matched HDR-SDR pairs. The goal is to teach the model to attend to HDR-specific information. Both stages use RL; there is no SFT stage.
Stage 2, quality calibration
The full Beyond8Bits corpus, with the score reward as the primary signal and a reduced γ. The goal is prediction accuracy while keeping the HDR grounding from stage 1.
Why two stages
Modality alignment and quality calibration compete. Aggressive contrastive training degrades absolute accuracy, and pure quality training allows modality neglect. Doing them in sequence resolves the tension.
Composite reward
- Rfmt is binary, 1 for valid <think> and <answer> tags
- Rscore is Gaussian, exp(−(ŝ−s*)2/2σ2) with σ = 3, smooth and differentiable
- Rself is majority-vote consistency across K = 8 completions
HAPO vs GRPO during training
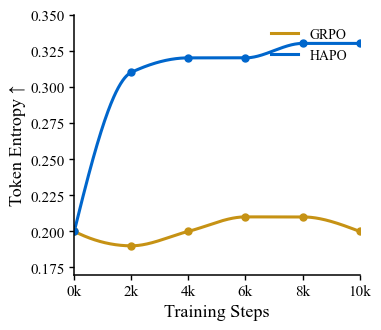
Token entropy during training. GRPO collapses; HAPO keeps healthy exploration.
GRPO failure mode
Entropy drops, generation turns deterministic, the model ignores the visual modality and takes text-context shortcuts.
HAPO stabilization
Dual entropy holds H ≈ 0.33 at quality-critical positions, so exploration survives.
Reasoning efficiency
Chain of thought shrinks from 168 to 137 tokens (−18%). Boilerplate goes, quality observations stay.
What we learned, and what remains
What we learned
- Modality neglect, rather than encoder capacity, is the bottleneck. The contrastive KL mechanism is necessary and sufficient for HDR grounding.
- Token-level entropy is a diagnostic signal. Rising entropy at decision points means better visual grounding; collapsing entropy means text shortcuts.
- Two-stage RL beats SFT followed by RL. Both stages use RL, so the HDR grounding is there from initialization.
Remaining challenges
- Temporal reasoning is limited to T = 8 sampled frames, so long-range temporal quality patterns may be missed.
- Extreme out-of-distribution content (synthetic HDR, gaming HDR) is thin in the training data.
- Inference cost. An MLLM is slower than lightweight VQA models, so this is not real-time yet.
What the SDR pipeline throws away
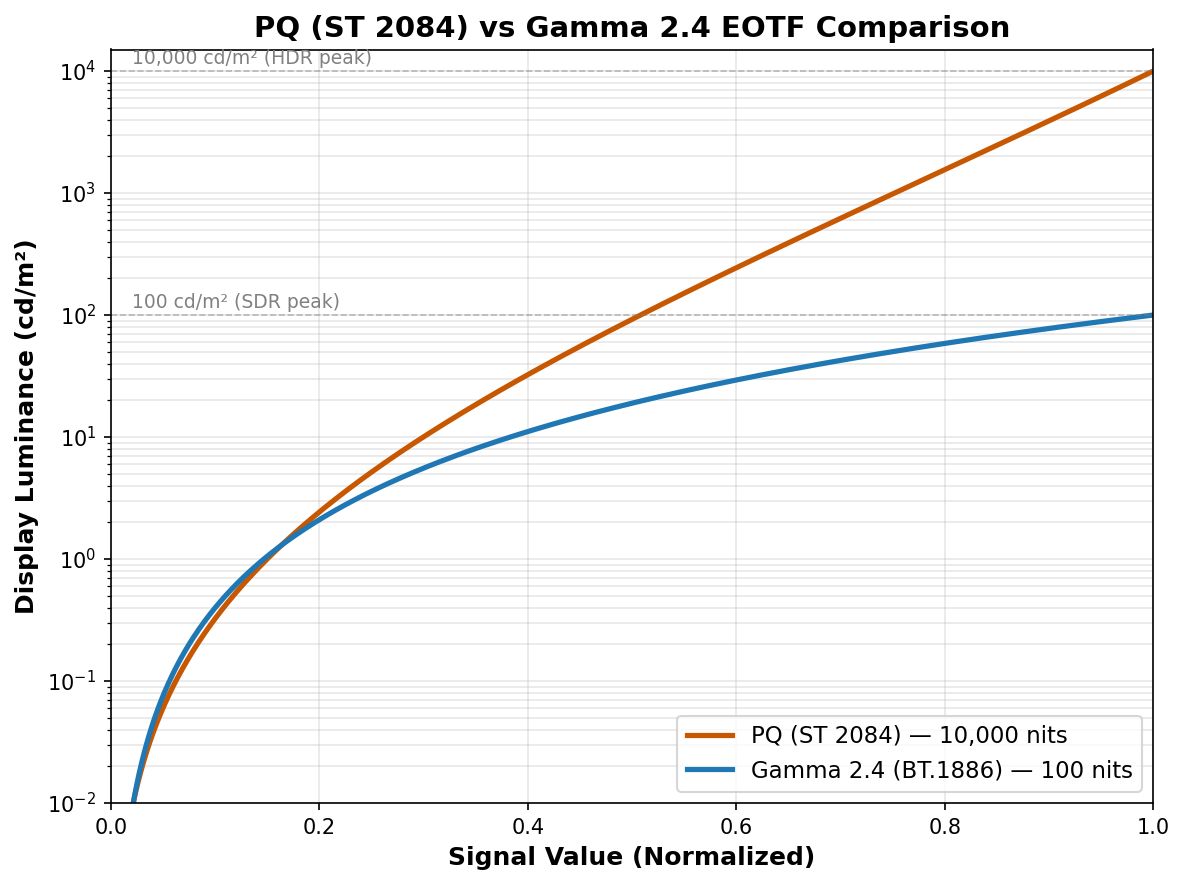
Luminance. PQ reaches 1,000 cd/m2; SDR gamma stops near 100. Everything above the ceiling becomes flat white.
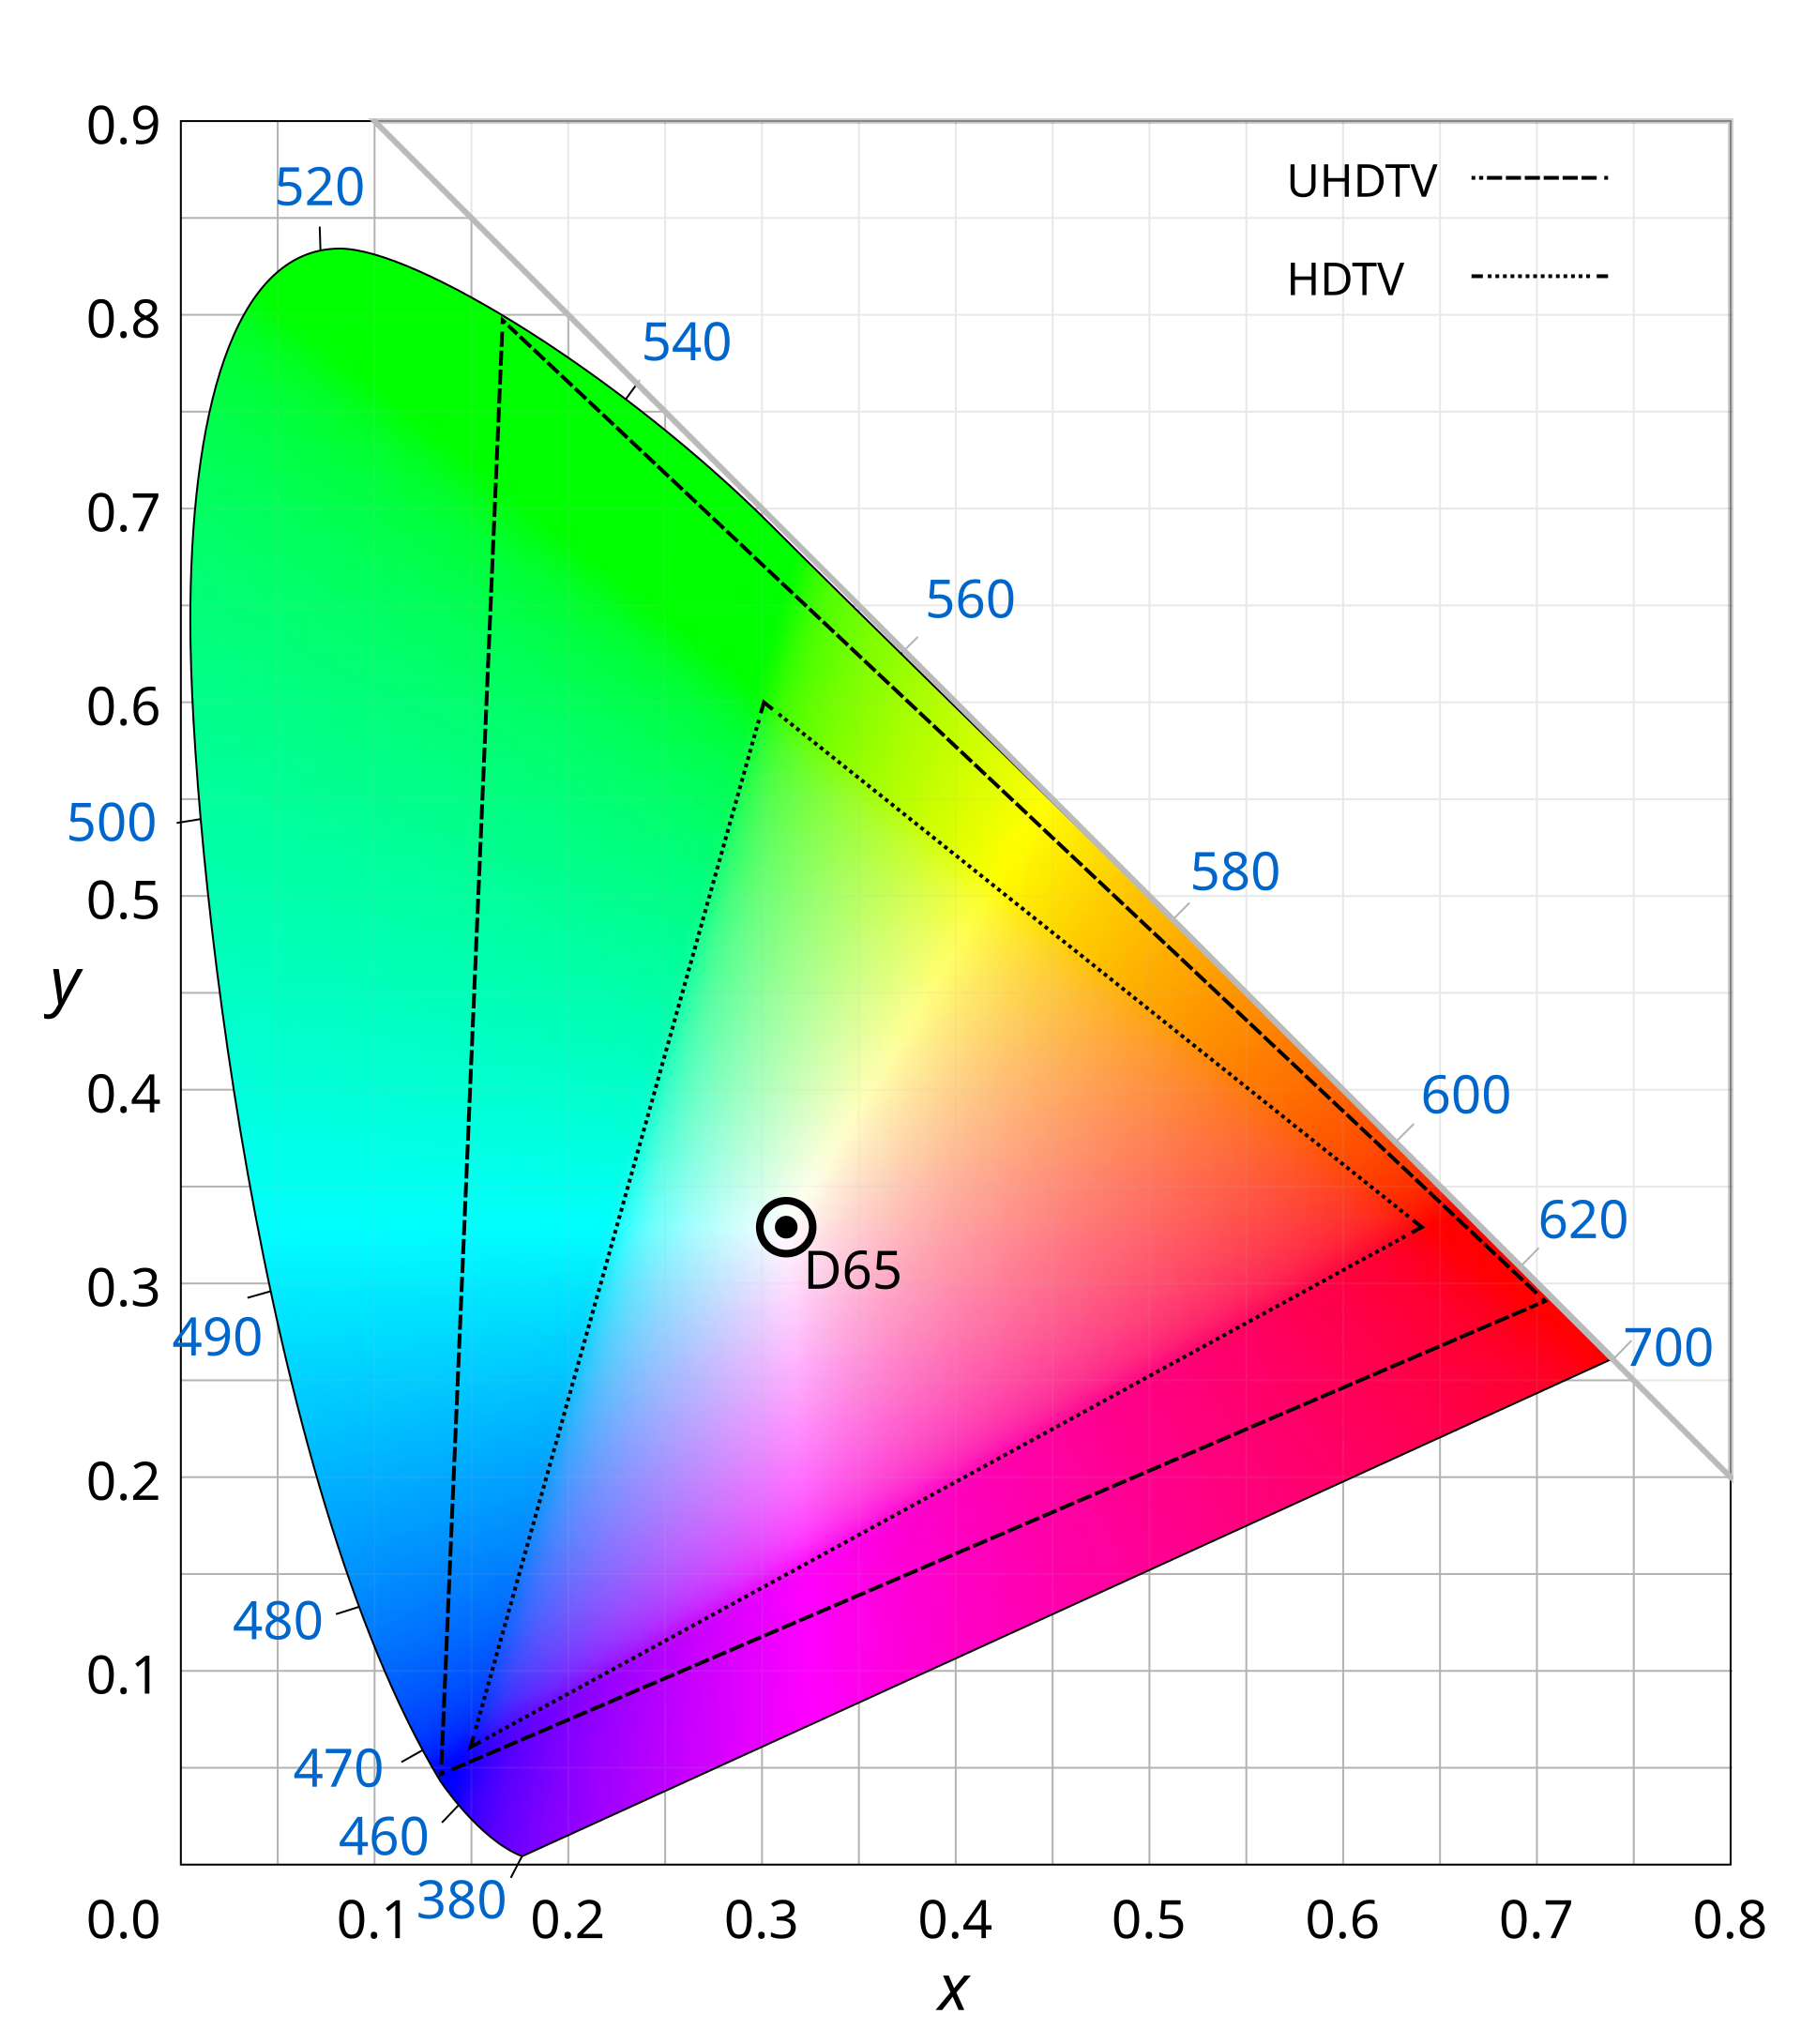
Color. BT.2020 is squeezed into BT.709, then 10-bit PQ codes become 8-bit gamma codes and a codec quantizes them.
Why the inverse is ill-posed
Clipping is many-to-one
Every luminance above the ceiling lands on the same code value, so very different highlights become one flat white.
Gamut mapping loses chroma
Distinct BT.2020 colors collapse onto the BT.709 boundary. The SDR code does not say how far outside they were.
Quantization and coding
10-bit codes become 8-bit codes and a codec removes what is left in between, so shadows band.
A converter has to invent what the frame no longer holds. The design question is what to invent, and what to leave alone.
The frozen VAE in LumaFlux was trained on SDR. The tone decoder calibrates its output, but no method recovers detail that heavy clipping removed.
Against the other generative converters
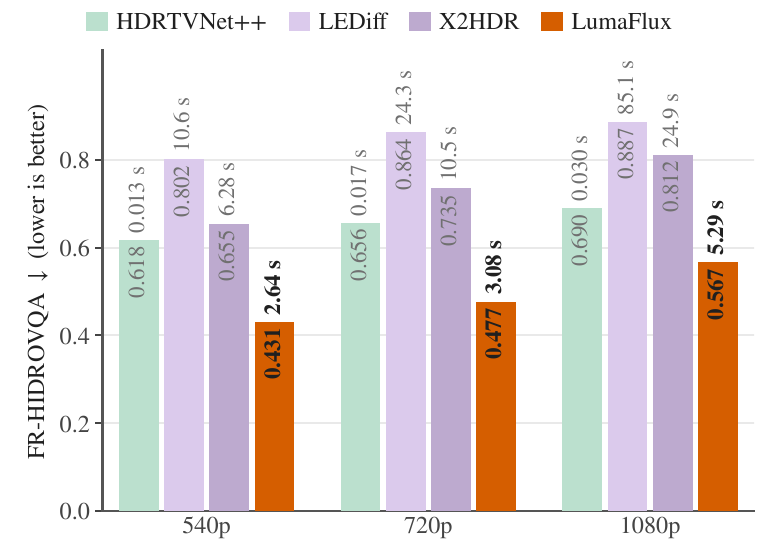
FR-HIDROVQA (lower is better) on 30 expert-track frames, with median seconds per frame above each bar.
FR-HIDROVQA is a full-reference distance on HIDRO-VQA features (Saini et al., WACV 2024).
| Method | Steps | Params (M) | Trainable (M) | s/frame | Mem. (GB) |
|---|---|---|---|---|---|
| HDRTVNet++ (CNN, for scale) | 1 | 0.59 | 0.59 | 0.857 | 2.31 |
| LEDiff (5122) | 50 | 1370.23 | 859.53 | 4.449 | 6.37 |
| X2HDR (5122) | 30 | 17020.02 | 149.42 | 4.244 | 33.77 |
| LumaFlux (ours) | 8 | 12484.77 | 71.32 | 5.282 | 27.06 |
- LumaFlux scores 0.431, 0.477 and 0.567 at 540p, 720p and 1080p, the lowest at each, in 2.64, 3.08 and 5.29 s.
- That is 2.4 to 4.7× faster than X2HDR and 4.0 to 16.1× faster than LEDiff. HDRTVNet++ stays 173 to 201× faster.
- All three generative models share one output contract: 99.5th luminance percentile anchored at 1,000 nit, BT.709 to BT.2020, clip, ST 2084.
- LumaFlux loads no text encoder and takes 8 Euler steps.
How LumaEval scores every method
| Track | Pairs | What is scored | Checkpoint |
|---|---|---|---|
| Synthetic (primary) | 100 | 20 held-out CHUG and LIVE-TMHDR contents, eight TMO variants, 78 video-variant groups | mixed-corpus |
| Expert | 100 | LIVE-TMHDR pairs whose SDR is an expert grade | mixed-corpus |
| Native | 117 | HDRTV1K test pairs | mixed-corpus |
| Legacy HDRTV1K | 117 | same pairs, five-metric suite, published baseline values | HDRTV1K-specific |
| Fixed-QP | 468 | intra-only HEVC on the SDR input at QP 27, 32, 37, 42 | both |
| Temporal | 5 clips | Bonfire and four CHUG clips, PU21 flicker energy | mixed-corpus |
| Text-to-HDR | 6 clips | LTX-Video clips, 121 frames each, intrinsic metrics only | mixed-corpus |
Degradations
BT.2390 EETF, BT.2446 Method C and hard clip (each with a gamut map); Reinhard; BT.2446 Method A; gamma clip; OpenColorIO v2; YouTube LogC.
Metrics
PU21-PSNR (RGB and Y), PU21-SSIM, ΔEITP, HDR-LPIPS, HDR-VDP-3, and FR-HIDROVQA, a full-reference distance on HIDRO-VQA features (Saini et al., WACV 2024).
Baselines
Analytic BT.2446c and Reinhard; CNNs HDRTVNet++, FMNet, ITM-LUT, KUNet; PromptIR with a fixed Reinhard inverse; generative LEDiff (50 steps) and X2HDR (30 steps); a VAE + RQS control with no diffusion transport.
KUNet and PromptIR cover 86 of the 100 synthetic IDs, and LEDiff and X2HDR only five variants, so they stay off the primary table.
Flow matching in four lines
The training recipe behind FLUX.1-dev, which LumaFlux keeps unchanged
A straight path from a data sample x0 to a noise sample x1, indexed by t in [0, 1].
The target velocity along that path is constant.
Train the network vθ by least squares on the velocity.
Sample by integrating from t = 1 back to t = 0 with a few Euler steps. No noise is injected on the way.
A text-to-image model starts at pure noise and needs many steps. LumaFlux starts much closer to the answer, which is the next slide.
Rectified flow and the SDR-conditioned bridge
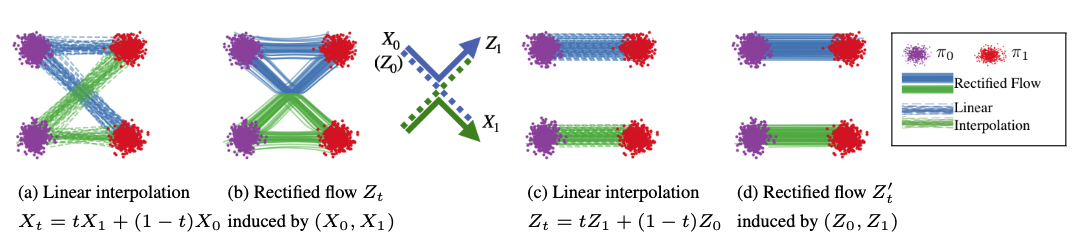
From Liu et al., Flow Straight and Fast. Rectification straightens crossing paths, so a few Euler steps track them closely.
- Training interpolates zt = (1 − t) zHDR + t z1; the network predicts the straight-path velocity z1 − zHDR.
- Sampling starts at the encoded SDR plus a small perturbation. There is no partial-noise start and no sampling-strength knob.
- 8 uniform Euler steps with fixed guidance: 5.28 s and 27.06 GB per 1080p frame on one GH200. 40 steps take 24.99 s, 4.7× the time, with no calibration gain.
- Loss (5): (λ1, λ2, λ3) = (1, 0.5, 0.1). LFM regresses the bridge velocity, the L1 terms compare linear light at the 1,000-nit peak, Lsmooth regularizes adjacent knot slopes.
- Decoded losses run every fourth optimizer step on the one-step estimate ẑ0 = zt − t v̂t; the sampler is never unrolled.
The frozen backbone, and why plain LoRA is not enough
What stays frozen
- FLUX.1-dev MM-DiT: all 57 blocks (19 dual-stream, 38 single-stream), width 3072, 24 heads, 12.48B parameters loaded.
- The FLUX VAE, which was trained on SDR images.
- SigLIP-SO400M at 3842, giving 729 tokens of width 1152.
- No text encoder is loaded. The text stream receives 8 learned null tokens plus the SigLIP tokens.
Plain LoRA
- The same low-rank update for every token, every step and every block, whatever the frame contains.
- Nothing maps the SDR-trained VAE output into HDR.
What the ablation says
| Configuration (20k steps, 82 held-out frames) | PSNR | ΔEITP |
|---|---|---|
| (a) LoRA only, no tone decoder | 19.29 | 256.84 |
| (b) attention + MLP LoRA, with the RQS decoder | 28.36 | 36.35 |
| (g) full LumaFlux design | 29.19 | 27.81 |
Removing the tone decoder from the full design costs 9.69 dB. Conditioning the adaptation on what the frame measures adds 0.83 dB over plain LoRA and cuts color error by 8.53.
The full architecture
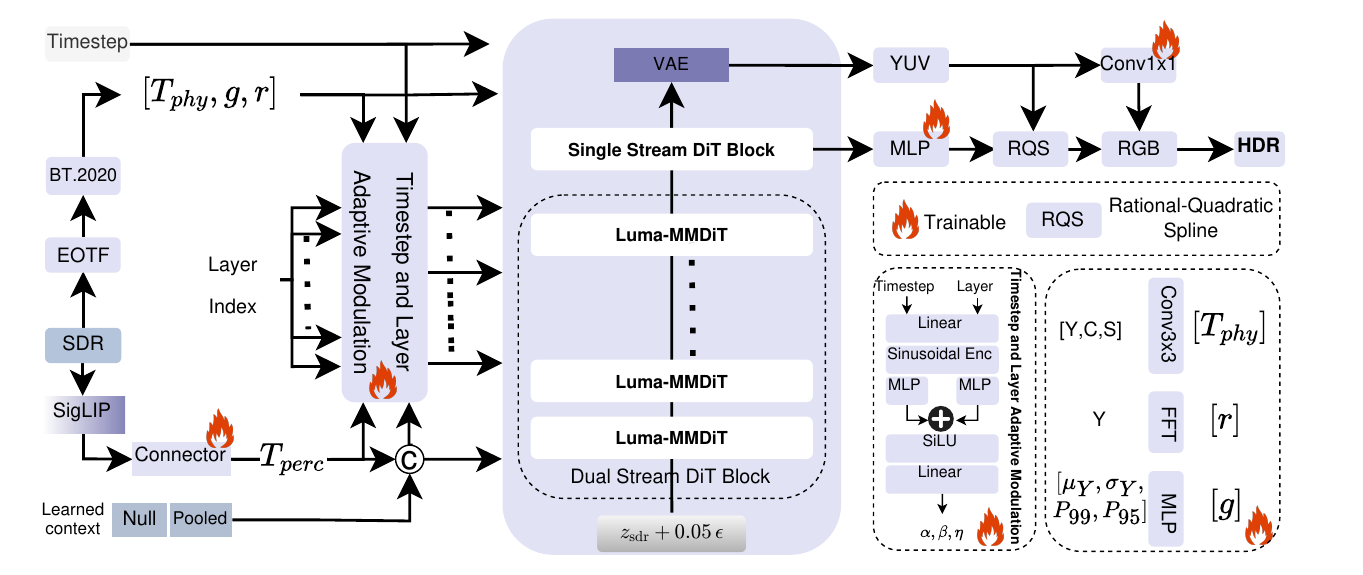
Physical measurements and SigLIP tokens condition every frozen block; the frozen VAE and the RQS head produce PQ BT.2020.
- Left: the SDR frame becomes linear-light BT.2020 measurements [Tphys, g, r]; frozen SigLIP gives 729 perceptual tokens Tperc.
- Center: Ψ(t, l) modulates PGA, PCM and the coupler in every frozen block; transport starts at zSDR + 0.05 ε.
- Top: xout = DVAE(z0) is read as PQ BT.2020 and converted to Y′CbCr; the RQS head calibrates luma.
Inside one frozen block
Standard block
h = LN(z)
Q = h W_Q,  K = h W_K,  V = h W_V
z = z + Attn(Q, K, V)
z = z + MLP(LN(z))
PCM, FiLM from the pooled SigLIP tokens
With the three paths added
z = z + γ ⊙ LN(z) + ζ                    # PCM
h = LN(z)
V_i = h_i (W_V + R_v,i)                   # PGA, per token
z = z + Attn(Q, K, V)
z = z + MLP(LN(z))
z = z + λ [W_p T_phys + W_c R(C T_perc)]  # coupler
PGA, a gated low-rank residual
- Every added path starts at zero (Bv, Wr, γ, ζ and the coupler's last layers), so step zero is exactly the frozen FLUX.
- [αpga, βpga, αpcm, βpcm, nspec, λ] = Ψ(t, l): six gains per flow step and block, from sinusoidal flow-time features and learned block embeddings, 41,094 parameters.
- Y = m2020T xlin with m2020 = [0.2627, 0.6780, 0.0593]; Tphys = Conv3×3([Y, log(1 + |∇Y|), sat]); g = MLPg([μY, σY, p95, p99]) in ℝ16; r has Kr = 8 radial bands.
Where the highlights go
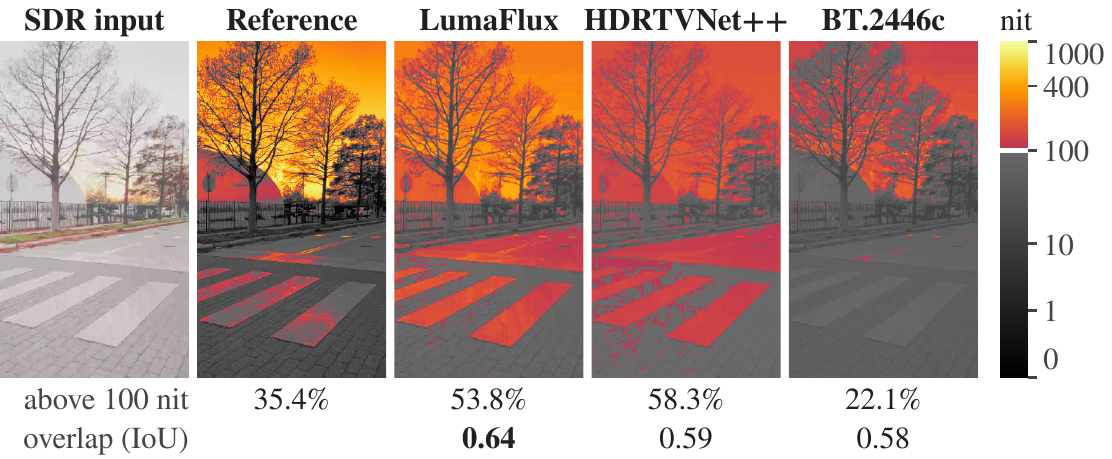
Headroom maps of one LumaEval frame. Gray is at or below 100 nit; color marks pixels above the SDR ceiling.
| Method | Share above 100 nit | IoU with reference highlights | Error inside highlights (stops) |
|---|---|---|---|
| Reference | 32.3% | ||
| BT.2446c | 19.1% | ||
| Reinhard | 29.7% | 0.563 | |
| HDRTVNet++ | 47.9% | 0.538 | 0.81 |
| LumaFlux | 37.5% | 0.579 | 0.87 |
The analytic curve under-expands, HDRTVNet++ pushes too much of the frame bright, and LumaFlux puts highlights where the reference has them.
What CFG does to flow models
Every image here is standard CFG on a flow model. These are typical results; none were cherry-picked.
Flux-dev with CFG, ω = 3 (paper Figure 6)
Plastic, cartoon look
Oversaturated
Flat, clipart look
Blown highlights
Washed out
SD3 with CFG, ω = 3 to 3.5
Oversaturated
Text garbled
Misspelled
Color blow-out
Color distortion
Four failure modes. Oversaturation (colors pushed past their natural range), cartoonification (photoreal turns plastic), text corruption (letters distort and merge), and detail blow-out (fine texture becomes flat patches).
Not rare. CFG artifacts show up on every prompt across Flux, SD3 and SD3.5. The cause is structural: CFG extrapolation is incompatible with the deterministic ODE that every modern flow model uses.
What good guidance for a rectified flow should do
- D1. Stay on the manifold. The guided trajectory stays in a bounded neighbourhood of the learned transport manifold Mt. No off-manifold drift, no error accumulation.
- D2. Strong early, gentle late. Early steps set the global structure (layout, color palette), so guidance should be strong. Late steps resolve fine detail (text, texture), so guidance should vanish to avoid corrupting it.
- D3. Provable guarantees. Formal bounds on manifold distance and on how far the output distribution drifts, on top of looking better. No prior guidance method has them.
- D4. Drop-in replacement. Works with any pretrained flow model (Flux, SD3, SD3.5, Lumina) without retraining. Swap the sampling algorithm and nothing else.
Do existing methods satisfy these?
| Method | D1 | D2 | D3 | D4 |
|---|---|---|---|---|
| CFG | no | no | no | yes |
| CFG-Zero* | no | no | no | yes |
| APG | partly | no | no | yes |
| Rectified-CFG++ (ours) | yes | yes | yes | yes |
Our idea: predict a midpoint on the manifold, evaluate guidance there, and add it to the conditional velocity as a bounded correction, in place of extrapolating from the current point.
Three ideas, three guarantees. A predictor half-step gives on-manifold evaluation, an adaptive α(t) gives vanishing guidance, and a bounded correction gives interpolation in place of extrapolation.
The ideal flow on the manifold (1 of 3)
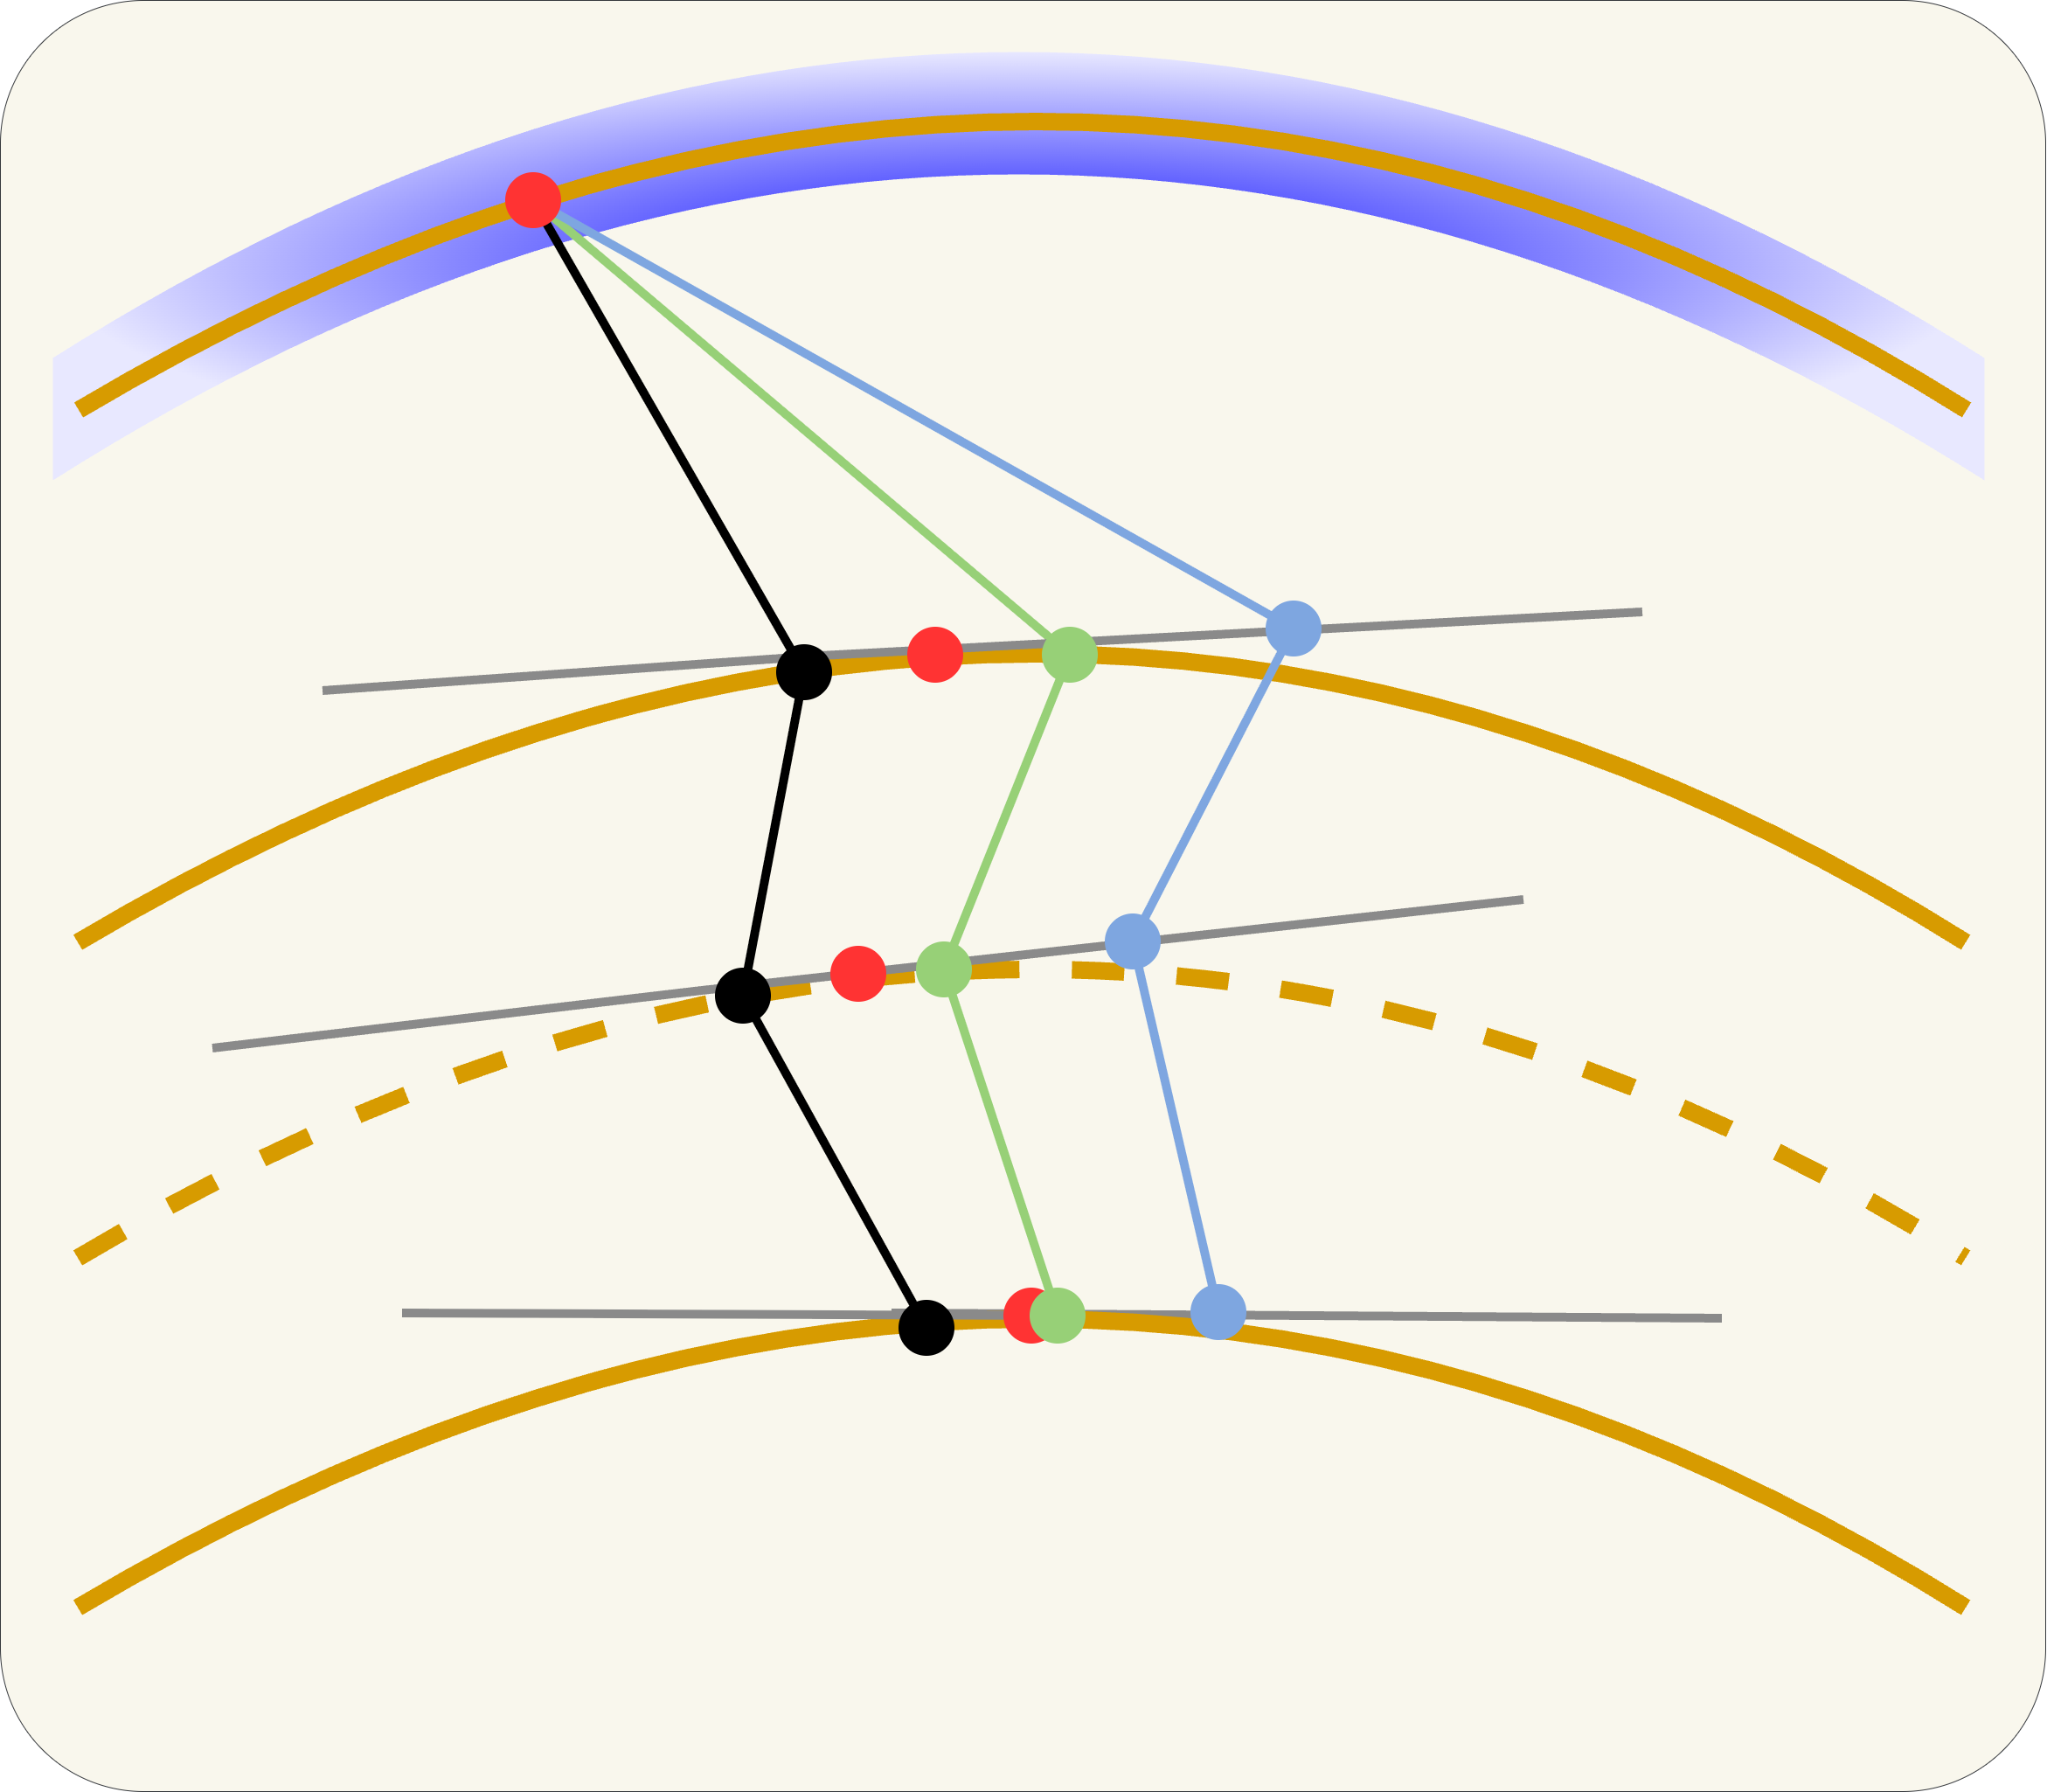
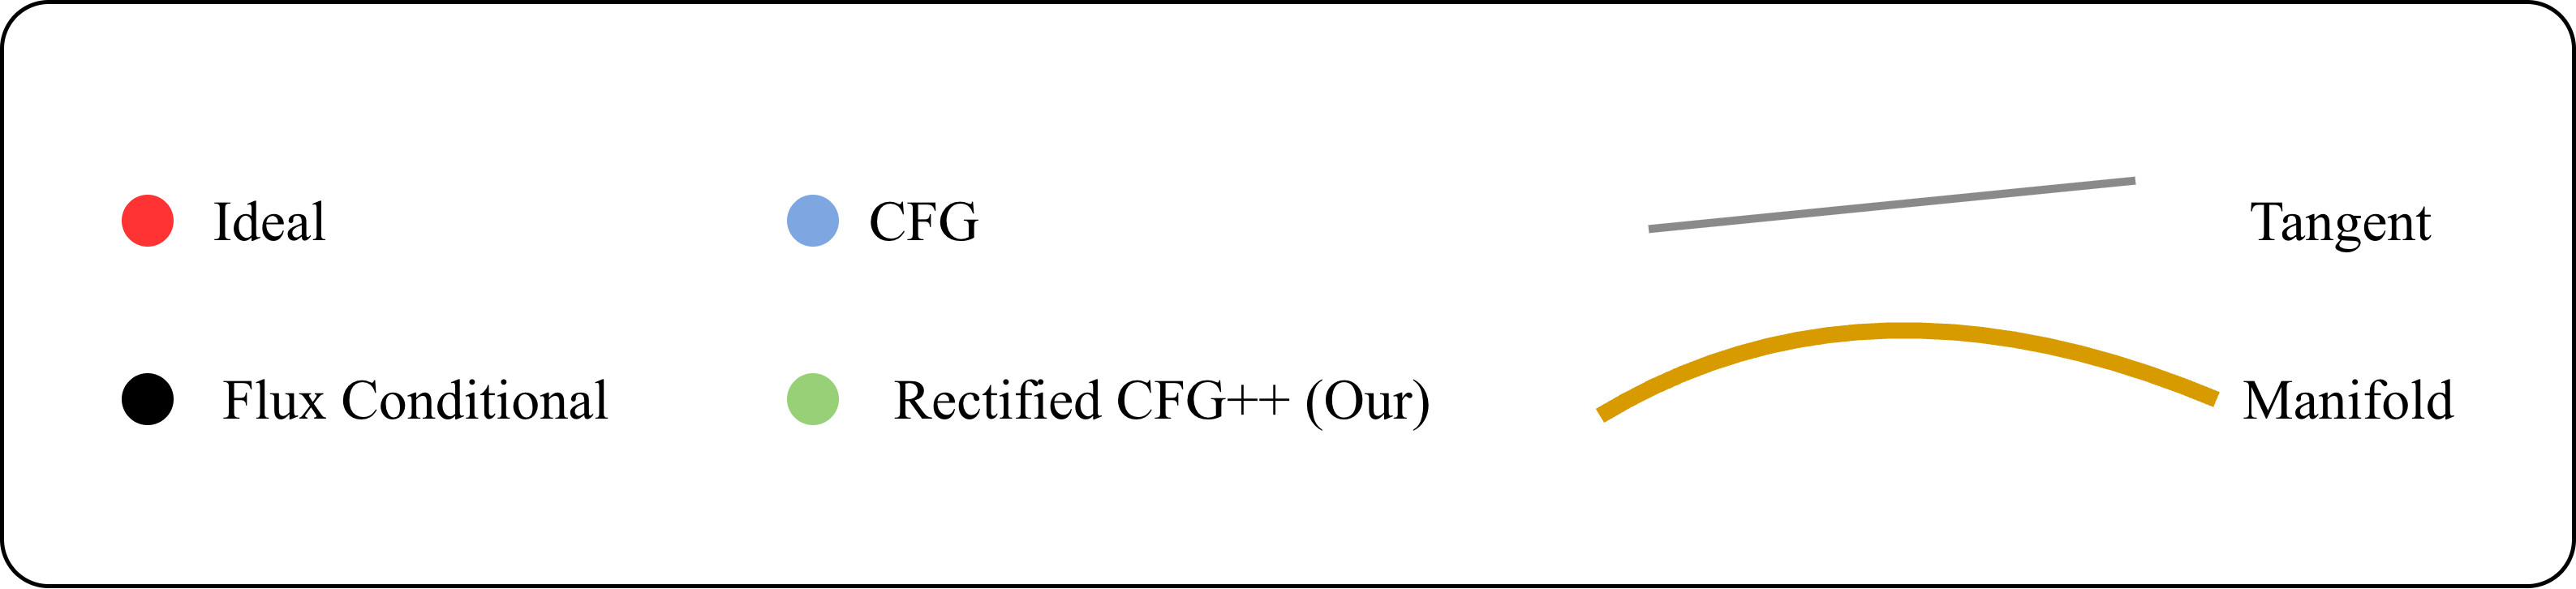
- What you are looking at. Three manifolds: Mt at the current time (the blue and gold band), Mt−1 at the next step, and M0, the data (the orange curve at the bottom). The red dots are the ideal positions at each timestep.
- The ideal trajectory. The sample flows along the manifold surface from Mt to Mt−1 to M0. At each step the velocity lies in the tangent space of the manifold and never leaves it.
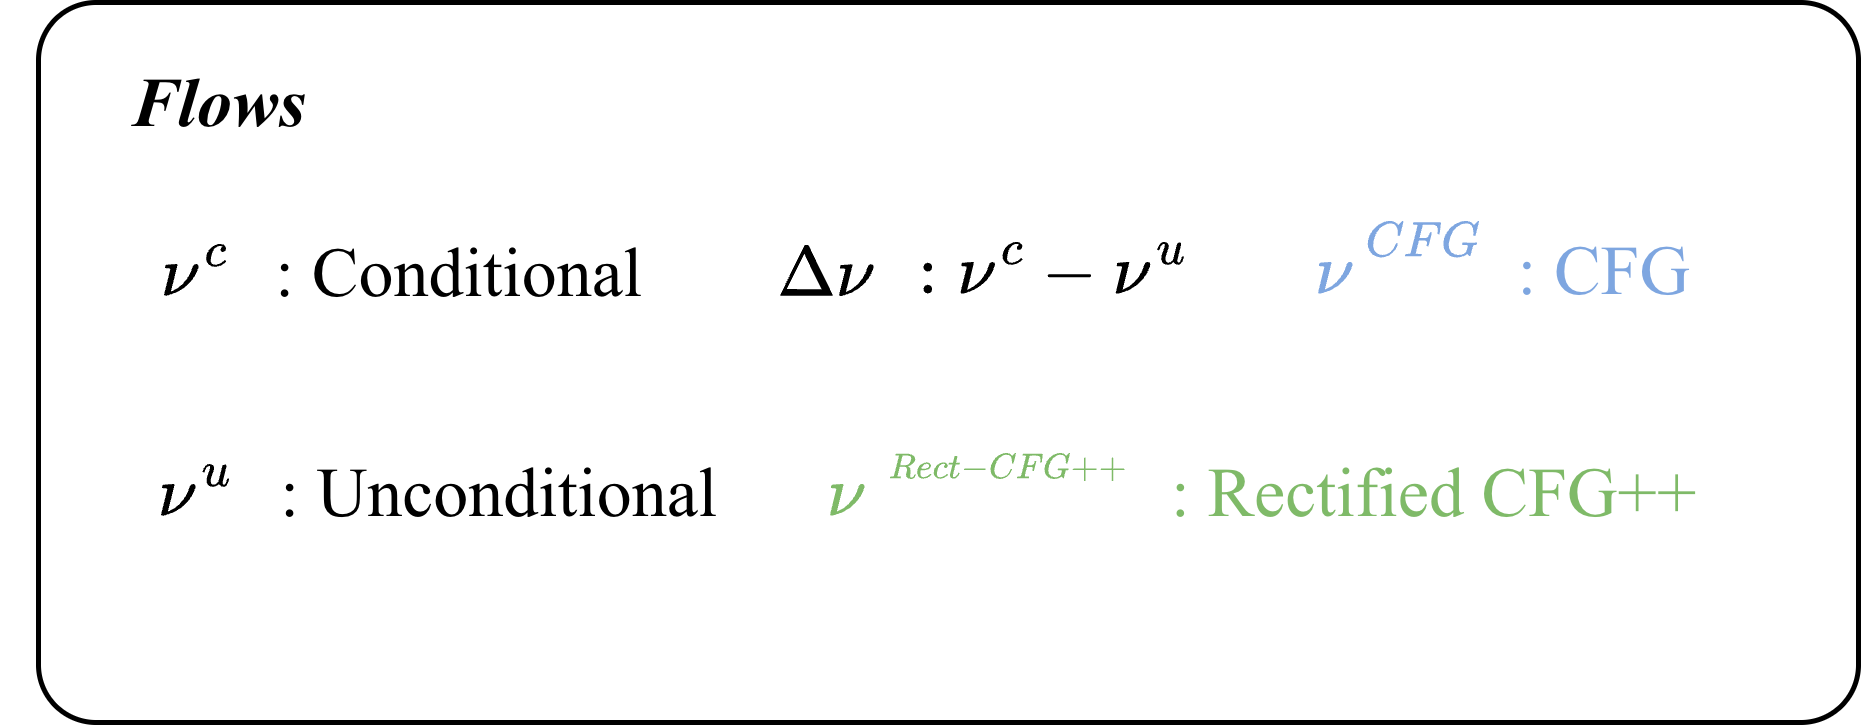
- Three flows. Blue is the Flux conditional velocity vc, red is CFG (extrapolated), green is Rectified-CFG++ (ours). Green and blue stay near the manifold while red diverges.
- The question. How do we guide the generation for better text adherence while staying on the manifold? First, what goes wrong.
CFG extrapolates off the manifold (2 of 3)
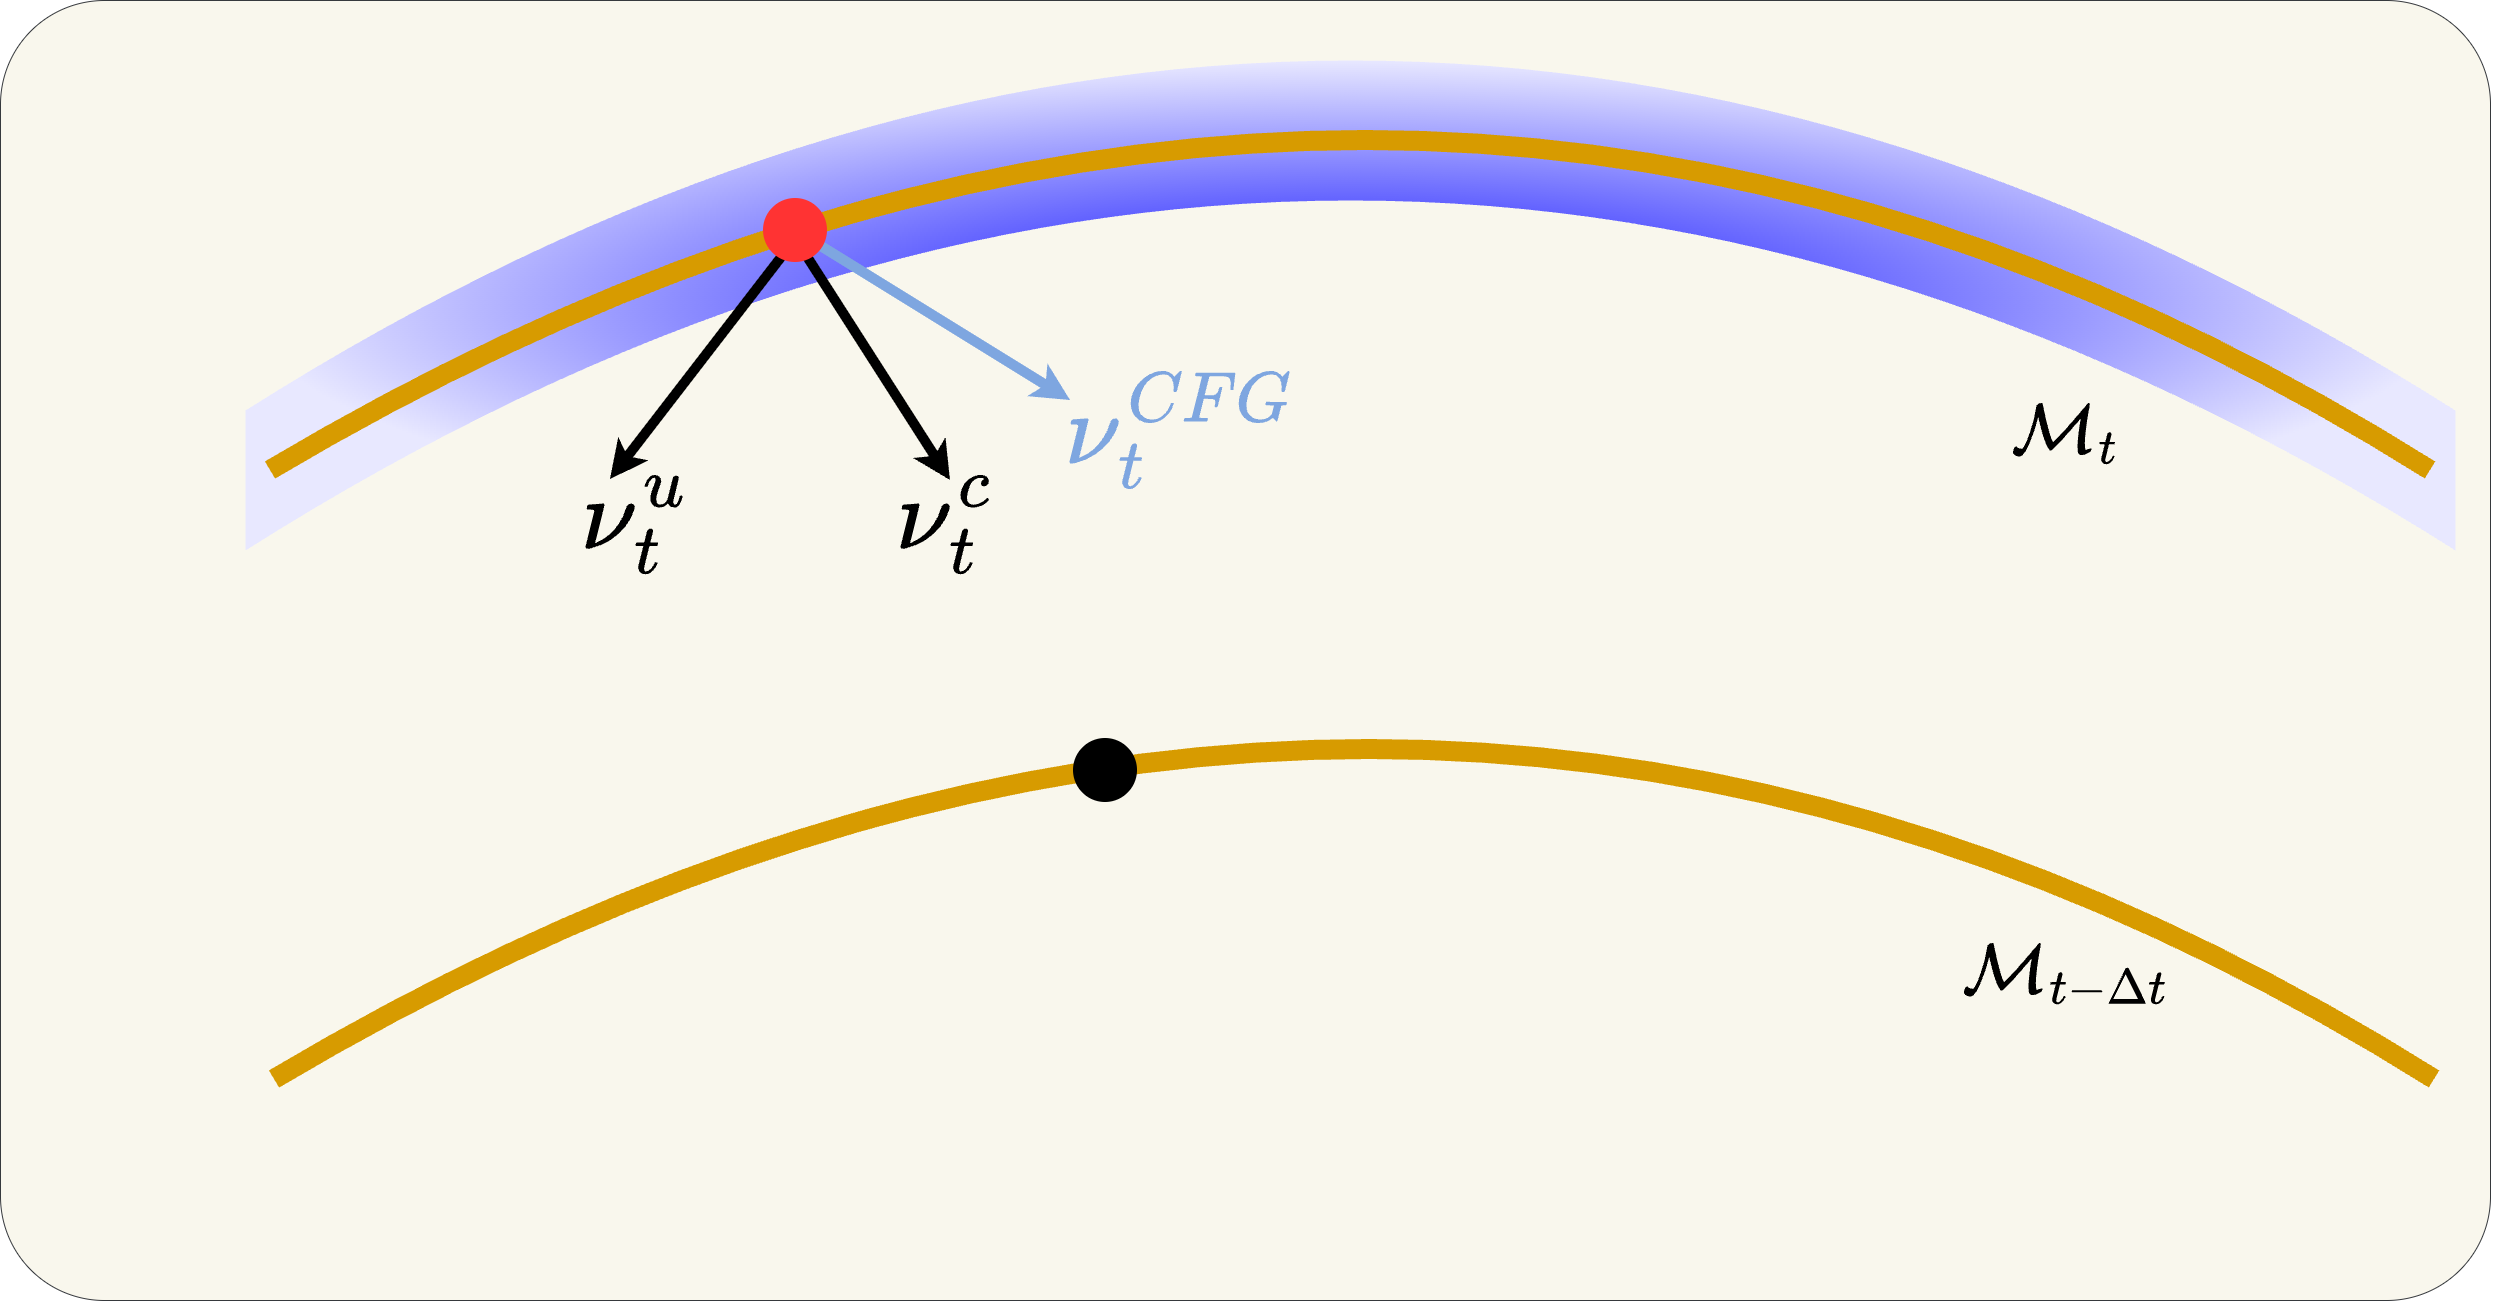
- What CFG does. Starting from the black dot on Mt, CFG computes the guided velocity v̂ω at the current point. With ω > 1 this velocity extrapolates past the conditional velocity vc.
- The tangent space violation. v̂ω does not belong to the tangent space TxtMt. The Euler step lands the sample off Mt−1, and in a deterministic ODE there is no way back.
- The compounding effect. At the next step CFG evaluates guidance at the off-manifold point, which makes the direction worse again. Errors accumulate at every step. In the final image: oversaturation, color blow-out, structural distortion.
Our predictor-corrector stays on the manifold (3 of 3)
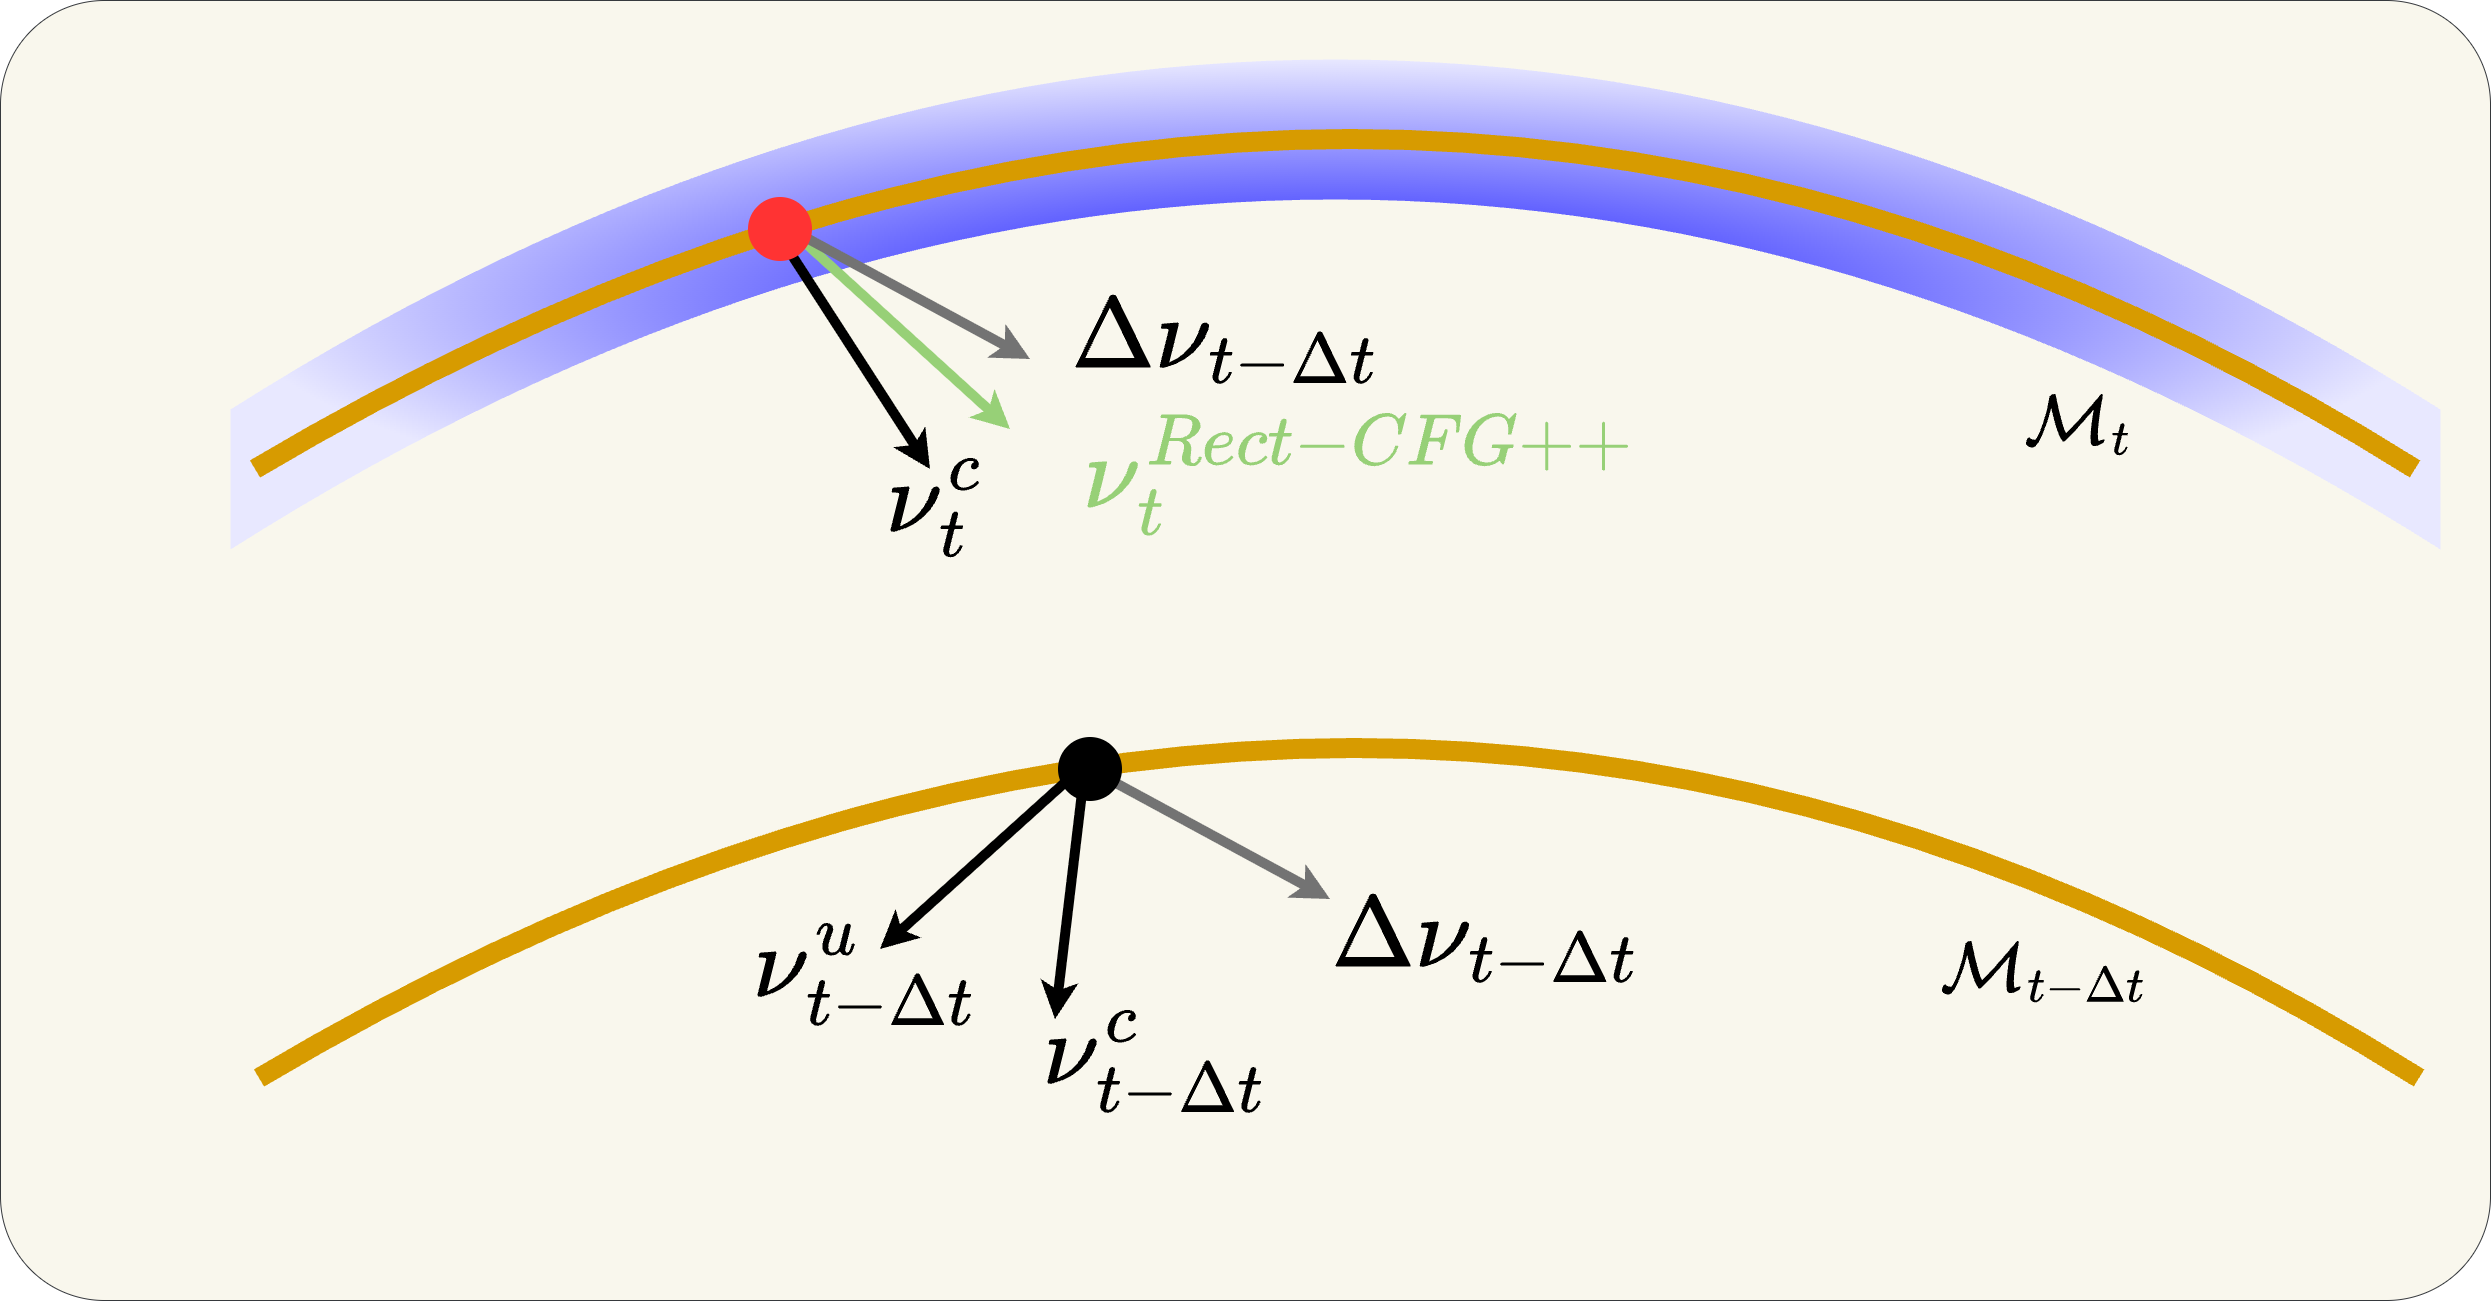
- Predict a midpoint with vc only. Take a half-step with the conditional velocity: x̃mid = xt + (Δt/2) vct. Since vc lies in the tangent space, x̃mid lands on or near Mt−Δt/2.
- Evaluate guidance at the midpoint. Compute vcmid and vumid at x̃mid. The guidance direction Δvmid = vcmid − vumid is evaluated on the manifold, so it reflects the geometry of the target manifold Mt−Δt.
- Apply a bounded interpolative correction.
α(t) = λmax(1−t)γ. The base velocity is always vc, which is on the manifold. The correction is additive and bounded, and α(t) goes to 0 near the data, so fine detail survives.
The trajectory stays in a bounded tubular neighbourhood of Mt.
Four guidance rules for the same model
Only ours avoids extrapolation altogether
Standard CFG (Ho and Salimans, 2022)
ω > 1 extrapolates past vc. Designed for SDEs with renoising. On an ODE: off-manifold drift, oversaturation, error accumulation. Constant guidance at every timestep.
CFG-Zero* (Fan et al., 2025)
Adds an optimal rescaling factor st* to align the unconditional and conditional norms. Less initial drift, but it still extrapolates (ω > 1) and has no late-step adaptation, so fine detail is still corrupted.
APG (Sadat et al., 2024)
Projects the guidance direction onto the perpendicular subspace to shrink the parallel component. Partial mitigation, but guidance is still evaluated at the current point (possibly off the manifold). No decay schedule, no formal bounds.
Rectified-CFG++ (ours)
Base is always vc (on the manifold). Guidance at the predicted midpoint x̃mid (on the manifold). α(t) = λ(1−t)γ goes to 0 near the data. Bounded, interpolative, provable.
| Property | CFG | CFG-Zero* | APG | Ours |
|---|---|---|---|---|
| Guidance type | extrapolation | extrapolation | projection | interpolation |
| Evaluated at | current xt | current xt | current xt | predicted x̃mid |
| Temporal schedule | none (constant) | none | none | α(t) decays to 0 |
| Formal guarantees | no | no | no | yes (3 results) |
| NFE per step | 2 | 2 | 2 | 3 |
A 2D toy example
CFG drifts off the support, ours stays on the manifold
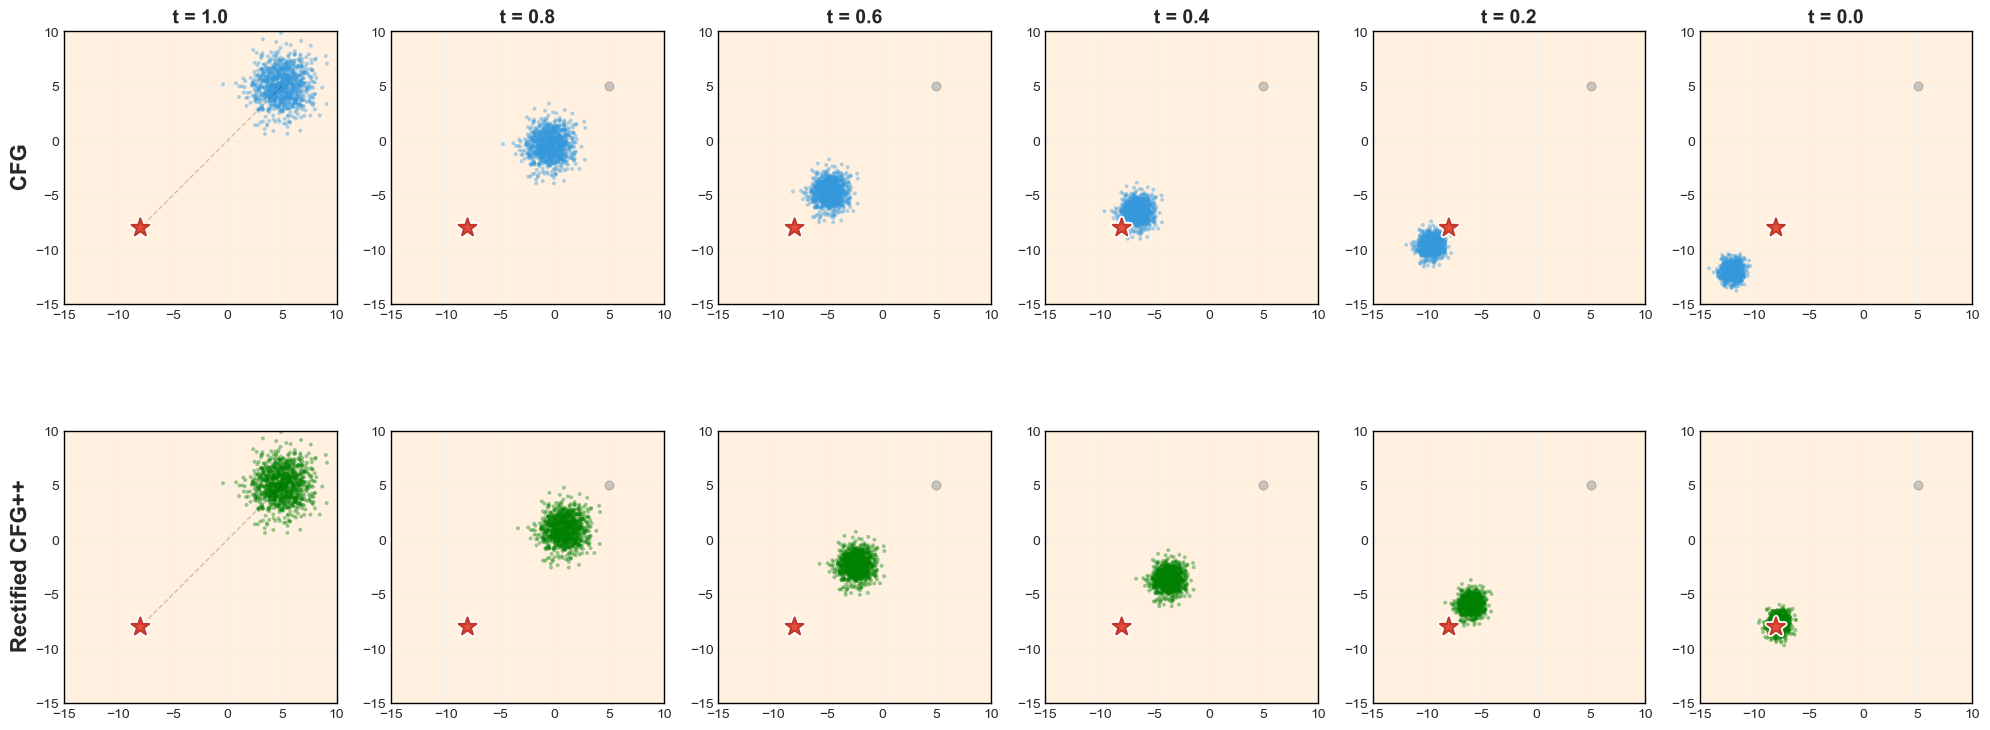
200 trajectories on a 2D mixed Gaussian. Top: CFG (blue) drifts off the support. Bottom: ours (green) moves smoothly along the manifold.
CFG (top). Trajectories overshoot at first and leave the learned transport manifold. Sharp late corrections pull the samples back, but the damage is done. The final distribution is noisy and off-center.
Rectified-CFG++ (bottom). Smooth convergence throughout. The predictor anchors each step on the flow field and the corrector applies bounded guidance. Samples arrive at the target tightly concentrated, with no drift and no sharp corrections.
Same prompt, same seed, three guidance strategies on Flux
Flux-dev, same prompt, same seed. Left: no guidance (baseline). Center: CFG, ω = 3.5. Right: Rectified-CFG++, λ = 0.5. Ours has sharper detail, faithful color and no rainbow artifacts.
Rectified-CFG++ on random prompts
All images from Rectified-CFG++ on Flux-dev. Random prompts from MS-COCO and Pick-a-Pic, no cherry-picking.
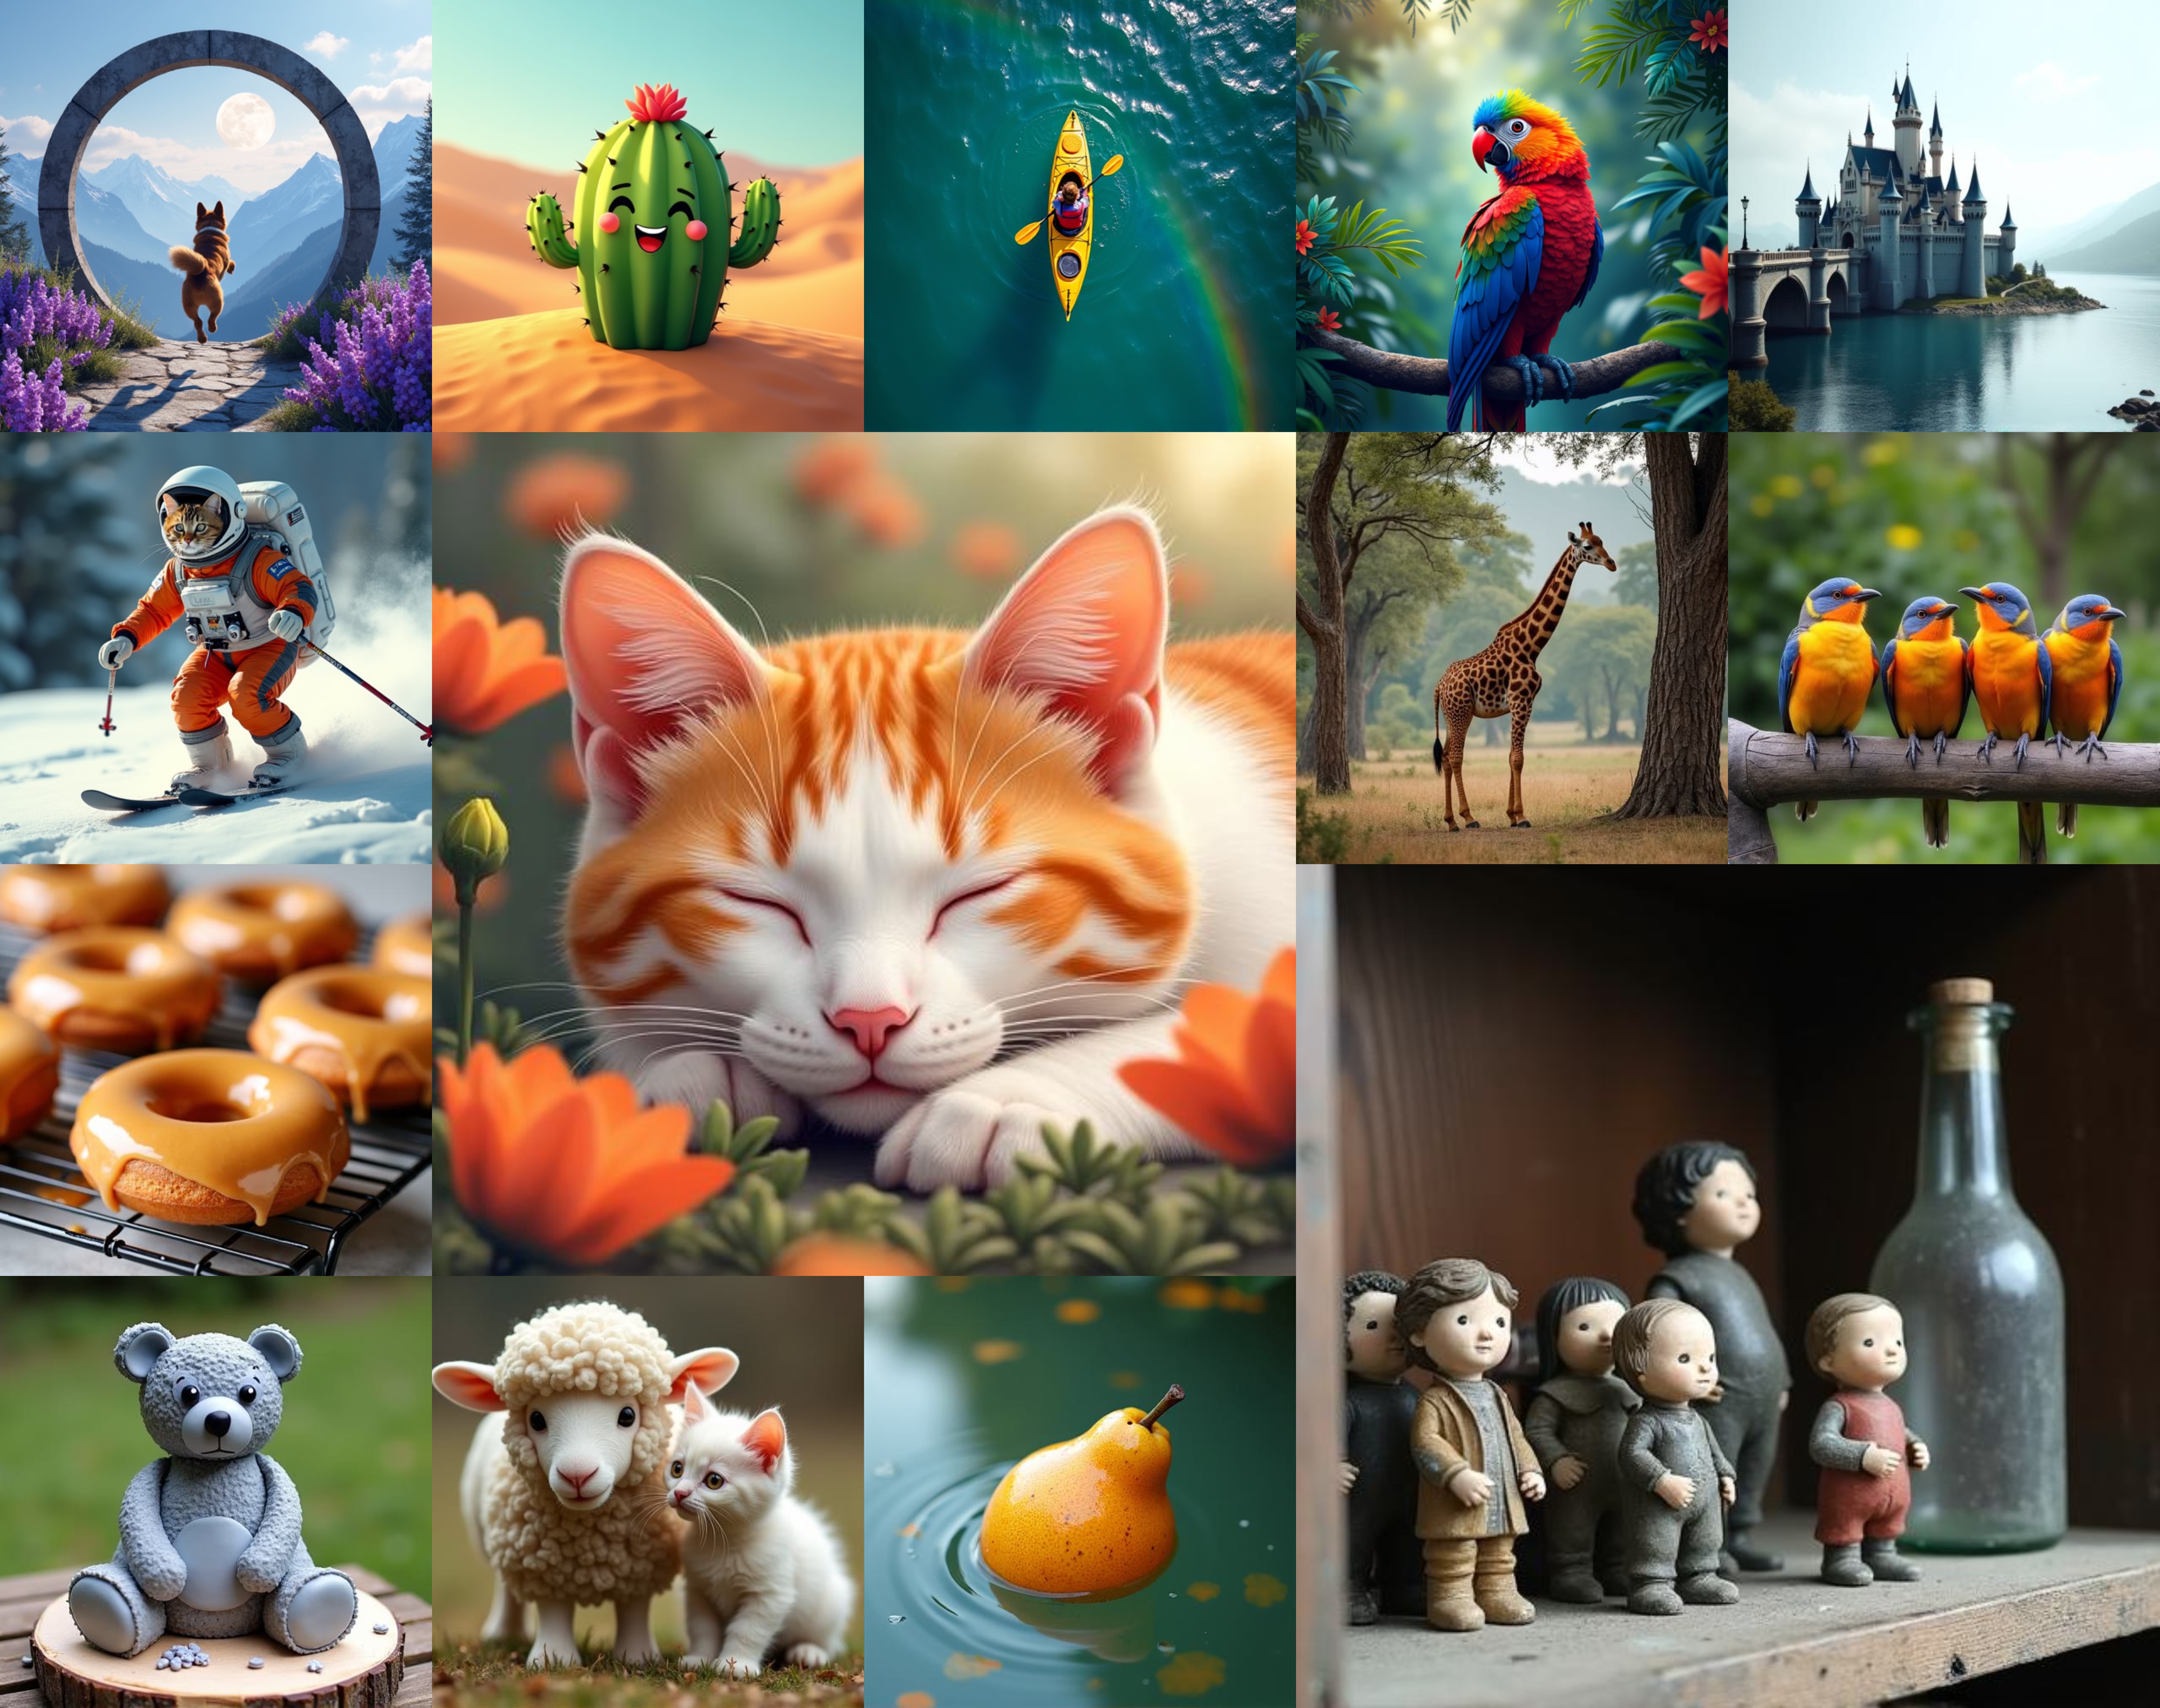
Photorealistic scenes. Landscapes, portraits, food, architecture. Natural lighting, correct shadows, no oversaturation. Staying on the manifold preserves the photoreal distribution Flux was trained on.
Artistic and stylized. Oil paintings, digital art, fantasy scenes. Style transfer works because α(t) allows strong guidance early (global style) while preserving fine brush strokes late.
Text and composition. Signage, book titles, multi-object scenes, the hardest category for any guidance method. α(t) going to 0 at late steps preserves pixel-precise text and spatial relationships.
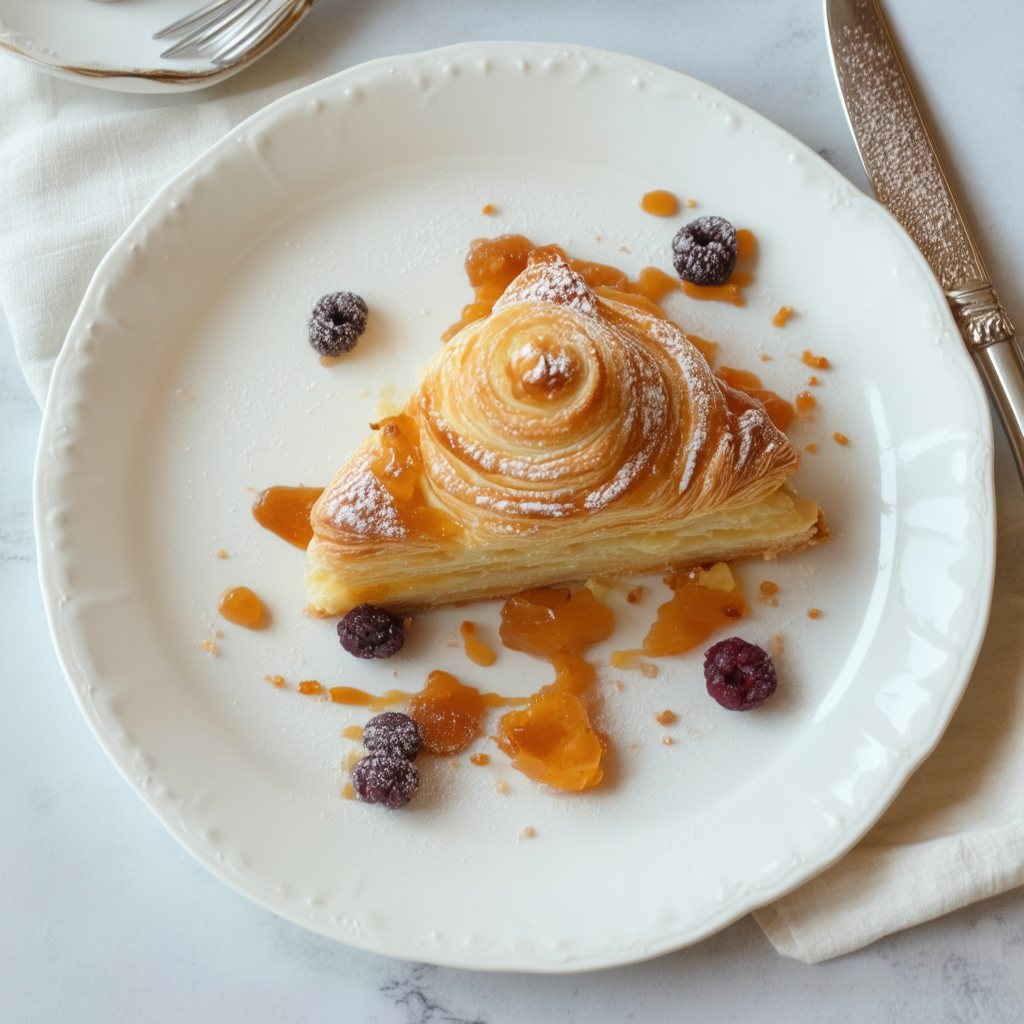
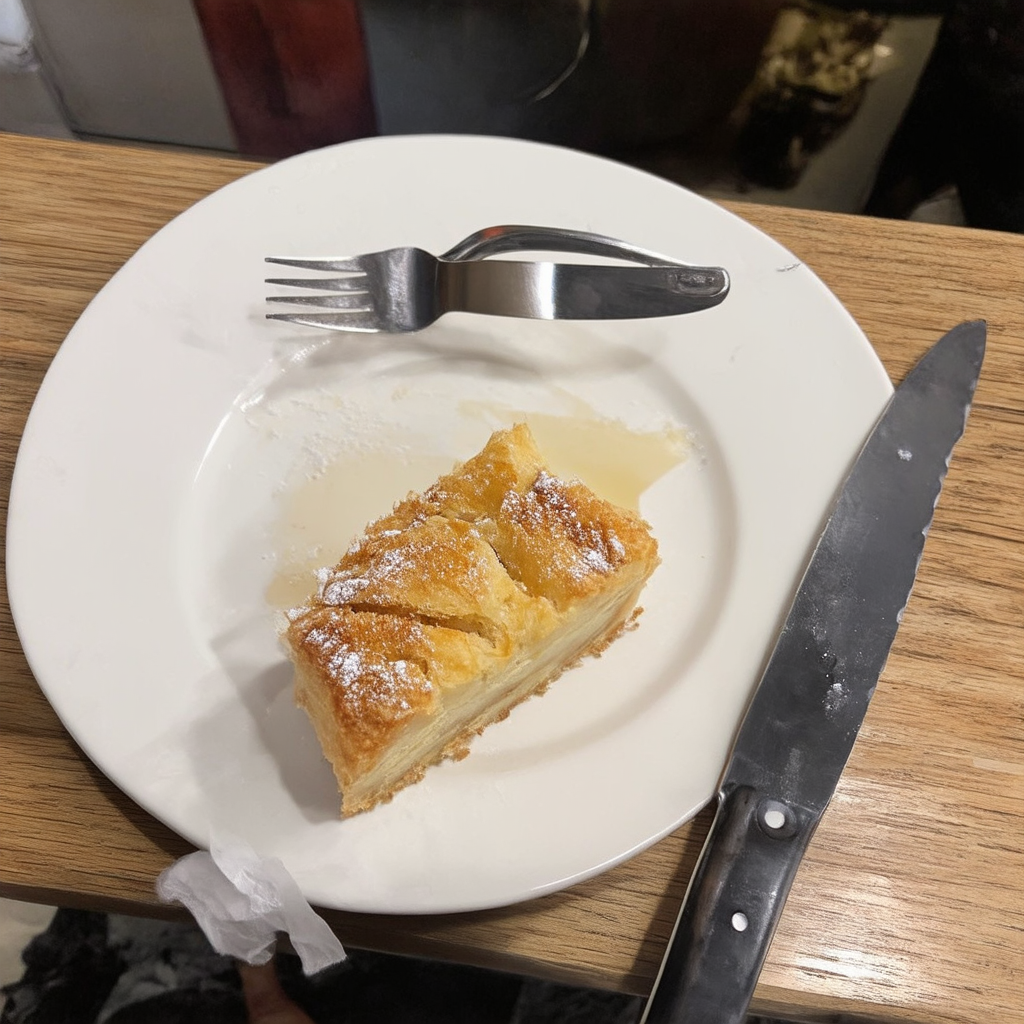
Four guidance methods on SD3.5, same prompt and seed
CFG, ω = 3.5
CFG-Zero*
APG
Ours, λ = 6
CFG
CFG
Ours
Ours
The same on SD3 and Lumina-Next
SD3, CFG
SD3, ours
SD3, CFG
SD3, ours
Lumina, CFG
Lumina, ours
Lumina, CFG
Lumina, ours
A drop-in replacement across rectified flow models. No retraining, no architecture changes.
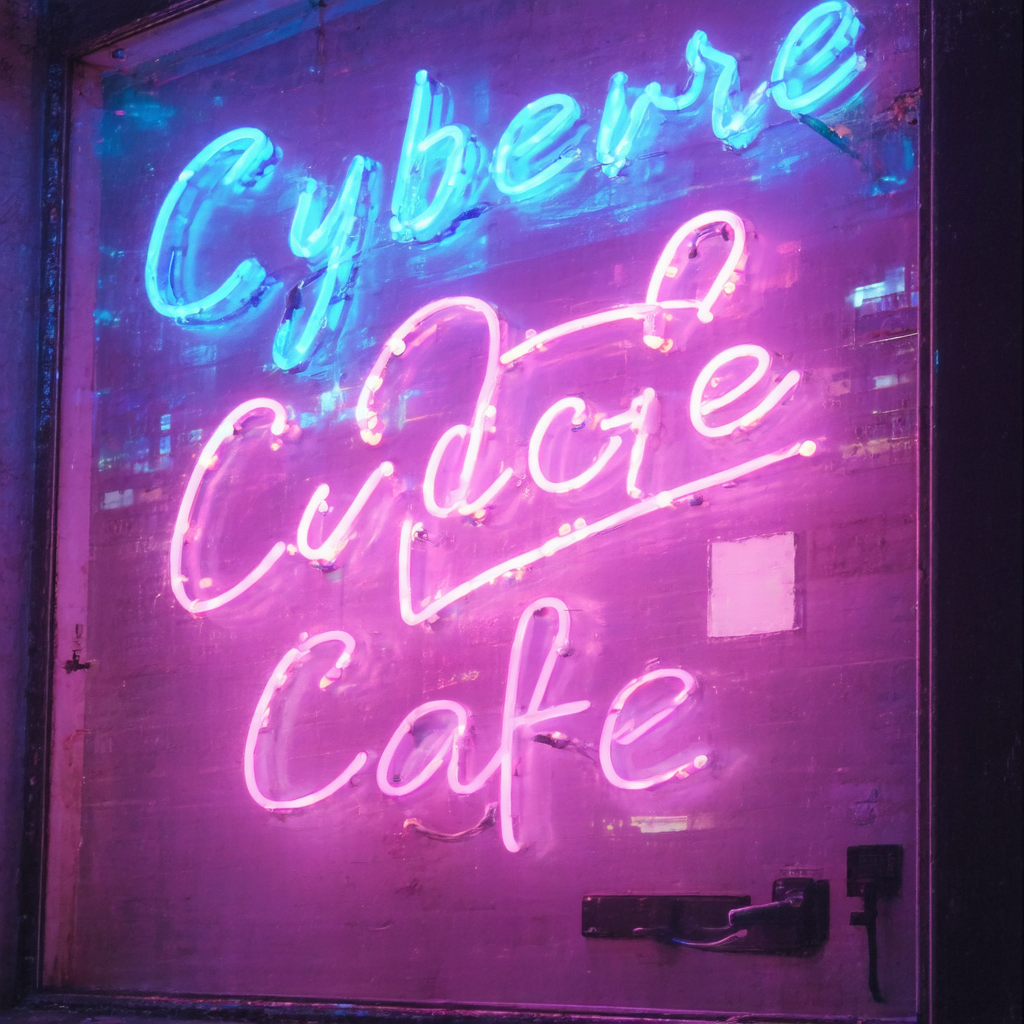
Text rendering, a neon street sign
CFG
Rectified-CFG++
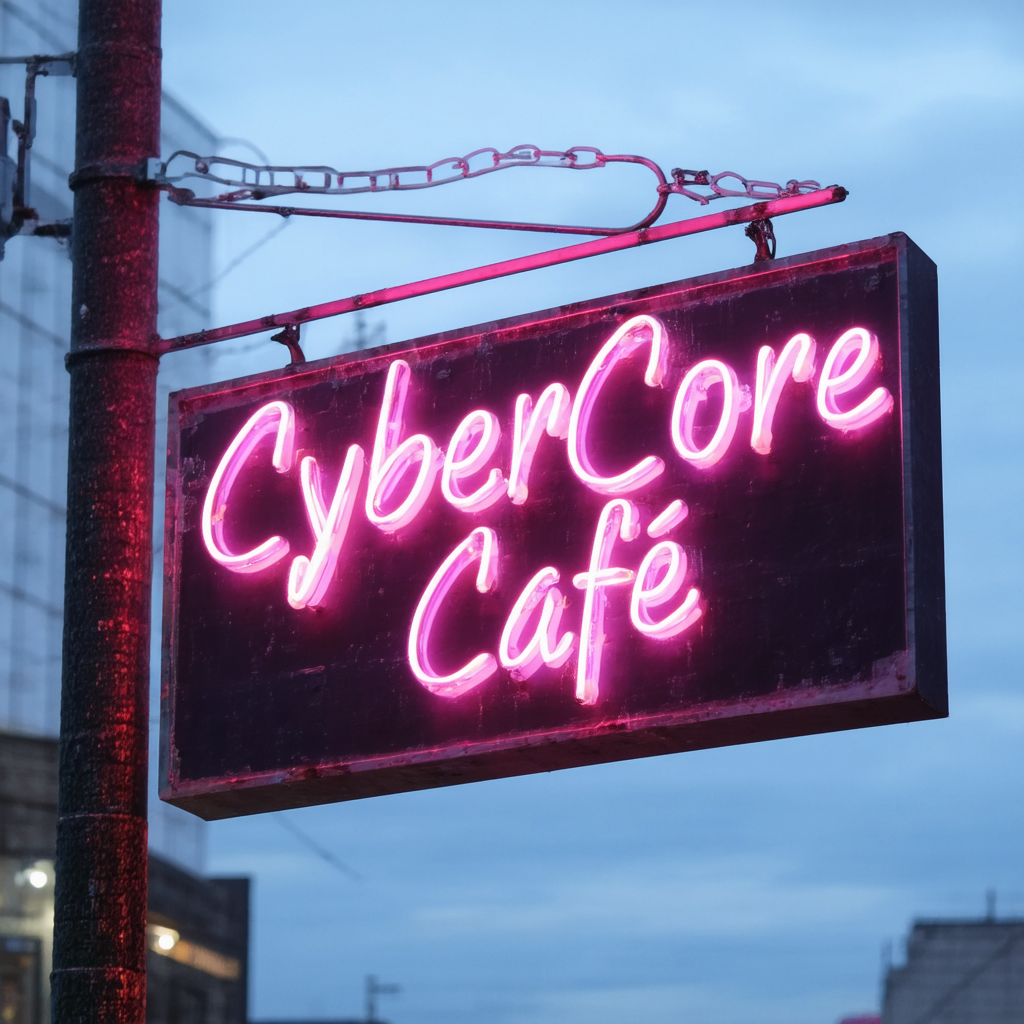
Prompt: "A neon street sign that says 'CyberCore Cafe', glowing in magenta and blue."
CFG garbles the neon letters into "Cyberre Cidie Cafe". The glow halos and letter boundaries bleed together. Ours renders each letter distinctly with clean separation between the neon glows.
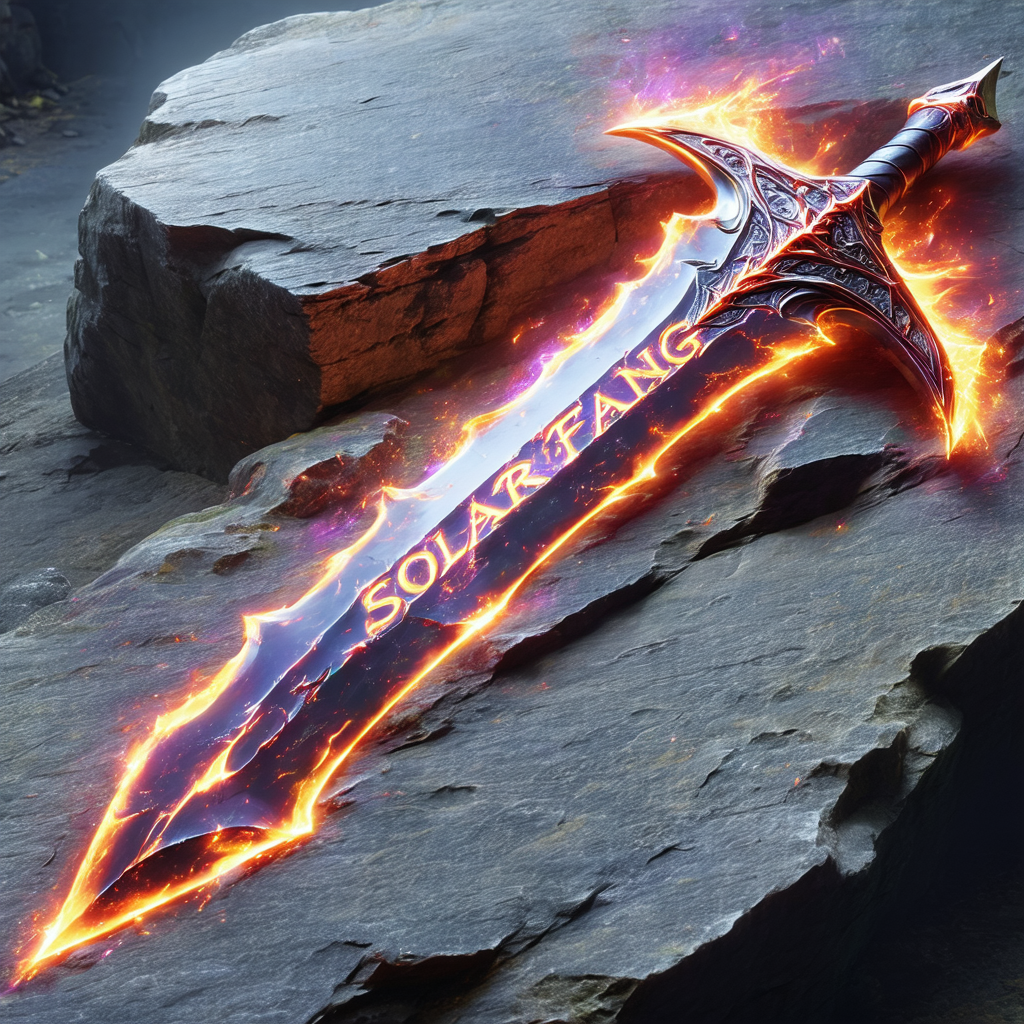
Text rendering, headlines and inscriptions
CFG
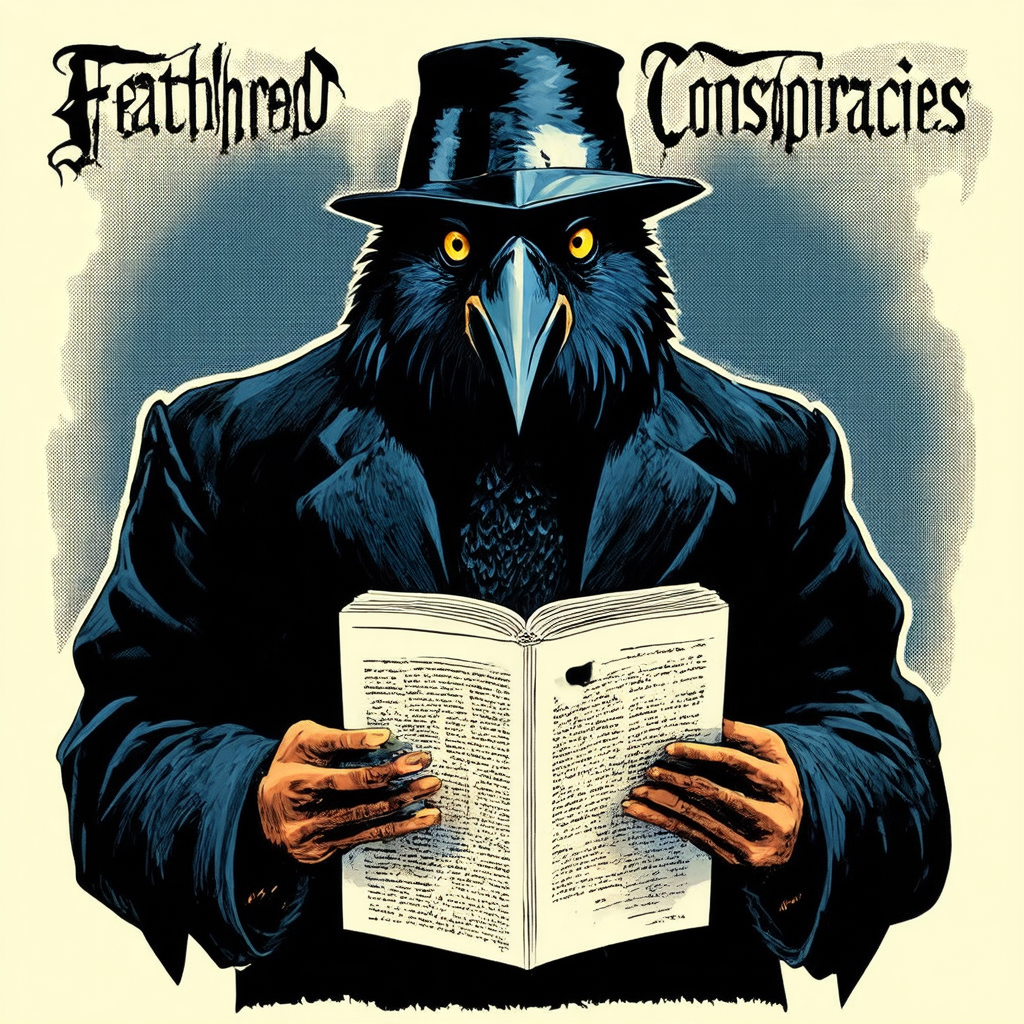
Ours
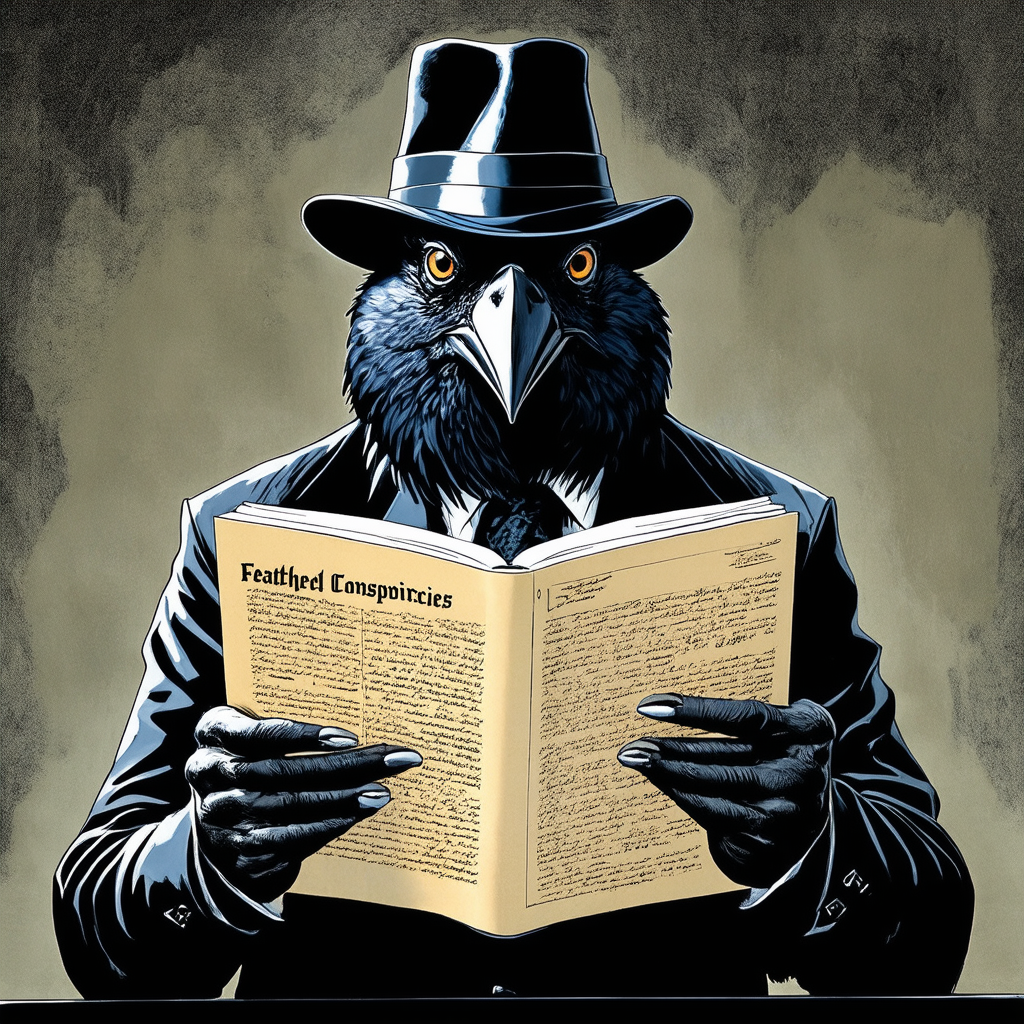
CFG
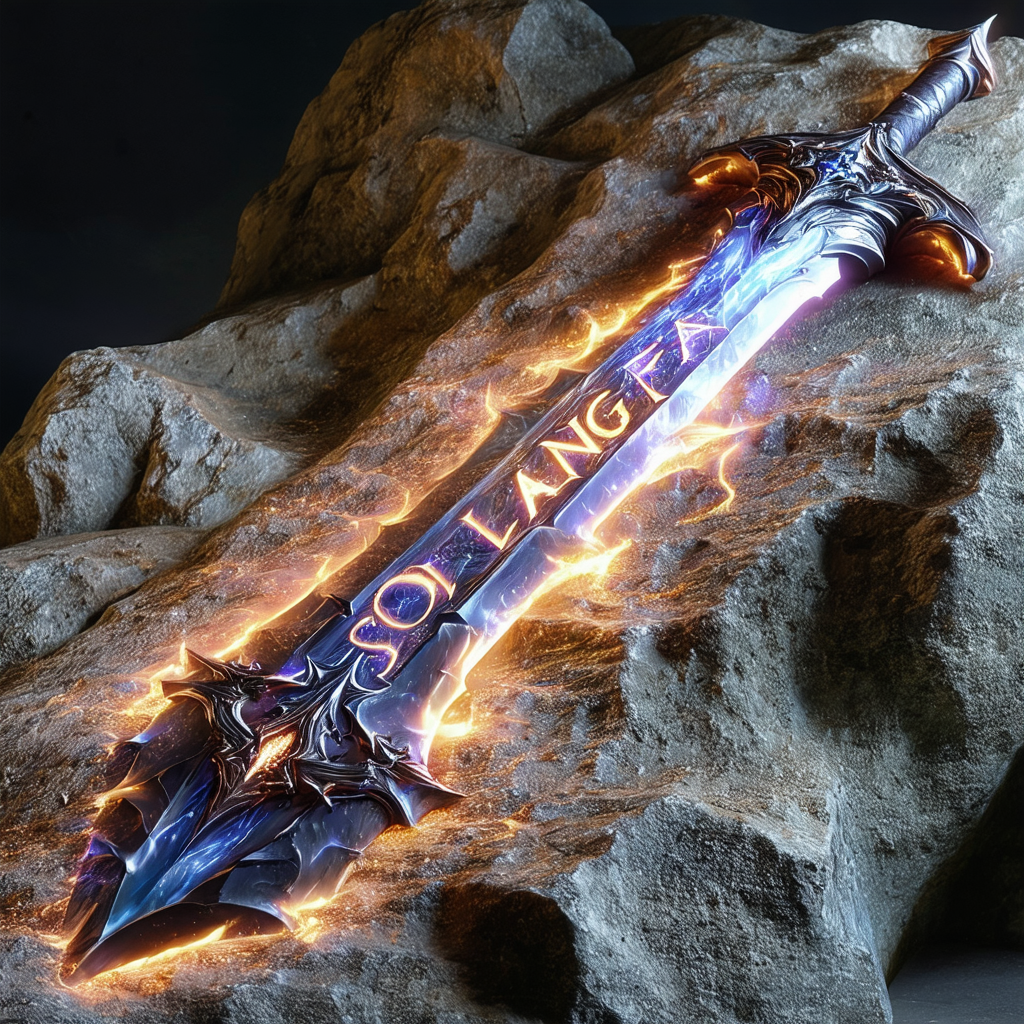
Ours
Prompt: "A crow detective reading a paper titled 'Feathered Conspiracies', headline in bold noir font."
Prompt: "A magical sword embedded in stone, with the name 'SOLARFANG' etched along its blade in glowing runes."
CFG turns "Feathered Conspiracies" into "Feathhrad Conspiracies" and SOLARFANG into garbled runes. Ours renders both headlines correctly with proper typography, even on surfaces like aged paper and glowing stone.
Text rendering, a slide and a scroll
CFG
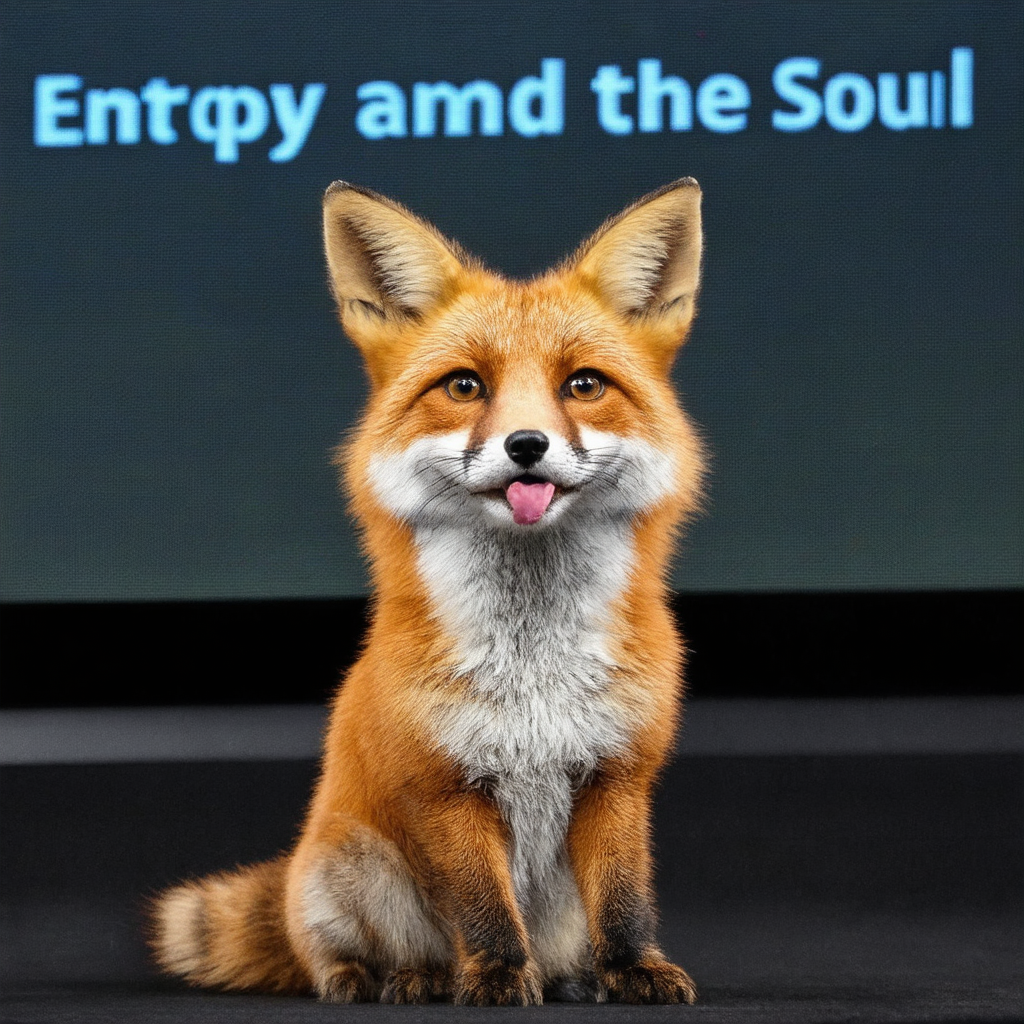
Ours
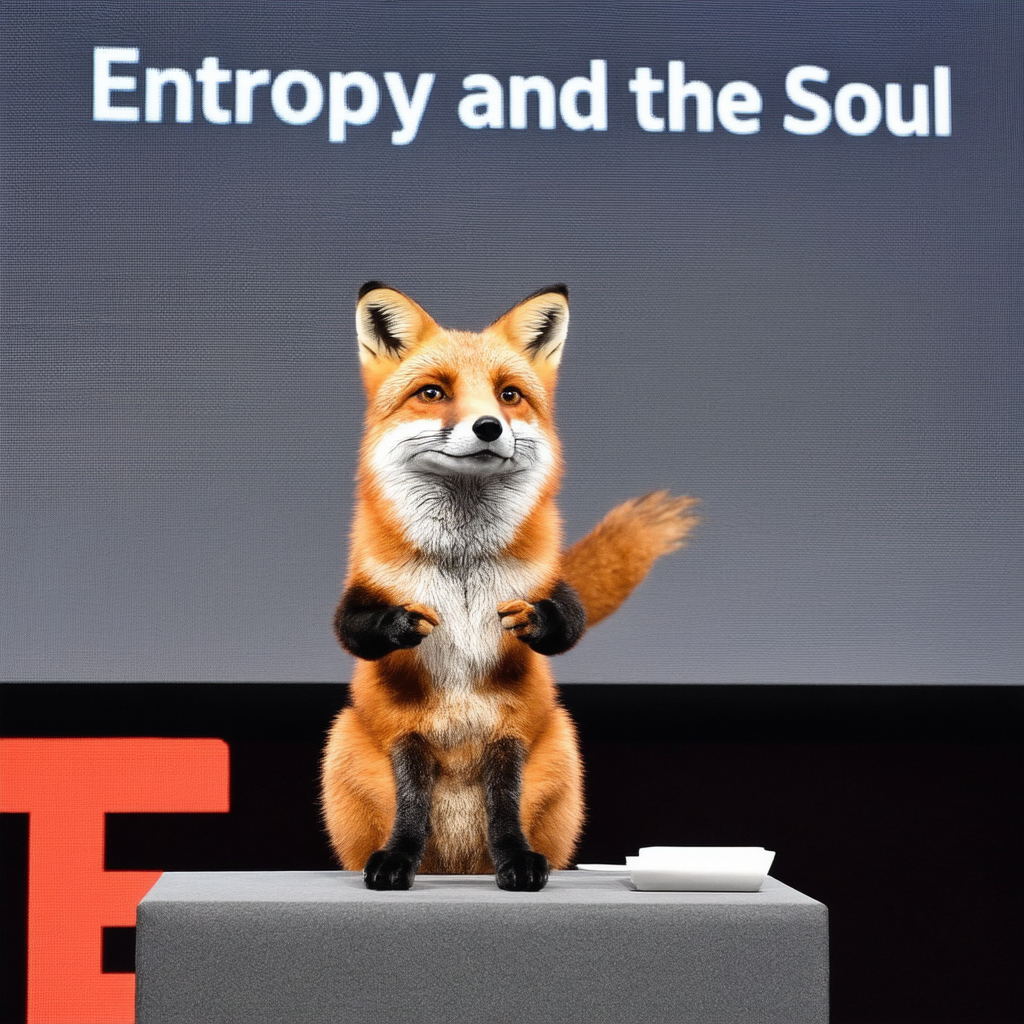
CFG
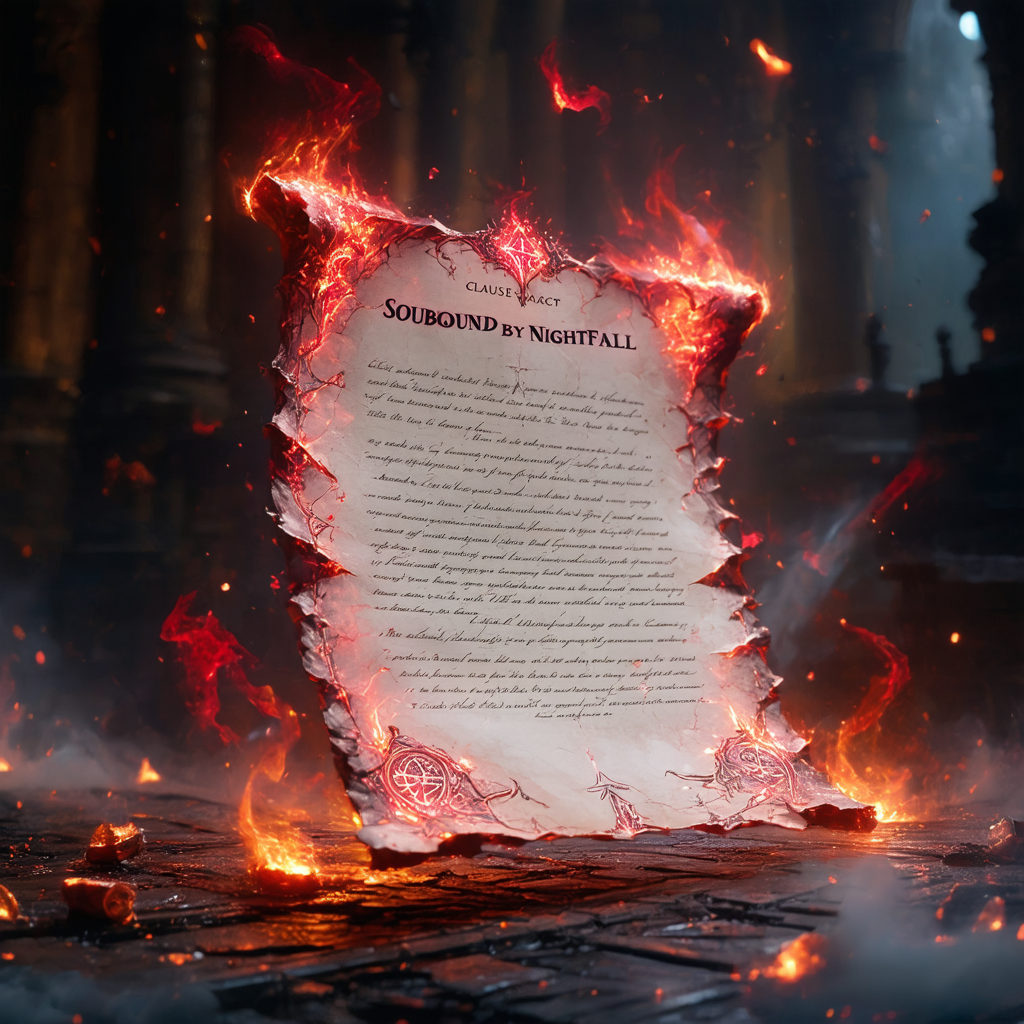
Ours
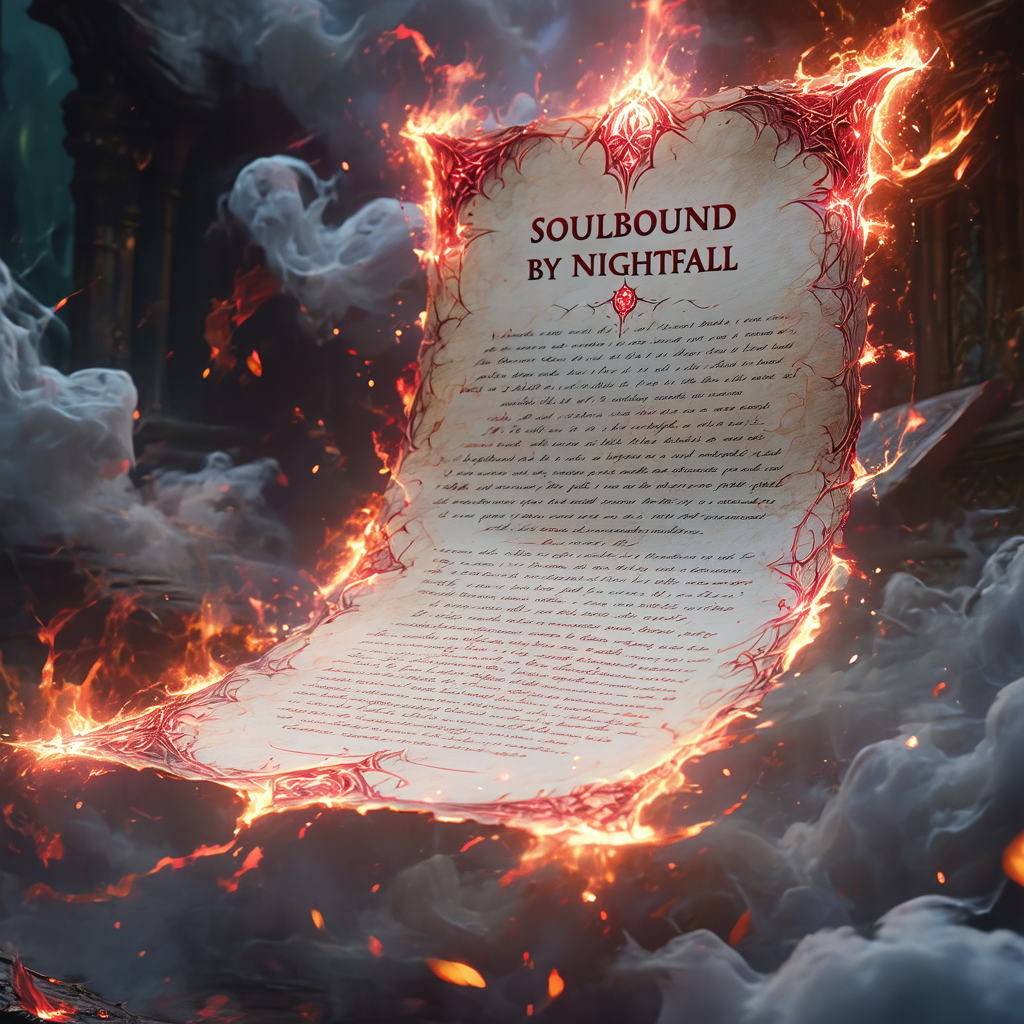
Prompt: "A fox giving a TED talk, slide behind reads 'Entropy and the Soul'."
Prompt: "A burning scroll with the title 'Soulbound by Nightfall' in ornate calligraphy."
CFG turns "Entropy and the Soul" into "Entφy amd the Soul", and the scroll title is barely readable. Ours gives clean title text on both the presentation screen and the burning scroll; zero guidance at the final steps preserves the fine detail.
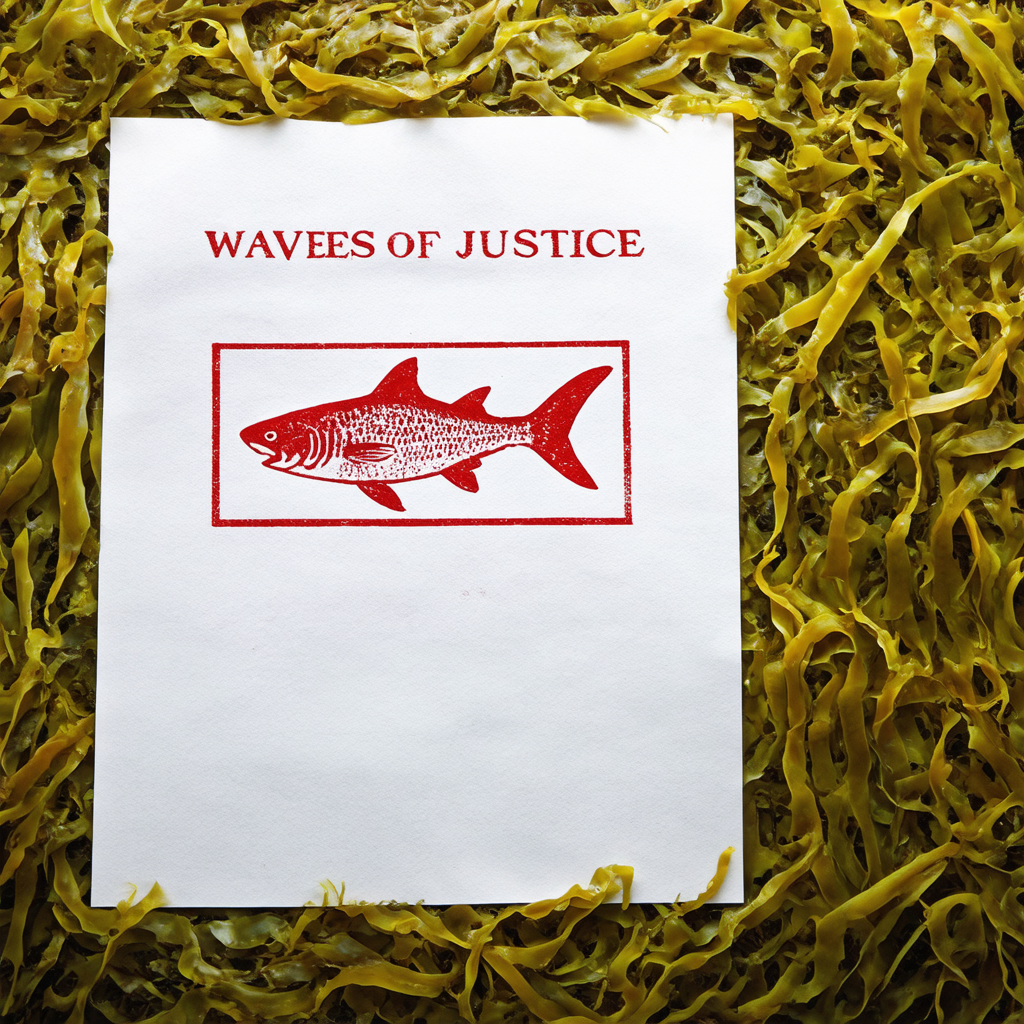
Text rendering, carved and printed
CFG
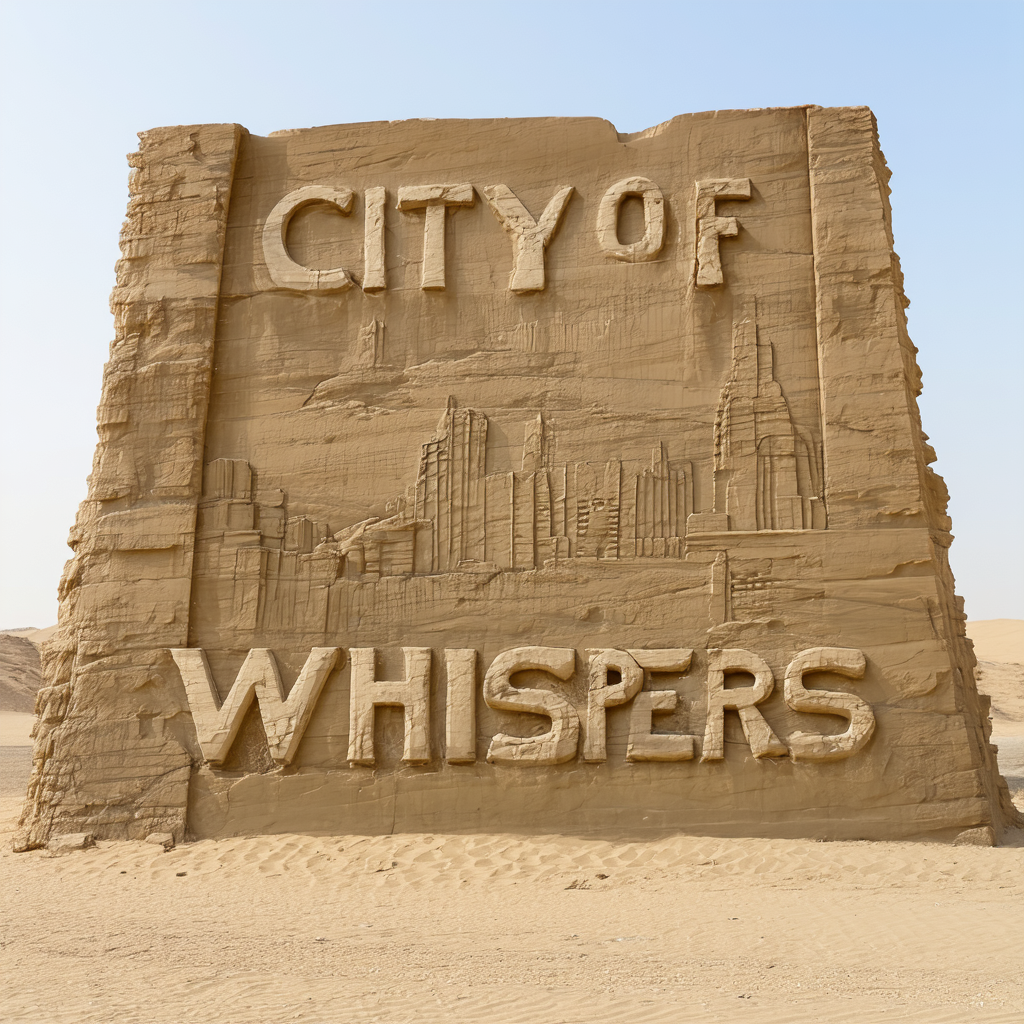
Ours
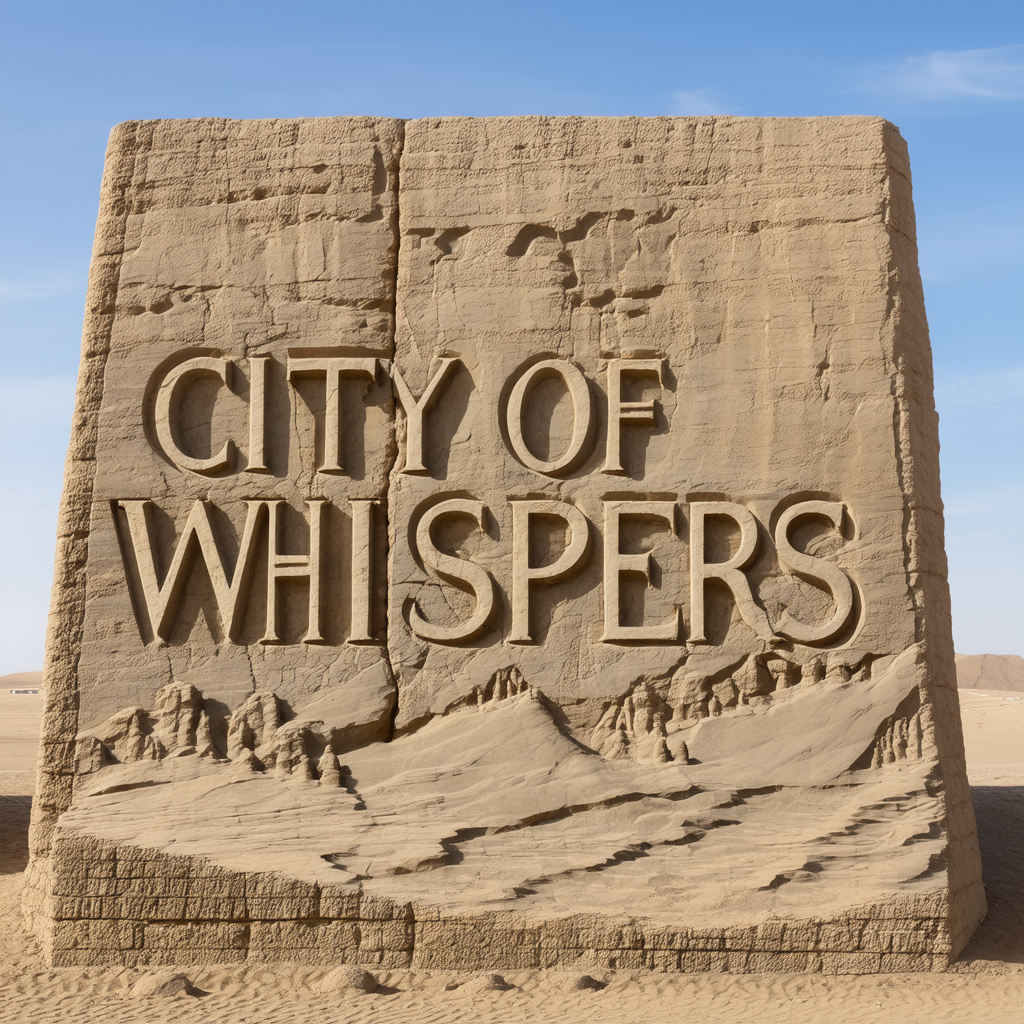
CFG
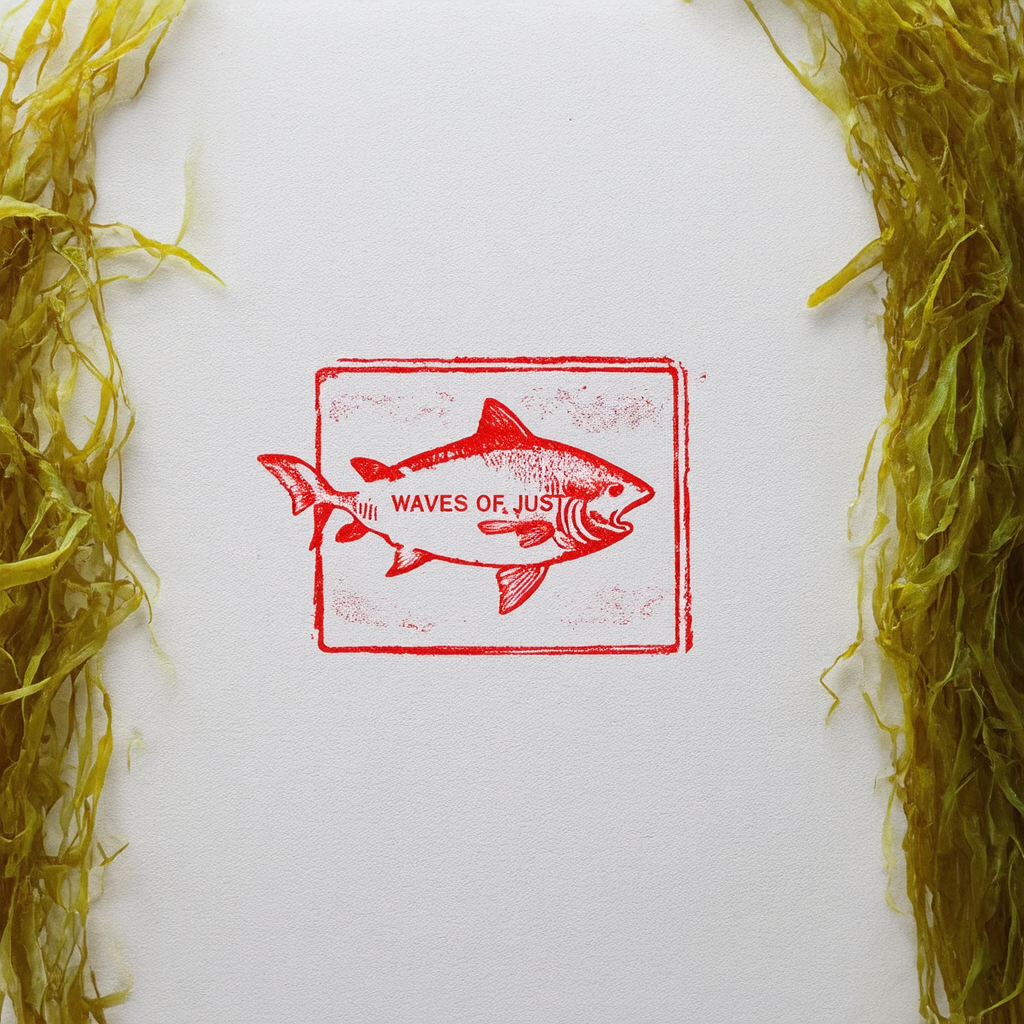
Ours
Prompt: "A desert gate carved in sandstone reading 'CITY OF WHISPERS'."
Prompt: "A Japanese fish stamp print with 'WAVES OF JUSTICE' in red ink."
The pattern. Across neon, carved stone, ink stamps, calligraphy and digital displays, Rectified-CFG++ keeps the text legible. The adaptive schedule α(t) going to 0 is the mechanism: no guidance perturbation while fine detail is resolved.
Text legibility on SD3.5, the full gallery
Each pair: CFG on the left, Rectified-CFG++ on the right
CFG
Ours
CFG
Ours
CFG
Ours
CFG
Ours
CFG
Ours
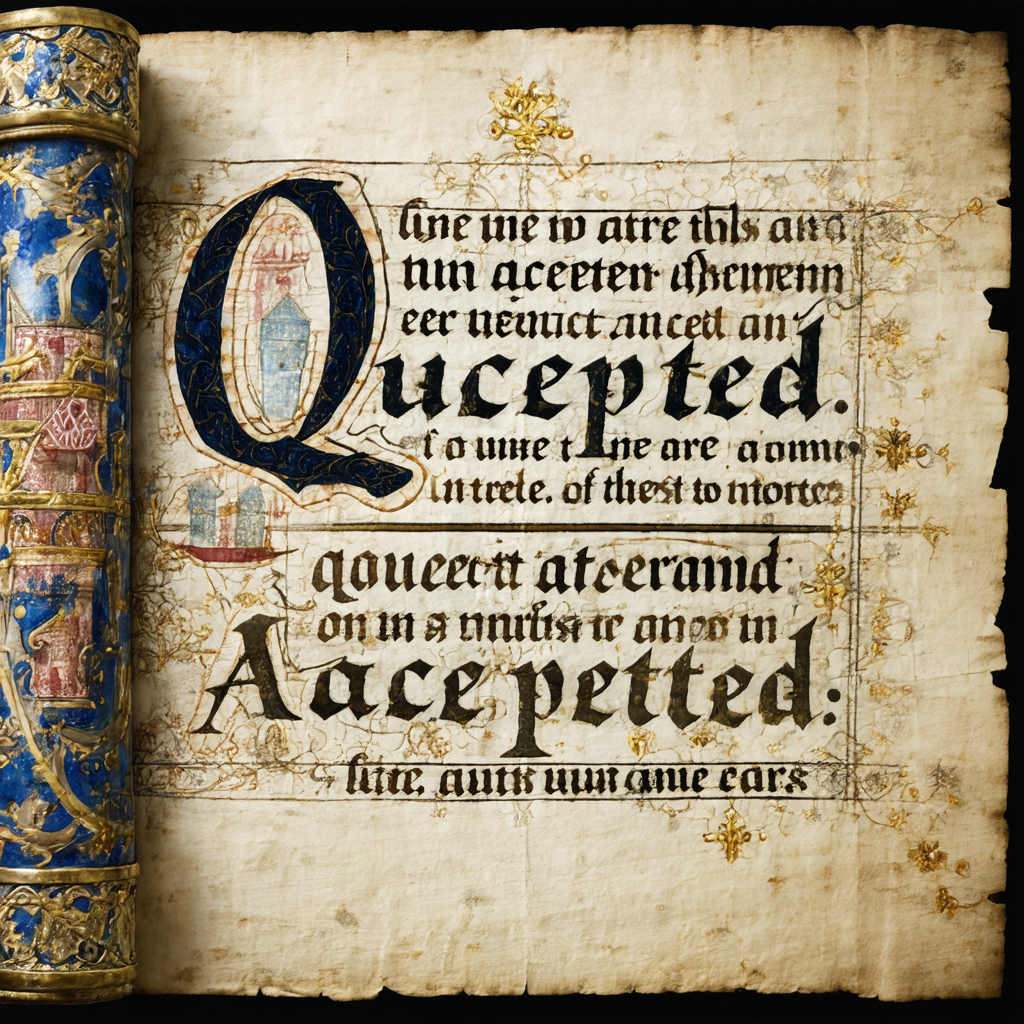
CFG
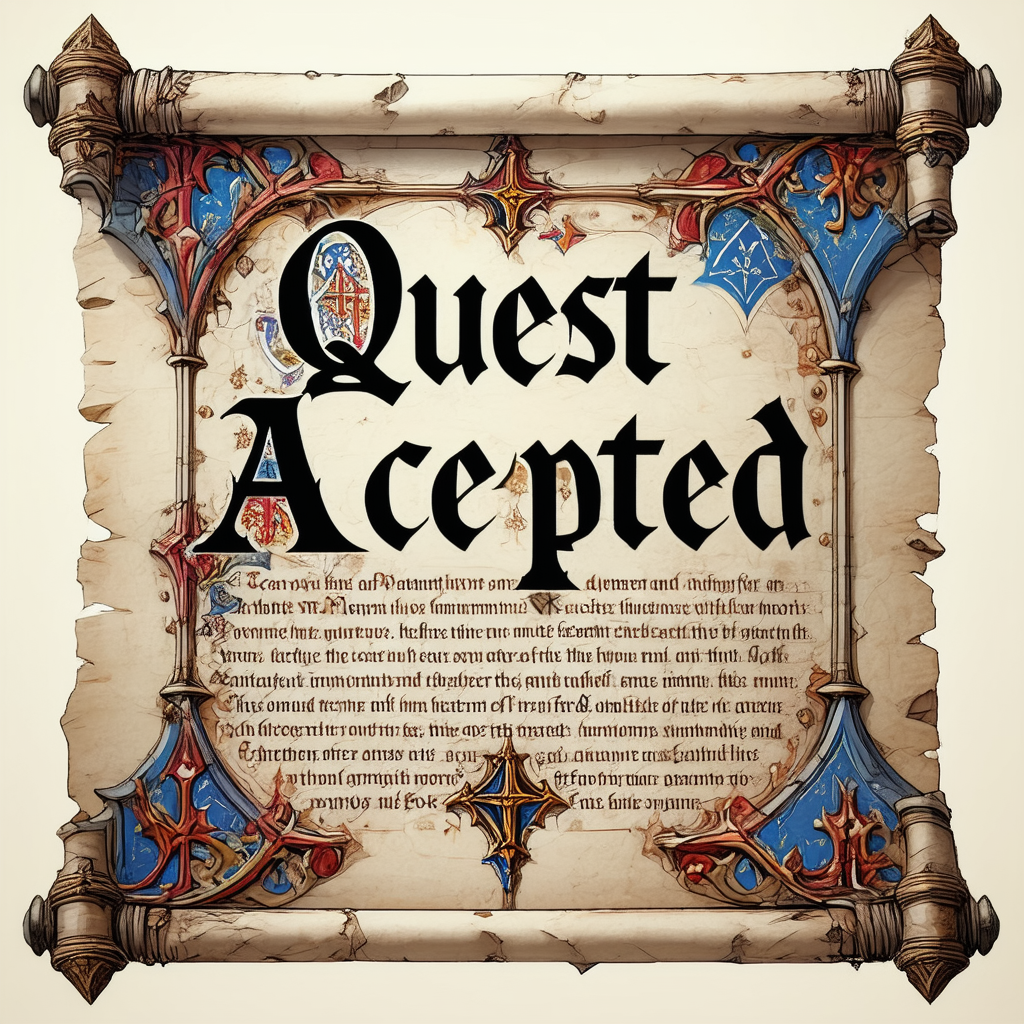
Ours
CFG
Ours
CFG
Ours
Legible text on every prompt. The adaptive schedule α(t) is what does it.
Sweeping the guidance scale
CFG collapses at high guidance, ours stays flat
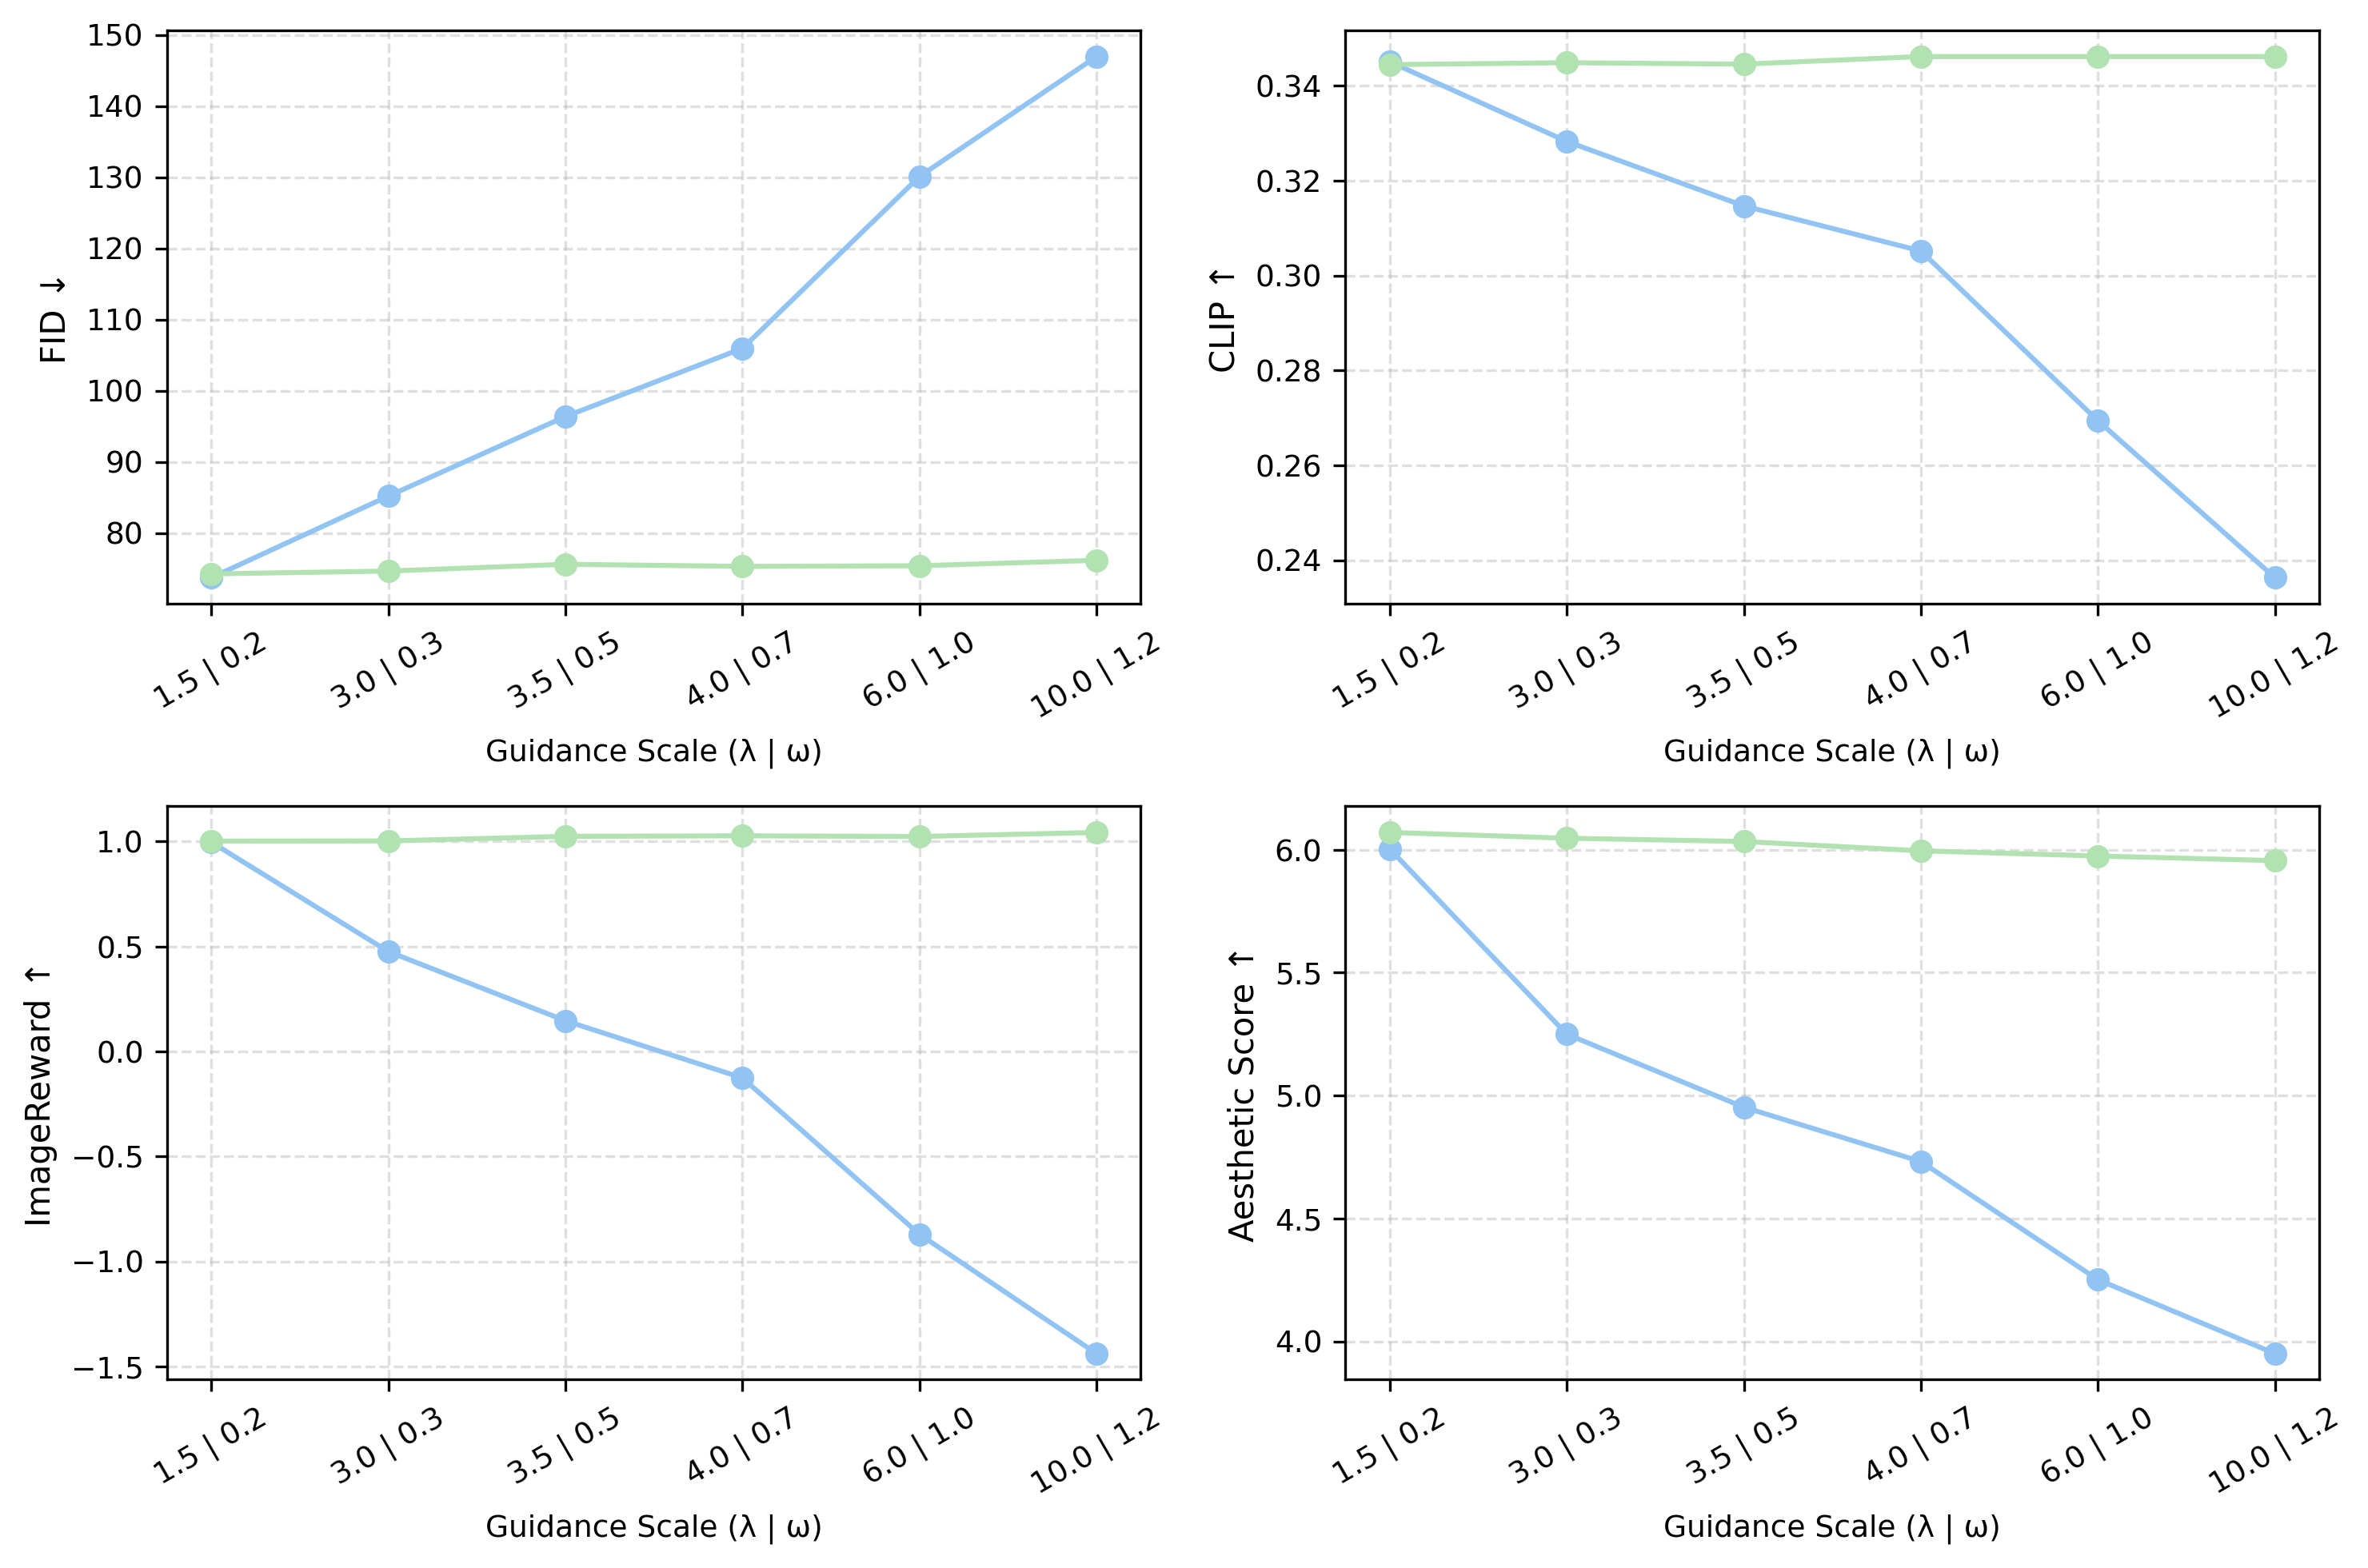
x-axis: guidance scale (λ for ours, ω for CFG). y-axis: FID ↓, CLIP ↑, ImageReward ↑, Aesthetic ↑. Blue is CFG, green is ours.
CFG (blue curves). FID explodes from 77 to 148 at ω = 10. ImageReward collapses from 1.0 to −1.5. CLIP drops 30%, Aesthetic drops 35%. Catastrophic failure at high guidance.
Rectified-CFG++ (green curves). FID stays at 75, flat. ImageReward goes from 1.0 to 0.95. CLIP and Aesthetic stay stable. Graceful degradation at every scale.
Why this matters. CFG needs careful per-model tuning of ω to avoid collapse. Rectified-CFG++ holds across a 50× range of λ with no hyperparameter sensitivity. One setting works everywhere.